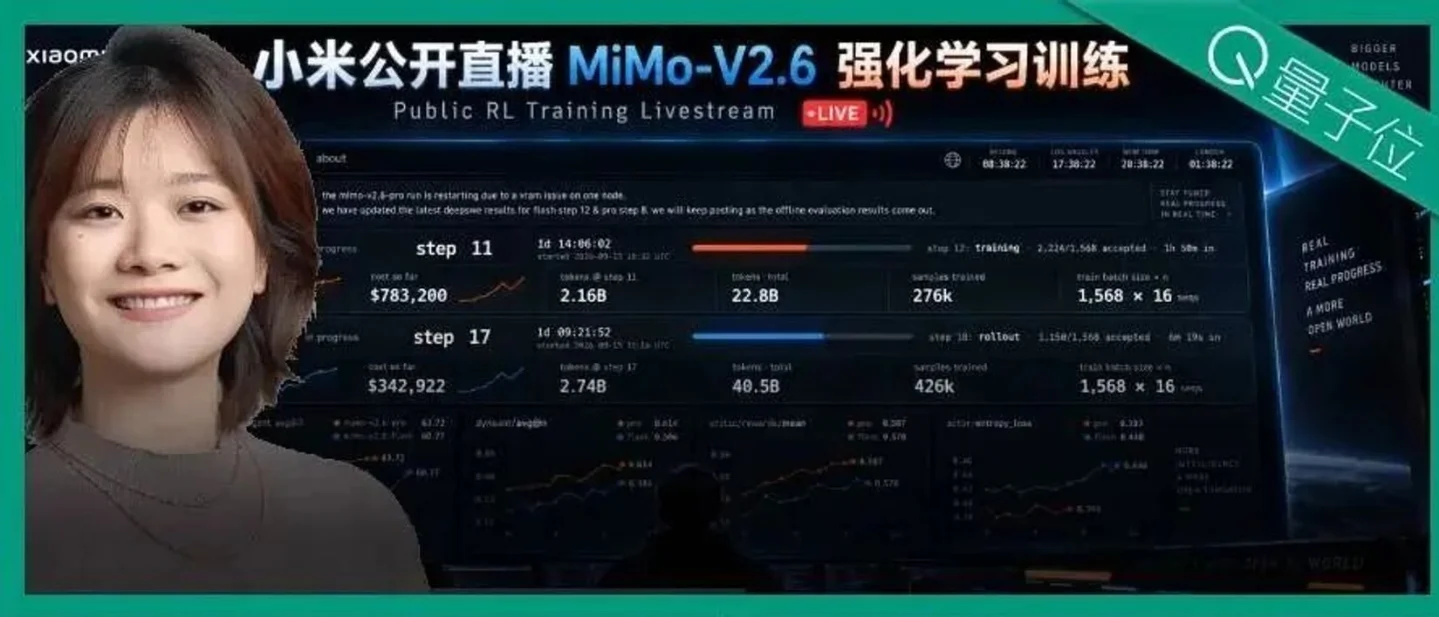
罗福莉沉寂半年官宣小米强化学习!直播新模型训练过程,一小时烧3万美元
量子位报道小米 MiMo-V2.6 的强化学习训练过程首次公开直播:Pro 与 Flash 两款模型的成本、步数与评测曲线实时可查,罗福莉说明团队在计算量、环境与评分三个方向上扩展 RL 规模。

转载说明:本文转载自微信公众号「量子位」官方账号(biz_id:MzIzNjc1NzUzMw),原文发表于 2026 年 9 月 17 日 08:56,作者署名「梦晨 发自 凹非寺 量子位 | 公众号 QbitAI」。原文链接:[量子位微信公众号原文](http://mp.weixin.qq.com/s?__biz=MzIzNjc1NzUzMw&mid=2247923967&idx=1&sn=f17eab60e3054b38931194ad3766a2a4),同题文章另见量子位官网 qbitai.com。
9 月 17 日,小米 MiMo 大模型团队负责人罗福莉在 X 上公开了 MiMo-V2.6 的强化学习训练进展,并给出一个实时看板,把这一轮 RL 训练的过程摆到了外面 1。
从 Pro 模型开始训练算起 36 小时,两款模型已经花了超过 108 万美元,平均每小时 3 万美元 1。原文的观察是,开放权重、开放训练代码、开放训练数据都见过,把训练过程本身开放出来还是头一次。
打开看板,钱、步数和故障都写在上面
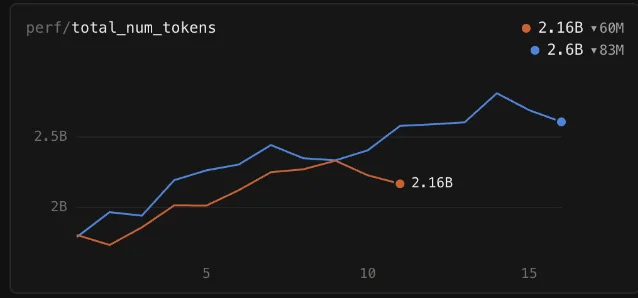
看板按 Pro、Flash 两条运行分别列出已经花掉的钱、当前 Step、每步 Token 数、总 Token 数、已训练样本数和训练 Batch 规模,下面是各项指标的实时曲线,数据直接来自训练机的日志 2。
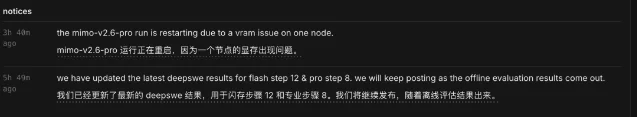
原文提到的公开范围还包括出故障的节点。看板的通知栏里就挂着这样一条:Pro 这一轮因为某个节点的显存问题正在重启。
两款模型现在练到哪一步
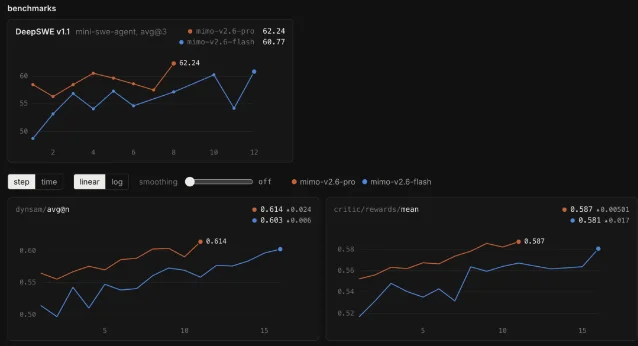
训练才进行一天多一点,原文判断还在初期,不过两款模型在这轮 RL 里都已经出现明显提升 1。
Pro 的 dynsam/avg@n 从第 1 步的约 0.565 升到 0.614,Flash 从约 0.514 升到 0.603;最新公开的 DeepSWE v1.1 离线评测里,Pro 和 Flash 分别拿到 62.24 和 60.77。原文同时给出对照:DeepSeek-Flash v1.1 在这一项上是 74.2% 1。
Flash 起点更低、追得很快,Pro 目前只保持小幅领先。Pro 跑完一个 Step 更慢,所以它最新的评分还没出来。
沉默了半年,小米只研究一件事
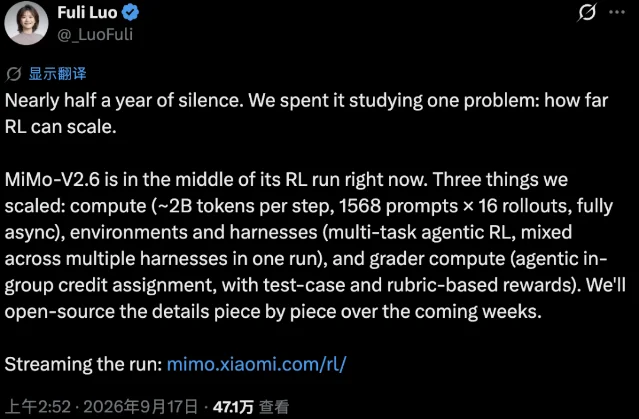
自 4 月开源 MiMo-v2.5 之后,小米沉默了近半年。罗福莉出面解释,这期间团队只研究了一件事:强化学习能扩展到多远 1。
她在推文里把这件事写成了三句话:
Nearly half a year of silence. We spent it studying one problem: how far RL can scale.MiMo-V2.6 is in the middle of its RL run right now. Three things we scaled: compute (~2B tokens per step, 1568 prompts × 16 rollouts, fully async), environments and harnesses (multi-task agentic RL, mixed across multiple harnesses in one run), and grader compute (agentic in-group credit assignment, with test-case and rubric-based rewards). We'll open-source the details piece by piece over the coming weeks.
(译文:沉默了近半年,我们用这段时间研究一个问题——强化学习能扩展到多远。MiMo-V2.6 正处在 RL 训练的中途。我们扩展了三件事:计算量,每步约 20 亿 Token、1568 个 Prompt × 16 条 Rollout、完全异步;环境与 Harness,多任务 Agentic RL,在一次运行里混合多个 Harness;评分计算,Agentic In-group Credit Assignment,带测试用例和量规奖励。相关细节我们会在未来几周逐步开源。)
原文把这套说法整理成一条线:扩展计算量,让模型产生更多经验;扩展环境和 Harness,让模型获得更多样的经验;增加评分计算量,则负责从这些经验里提取更准确的学习信号 1。
计算量的 Scaling:一个 Step 大约 20 亿 Token
MiMo-V2.6 系列每个训练 Step 大约会处理 20 亿 Token,配置是 1568 个 Prompt × 每个 Prompt 16 条 Rollout 1。
同一道题会让模型给出多条不同的解题和行动轨迹,再从这些尝试里获得强化学习信号。1568 × 16 意味着一轮就可能产生超过 2.5 万条 Rollout。
对 Agent 任务来说,一条 Rollout 远不只是一问一答:模型可能要经历几十轮思考、工具调用、环境反馈和再次行动,所以一个 Step 的 Token 数可以达到数十亿级别。
整个系统用的是 Fully Async,也就是完全异步的执行方式。按传统做法,一次 RL 训练像一条整齐的流水线,所有样本生成完才能统一评分,评完才能训练,然后才开始下一轮;大规模 Agent RL 很难这样等待 1。
在 MiMo 的系统里,不同任务同时处在不同阶段:有的 Agent 还在环境里执行,有的已经完成、等待判分,还有的在算 Reward,新任务也在不断进入系统。生成、执行、评分和训练组成了一条持续运转的异步流水线。
环境的 Scaling:一次 Run 里混合多种任务
第二个方向是 Environments and Harnesses,也就是训练环境和执行框架的扩展 1。
MiMo-V2.6 做的是 Multi-task Agentic RL:代码、通用任务、视觉、Chat 等不同类型的任务,可以混在同一次 RL Run 里训练,而且可以运行在不同的 Harness 里。
一个编程 Agent 的 Harness 可能允许模型打开终端、修改代码、执行测试、阅读报错,然后继续修改;一个视觉 Agent 面对的则是另一套工具、环境反馈和成功条件。
所以 MiMo 要扩展的不只是题目数量,还有模型能进入多少种环境、使用多少种工具、解决多少种类型的问题。看板上专门留了一栏 Batch Composition,用来显示每个训练 Step 里模型正在从什么样的任务和环境里获取经验。
评分的 Scaling:给打分本身加算力
第三个方向最容易被忽略:Grader Compute,也就是给打分本身增加算力 1。
代码任务可以跑 Test Case:100 个测试通过了多少个,就是相对客观的反馈。开放程度更高的 Agent 任务需要更细的判断,负责判断模型做得好不好的评分者,本身也开始消耗越来越多的计算资源。
更关键的问题是 Credit Assignment,也就是信用分配。假设一个 Agent 为完成任务连续执行 40 步——搜索资料、打开网页、阅读信息、编写代码、运行测试、发现错误、修改代码——最后只收到一句"成功,Reward=1",这条信号里其实没有模型需要的东西:这 40 步中哪些动作真的帮上了忙,哪些纯属多余,哪一次修改扭转了整个任务。
MiMo 这次提到的是 Agentic In-group Credit Assignment。具体算法原文没有公布,不过结合"同一个 Prompt 生成 16 条 Rollout"的训练方式,可以理解它的目标:用同一组里的多条 Agent 轨迹和结果,拿到比最终成败更细的强化学习信号。
原文留下的判断
原文对这套体系的收束是一句反问:
当预训练的 Scaling 已经发展多年之后,能否把模型与环境交互、产生经验、评价经验再到学习经验的整个 RL 循环,也变成一台可以持续扩大规模的机器?
来看热闹的人里,有人把这套说法翻成了一句大白话:"三件事,背后都是算力。" 1
想自己盯进度的,可以直接打开小米 MiMo 训练看板;罗福莉的原帖在 X。
References
- 1罗福莉沉寂半年官宣小米强化学习!直播新模型训练过程,一小时烧3万美元
mp.weixin.qq.com
- 2小米 MiMo-V2.6 强化学习训练看板
mimo.xiaomi.com
- 3
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.