Gemini 3.8 Flash TTS designs a voice from a prompt, replicates one from 30 seconds, and bills about half the 3.1 rate
Google's two new Gemini speech models are generally available, build custom voices from a prompt or a 30-second sample behind consent checks, and bill audio at roughly half the 3.1 preview's rate — with a two-speaker ceiling and a 200-voice cap per project.

Google published two text-to-speech models on September 23, both in general availability: Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS. They are audio-only models built on the Gemini 3 Pro base and replace a 3.1 Flash TTS that never left preview. 12
| Signal | Confirmed detail | What it means for you |
|---|---|---|
| What shipped | Two generally available models on the Gemini 3 Pro base: text in up to 8K tokens, audio out. 2 | Unlike the 3.1 preview, this is a surface you can build on. |
| What it costs | Flash TTS bills $0.50 per 1M input and $9.00 per 1M audio tokens; Flash-Lite $0.50 and $6.00. Both double on January 1, 2027. 3 | At Google's stated 25 audio tokens a second, that is roughly $0.014 a minute on Flash and $0.009 on Lite, against $0.03 on the 3.1 preview. |
| What breaks | Unary requests now return WAV instead of headerless PCM, and the text field is read strictly as a verbatim transcript. 4 | Pipelines that prepended a WAV header, or wrote stage directions into the script, need a rewrite. |
Direction becomes part of the script
What separates the tiers is voice design: Flash TTS invents a vocal identity from a natural-language description and covers 130 languages against Flash-Lite's 101, while Flash-Lite skips it and is positioned for high-volume dubbing and voice agents. Google's launch post puts the library at 2,000+, the DeepMind page says "over a thousand", and the API documents list 30 studio voices by name. 145
Delivery control splits in two. Sustained direction — "whispering", "out of breath" — belongs in a per-turn
speech_metadata.style field; momentary vocal bursts and pauses stay inline as angle-bracket tags in the transcript. Both models share one schema, so changing tier is a single parameter. 4Two speakers can be staged in a single request with
mode: "conversational", but only using prebuilt voices. Mixing custom or replicated voices in one dialogue means synthesizing each turn separately and concatenating. 4Voice replication rebuilds a speaker from a 30-second sample, behind a consent recording from the voice's owner. Stored voices are capped at 200 per project with a one-year expiry, and stateless voice keys last seven days. Replication through AI Studio is unavailable in Illinois, Texas, the EEA, the UK, Switzerland and India, and every generated clip carries a SynthID watermark. 14
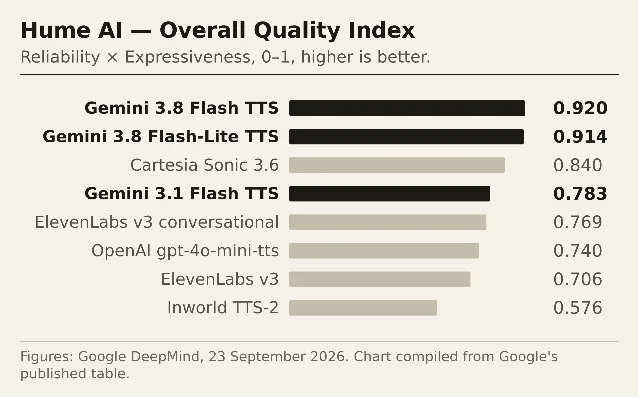
Where it stands, on Google's numbers
On Voice Arena's blind human Elo for US English, Flash-Lite leads at 1087 and Flash sits third at 1061, behind Cartesia's 1068. The same Google tables show where the new models lose: ElevenLabs v3 rates closer to human turn-to-turn variation, 5.00 against Flash's 4.58, and leads the single-tag voice-qualities measure 76.6 to 74.6. 56
All of it is Google's or its partners'; no independent measurement of the released models has appeared yet. 5
Why it matters
Persona, scene and per-line direction become text you can generate, version and reuse, which is what lets a script-to-audio pipeline live inside one API family. The price is the reason to move now, with two caveats: both rates double on January 1, and the voice cap is per project, not per key. 13
Flash TTS is rolling out in the Gemini API, Google AI Studio and Gemini Notebook; Flash-Lite in the API, AI Studio and Google Vids. Gemini Enterprise is "coming soon". 1
References
- 1Gemini 3.8 text-to-speech says hello
blog.google
- 2Gemini 3.8 Audio — model card
deepmind.google
- 3Gemini Developer API pricing
ai.google.dev
- 4Text-to-speech generation — Gemini API
ai.google.dev
- 5Gemini Audio — speech generation
deepmind.google
- 6Voice Arena — TTS US English leaderboard
voicearena.com
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.