Xiaomi's MiMo-V2.6-Pro tops the open-weight index at $0.13 a task; Claude Opus 5 still leads on coding
Xiaomi open-sourced MiMo-V2.6-Pro and Flash, a 1.02-trillion-parameter omni-modal family that Artificial Analysis measures as the highest-scoring open weights yet, seven points behind the closed leaders and still behind Claude Opus 5 on the coding rows Xiaomi reports.

Xiaomi released and open-sourced the MiMo-V2.6 series on September 21, with MIT-licensed weights for a 1.02-trillion-parameter flagship and a smaller model built for volume. 1 Both models take text, images, video and audio, return text, and carry a 1M-token context window. 2 Both are live on Xiaomi's API and OpenRouter, and both can be downloaded. 2
| Signal | Confirmed detail | What it means for you |
|---|---|---|
| What shipped | mimo-v2.6-pro and mimo-v2.6-flash, MIT weights, a distilled Qwen-3.5-9B, the technical report, 7,000-plus RL task environments, an RL framework and mini-harnesses. 1 | Two model slugs to try, or a full training stack to read. |
| What is new | One mixed reinforcement-learning run covering coding, general-agent, visual and cybersecurity tasks. 2 | The method is the story; the architecture is a familiar sparse mixture of experts. |
| What it costs | Pro $0.435 and $0.87 per million uncached input and output tokens; Flash $0.14 and $0.28. 3 | Flash costs a third of Pro for a few points less. |
| Where it lands | 46 on Artificial Analysis's Intelligence Index, the highest open-weight score, at $0.13 per index task. 4 | A downloadable model now matches the proprietary release of the same day. |
| The catch | On Xiaomi's own table Pro still trails Claude Opus 5 on the coding rows, and every agentic evaluation here was run by the vendor. 2 | One band of work is still closed-model territory. |
What Xiaomi's own table shows
Xiaomi's model card puts Pro at 71.9 on DeepSWE v1.1 against 19.0 for MiMo-V2.5-Pro, 53.1 on AutomationBench and 89.9 on Terminal-Bench 2.1. 2 It also claims Pro performs on par with Claude Opus 5 across most agent benchmarks, and on the general-agent rows that holds: AutomationBench 53.1 against 50.3, Terminal-Bench 2.1 89.9 against 89.1, Toolathlon-Verified 76.9 against 80.6. 2 The coding rows do not: DeepSWE 71.9 against 74.0, ProgramBench 26.5 against 37.0, MiMo Code Bench 63.2 against 68.6, Terminal-Bench 4.0 34.9 against 49.0. 2 Flash gives up little for its price — 67.9 against Pro's 71.9 on DeepSWE, 52.3 against 53.1 on AutomationBench. 5
Where it stands on someone else's scale
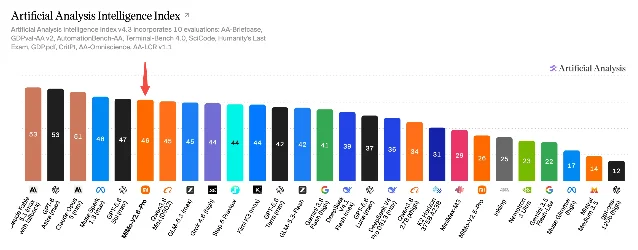
The bar it lands beside is a proprietary one: SpaceXAI's Grok 4.7 scores 46 as well. 7 The same measurement puts Pro at 125.2 output tokens per second against a 77.7 median for open-weight models of its size, and 2.19 seconds to first token. 4
Before you build on it
The licence is open; running it is another matter. Pro's repository holds about 570 GB of weights, and Xiaomi's recommended SGLang launch runs it at 16-way tensor parallelism across two nodes. 2 Flash, at 309 billion parameters with 15 billion active, runs at eight-way parallelism on one node. 5
On the API, UltraSpeed — the variant Xiaomi says generates up to 20 times faster — bills at ten times Pro's rates and is excluded from batch inference. 3 Batch work on the standard models costs half price, and the previous
mimo-v2.5-pro and mimo-v2.5 slugs retire on October 21. 3Xiaomi put the training method in the open with the weights: a technical report, the RL environments and the harnesses. 1 The report puts Pro's RL post-training at $2.6 million and Flash's at $0.9 million, run across thousands of GPUs with 1,568 prompts and 16 rollouts each per step, and says confirmed reward-hacking trajectories stayed under 2% for both. 8
References
- 1
- 2XiaomiMiMo/MiMo-V2.6-Pro-RL
huggingface.co
- 3Xiaomi MiMo API pricing
mimo.mi.com
- 4MiMo-V2.6-Pro — Intelligence, Performance & Price Analysis
artificialanalysis.ai
- 5XiaomiMiMo/MiMo-V2.6-Flash-RL
huggingface.co
- 6Xiaomi open-sources MiMo-V2.6 Pro and Flash models
testingcatalog.com
- 7
- 8
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.