Qwen3.8-Omni-Flash: audio and video in, text out, video input at $0.20 an hour
Qwen's first agentic omni-modal model takes audio and video in and returns text, ships as a hosted API at roughly a tenth of its predecessor's media price, and beats Gemini 3.8 Flash on agentic tool use and meeting transcription while trailing it on long-video reasoning, all on Qwen's own chart.
Qwen released Qwen3.8-Omni-Flash on September 18, 2026, its first omni-modal model built around agentic work. Text, images, audio and video go in one request, the context holds 1M tokens, and the model plans tasks and calls tools on what it finds. 1 A second endpoint, Qwen3.8-Omni-Flash-Realtime, is built for continuous live audio and video streams. 1
Two constraints decide what you do with it. Qwen shipped the model hosted, on QwenCloud, Alibaba Cloud Model Studio and Qwen Studio, with no weights published. 2 Its answer is text, and generated speech still routes to the older Qwen3.5-Omni. 3
What launched
| Signal | Confirmed detail | Action window |
|---|---|---|
| Hosted only | Live September 18, 2026 on QwenCloud, Model Studio and Qwen Studio; no open weights. 2 | Call it today; nothing to download. |
| Media in, text out | Text, image, audio and video input; 1M-token context, 991K max input, 131K max output; thinking on by default. 2 | Voices still mean Qwen3.5-Omni. |
| Agentic long video | Qwen reports OmniVideoBench accuracy up from 63.4 to 67.8 as tokens per query fall from 145,736 to 79,117. 1 | Test it on your own multi-hour footage. |
| Price | $0.15 per 1M input and $0.47 per 1M output tokens; video with audio at $0.20 an hour against $3.27 for Qwen3.5-Omni-Plus. 12 | Redo the media-cost arithmetic. |
| Documented limits | Video up to 2 hours and 2 GB by URL, audio up to 3 hours, 113 input languages, six regions. 3 | A two-hour recording goes in one call. |
What the chart shows
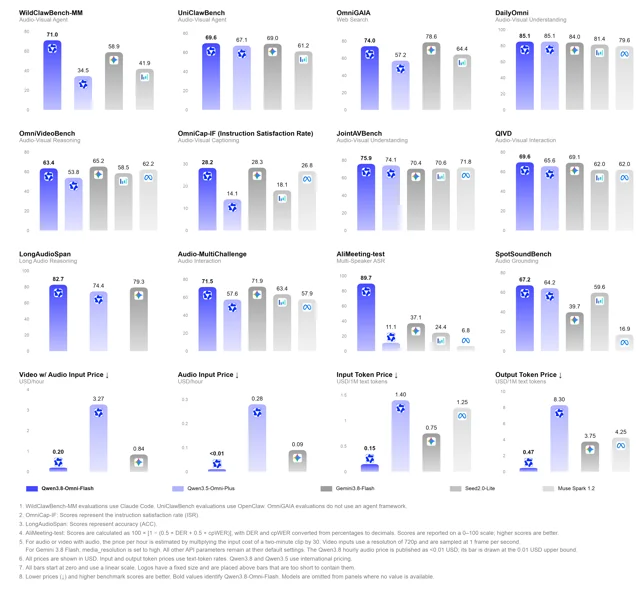
The launch claim — audio-visual performance close to Gemini 3.8 Flash, overall audio above it — splits panel by panel. Qwen3.8-Omni-Flash takes the panels where a tool is doing the work: 71.0 against 58.9 on WildClawBench-MM and 69.6 against 69.0 on UniClawBench. It also dominates multi-speaker transcription, where lower is better: 3.4 and 17.2 on AliMeeting's diarization and word-error measures against Gemini 3.8 Flash's 72.6 and 53.1. 1
Gemini 3.8 Flash holds the audio-visual reasoning panels, at 71.0 against 65.0 on Video-MME-v2, 70.7 against 63.3 on LVOmniBench, 65.2 against 63.4 on OmniVideoBench and 45.0 against 36.8 on AgenticVBench. 1
Agent mode narrows part of that. Inside Qwen's Qwen Code harness, Qwen3.8-Omni-Flash's LVOmniBench score climbs from 63.3 to 73.6, past the 70.7 where Gemini 3.8 Flash stays; Gemini 3.8 Flash rises from 65.2 to 70.1 on OmniVideoBench under the same harness. 1
The headline agentic gain averages two benches. Qwen's launch post puts it at +19.5 points across WildClawBench-MM and UniClawBench; against Qwen3.5-Omni-Plus, the chart shows +36.5 on the first and +2.5 on the second. 14
Why it matters
The price is the news for long-recording pipelines. Video with audio costs $0.20 an hour where the model it replaces charged $3.27, and input tokens cost $0.15 per million against Gemini 3.8 Flash's $0.75. 1
Every number above is Qwen's, on its own harnesses; no independent evaluation had appeared by publication. 5
Qwen also shipped tooling. Qwen-MM-Plugins installs as skills and optional MCP servers into Claude Code, Codex, Qwen Code, Gemini CLI and others, wrapping capabilities such as an audio-visual memory of a long video and speaker-preserving video translation. Its README records one gap: most harnesses cannot yet feed audio to the main model, so audio routes through the API. The companion Qwen-Live Harness is further off: the blog calls it open-sourced, the launch post marks it "coming soon", and its repository link does not resolve. 6
References
- 1
- 2Qwen3.8-Omni-Flash — QwenCloud
qwencloud.com
- 3Qwen-Omni — Alibaba Cloud Model Studio
alibabacloud.com
- 4Qwen on X
x.com
- 5Alibaba Qwen Releases Qwen3.8-Omni-Flash
marktechpost.com
- 6QwenLM/Qwen-MM-Plugins
github.com
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.
Related content
More from this channel
- StepFun's Step 5 Preview matches Grok 4.6 and Kimi K3 on the intelligence index, at $0.71 a task
- Google's Gemini reached three real companies in May, from an evaluation environment that was supposed to be offline
- TypeSafe's Jev answers typed questions in 70–500 ms at $0.042 per million tokens, and ships with the vendor's own failure list
- Grok Voice Transcribe 2.0: a 2.7% word error rate at $0.20 an hour, while the API default still ships v1
- Meta ships Muse for Mac, the agent's first desktop client, with files and Messages behind a permission prompt
- OpenAI's Astra for Law pairs GPT-6 Astra with a 230-million-URL legal index, open to selected law firms only
- Grok Build's memory is now generally available — notes after every turn, read back in later sessions
- Gemini 3.8 Live arrives as two voice models — 30.1% and 68.6% on the same agentic test