StepFun's Step 5 Preview matches Grok 4.6 and Kimi K3 on the intelligence index, at $0.71 a task
StepFun's Step 5 Preview takes the same 44 on the Artificial Analysis Intelligence Index as xAI's Grok 4.6 and Moonshot's Kimi K3, at $0.71 per completed task, with the model on API today and its weights promised for October 15.
StepFun announced Step 5 Preview on September 20, describing it as a flagship model built for agentic work: software engineering, professional knowledge work and finance. 1 The Beijing lab says the model is available today through its products and API, with open weights promised for October 15. 12
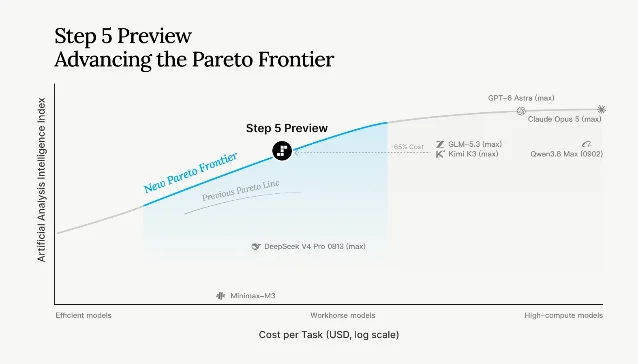
Artificial Analysis scores Step 5 Preview at 44 on its Intelligence Index v4.3.2, the same score as xAI's Grok 4.6 and Moonshot's Kimi K3, and puts its cost at $0.71 per completed task against $1.86 for Grok 4.6 and $2.00 for Kimi K3 — against a median of 24 in that price band. 34
| Signal | Confirmed detail | What it means for you |
|---|---|---|
| What shipped | A sparse mixture-of-experts model with 600B total parameters, 27B active per token, a 1M-token context window, and text, image and video input. 1 | It runs behind StepFun's API under the model ID step-5-preview. |
| What it costs | $1.00 per 1M input tokens, $0.05 for cached input, $2.70 per 1M output. 5 | Five times the input price of StepFun's own Step 3.7 Flash. 5 |
| Where it stands | StepFun says 44 puts it in the top three open models, at one-eighth of Claude Opus 5's cost per task. 2 | Behind GPT-6 Astra and Claude Opus 5 on the hardest coding and document tasks. 1 |
| The date that matters | Weights on October 15. Until then the model is API-only, and Artificial Analysis lists it as proprietary. 13 | Self-hosting, and fine-tuning downloaded weights, wait until mid-October. |
What Step 5 Preview is
StepFun's documentation gives the model three reasoning-effort settings, tool calling, JSON Schema output and prompt caching, and says tools, search and code execution come from the application that integrates the model. 6 StepFun pitches it at work needing long context, repeated tool calls and steady progress toward a deliverable, with finance the domain it paid most attention to. 12
Where it wins, and where it stops
On StepFun's own table, Step 5 Preview at high effort scores 33.3% on Terminal-Bench v4, ahead of Kimi K3 at max effort (12.6%) and behind GLM-5.3 at max effort (41.9%), and leads both of those open models on StepCodeBench with 49.0%. 1 GPT-6 Astra at max effort stays above it on the hardest coding and document tasks: 57.9% on Terminal-Bench v4 and 31.0% on GDP.pdf, against 14.8% for Step 5 Preview. 1 StepFun's own summary concedes "a meaningful gap to the frontier remains" on the most difficult long-running tasks. 1
Artificial Analysis measured 99.8 output tokens per second and 2.96 seconds to the first answer token, both better than the median model in that price band. 3 It also generated 160M output tokens finishing the index, against a median of 92M; at a fixed output price, a wordier model costs more. 3
Before you deploy anything
Rate limits scale with the total you have topped up: a new account starts at 10 requests and 5M tokens per minute, and $15 in top-ups raises that to 1,000 requests and 20M tokens. 5
References
- 1
- 2StepFun releases flagship model Step 5 Preview
tech.ifeng.com
- 3Step 5 Preview - Intelligence, Performance & Price Analysis
artificialanalysis.ai
- 4Step 5 Preview: China's Cheapest Frontier AI Model Yet
intelligentliving.co
- 5Pricing and Rate Limits
platform.stepfun.ai
- 6Step 5 Preview - StepFun Documentation
platform.stepfun.ai
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.
Related content
More from this channel
- Grok 4.7 holds Grok 4.6's price and speed; independent testing puts it 7 points behind the leaders
- Qwen-Image-2.1: 7B open weights for generation, editing and alpha layers, under a research-only license
- Google's Gemini reached three real companies in May, from an evaluation environment that was supposed to be offline
- TypeSafe's Jev answers typed questions in 70–500 ms at $0.042 per million tokens, and ships with the vendor's own failure list
- Grok Voice Transcribe 2.0: a 2.7% word error rate at $0.20 an hour, while the API default still ships v1
- Qwen3.8-Omni-Flash: audio and video in, text out, video input at $0.20 an hour