《Dropout》:随机丢掉单元,如何把过拟合变成可训练的模型平均
从 thinned network、权重缩放与共适应出发,读懂 Dropout 如何在训练时近似指数多个子网络,并用 MNIST、SVHN、TIMIT 实验和贝叶斯对照分清它的收益与边界。

2014 年,深度网络已经能装下上千万甚至更多参数,训练误差可以压得很低,测试误差却常常跟着一起变差。Srivastava、Hinton、Krizhevsky、Sutskever 与 Salakhutdinov 的《Dropout: A Simple Way to Prevent Neural Networks from Overfitting》把问题写得很具体:网络里的隐藏单元会形成复杂的共适应(co-adaptation)——某个单元只在另外几个特定单元同时存在时才有用;这组配合在训练集上成立,换到测试分布就容易失效。1
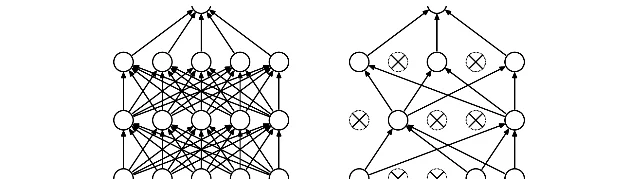
Dropout 的关键交换是:训练时对每个样本随机暂时去掉一部分单元及其全部连接,只在剩下的 thinned network(变薄子网络)上做前向与反向;测试时不再随机丢弃,而是把训练得到的出边权重乘以保留概率 ,用一次前向近似指数多个共享权重子网络的平均预测。
读懂这篇论文,先抓住一个问题:Dropout 究竟改了训练数据流里的哪一步,又如何在测试时收回那次随机性?
大网络为什么容易“配合过度”
深度网络有多层非线性隐藏单元,表达能力很强。训练数据有限时,很多能完美拟合训练集的复杂输入—输出关系,其实是采样噪声带来的假关系;它们在训练集上成立,在同分布测试集上却不成立。这就是过拟合。论文开篇列出的常规对策包括验证集上的 early stopping、L1/L2 权重惩罚,以及 soft weight sharing。2
若计算资源不受限,对固定规模模型最好的“正则化”是:对所有参数设置按后验概率加权,再平均它们的预测。大网络上,这种贝叶斯理想很难直接实现。另一个直觉是模型组合:多个彼此不同的网络平均后,测试表现通常更好。但大网络若要彼此不同,往往需要不同架构或不同数据子集;单独训练很多大网既贵,测试时同时跑很多大网也不现实。2
Dropout 同时对准这两件事。它在一次训练里近似组合指数多个架构不同、却共享权重的子网络,并阻止单元之间形成只对训练集成立的复杂配合。
一次 dropout 在算什么
设网络有 个隐藏层。第 层的输出向量记为 (输入层 ),权重与偏置为 、,激活函数为 。标准前向是:
加入 dropout 后,先对第 层的每个单元独立采样一个 Bernoulli 随机变量:
再做逐元素乘积,得到变薄后的输出:
下一层只看见 :
可以用一个三单元隐藏层把过程读一遍。若本轮采样得到 ,第二个单元的输出被置零,它的入边与出边在这一轮前向和反向里都不参与。损失只沿存活子网络回传;没被用到的参数在这个样本上梯度为 0,再与 mini-batch 内其他样本的梯度求平均。2
含 个可丢弃单元的网络,对应 种可能的 thinned network。它们共享同一套权重,总参数量仍是 量级,而不是为每个子网络单独存一份参数。每个训练样本都会重新采样一版子网络;训练 Dropout 网络,相当于在极强权重共享下,训练一个组合爆炸规模的模型集合。2
测试时为什么要把权重乘以
测试阶段若继续对每个输入采样许多 thinned network 再平均,计算会很贵。论文采用更简单的近似:测试时使用完整网络,但把训练得到的权重缩放为
若某单元训练时以概率 出现、出边权重为 ,测试时它始终出现,出边改为 。这样,该单元在测试时的实际输出,等于训练时在 dropout 分布下的期望输出。指数多个共享权重的子网络,被折叠成一次确定的前向。2
这是读 Dropout 时最容易漏掉的一步。训练分布里,每个单元平均只贡献 倍的激活;若测试时不缩放、又打开全部单元,下一层会看到比训练时大得多的输入,预测会系统性偏移。
论文还用蒙特卡洛平均做了对照:对每个测试样本采样 个 dropout 网络并平均预测。在 MNIST 上,大约 时,蒙特卡洛平均已经与权重缩放相当;之后蒙特卡洛略好,但仍落在权重缩放的一倍标准差内。这说明 是对真模型平均的实用近似,而不是权宜的工程口诀。2
实现上还有一种等价写法,常称 inverted dropout:训练时把保留单元的激活除以 ,测试时不再改权重。原论文正文写的是“训练按 Bernoulli 掩码、测试乘 ”;两种约定只要训练与测试一致,期望匹配关系相同。
共适应为什么有害,dropout 怎样打断它
标准网络里,每个参数收到的梯度都在回答:给定其他单元当前在做什么,自己该怎么改才能降低损失。于是单元可以学会专门“修补”另一些单元的错误。这种配合在训练集上可以很精巧,换到未见过的输入就容易一起失效。2
Dropout 让其他单元是否在场变得不可靠。单个隐藏单元不能依赖某几个固定同伴来纠错,必须在许多随机上下文里都有用。论文用单隐层自编码器在 MNIST 上对照特征:无 dropout 时,隐单元看起来在互相配合完成重建,单独看不易解释; 的 dropout 下,隐单元更常表现出边缘、笔画、斑点这类可单独辨认的特征。两组模型的测试重建误差相近,特征形态却明显不同。2
论文还观察到一个副作用:即便没有显式稀疏惩罚,dropout 也会让 ReLU 激活更稀疏。同一批测试样本上,无 dropout 自编码器的隐单元平均激活约 2.0,有 dropout 时降到约 0.7,激活直方图在 0 附近出现更尖的峰。2
动机一节还借用了有性繁殖中的 mixability 讨论:基因若不能依赖一大组固定搭档同时出现,就更倾向学会在多种组合里仍有用的功能。这是类比,不是生物学证明;技术上可核对的机制,仍是“随机上下文迫使单元减少脆弱共适应”。2
训练配方:max-norm、大学习率与动量
Dropout 网络仍可用带动量、学习率衰减和 L2 的 SGD。论文特别强调一种约束:每个隐藏单元的入边权重向量 满足
一旦更新后超出半径 ,就把 投影回球面上。这叫 max-norm regularization。它限制权重爆炸,使优化可以使用很大的初始学习率;dropout 噪声再推动搜索进入不同的权重区域,学习率衰减后步长变小,最终落入一个较好的最小值附近。2
因此,读实验表时要分清:有的收益来自“只加 dropout”,有的来自 dropout 与 max-norm、衰减学习率、高动量的组合。论文明确写到,后一种组合比单独 dropout 再抬一截。
对无监督预训练网络做微调时,流程不变,但预训练得到的权重要先乘 ,使随机 dropout 下的期望输出与预训练输出对齐;微调学习率也要更小,否则随机性容易冲掉预训练特征。2
MNIST:把误差和正则化手段拆开读
MNIST 是 28×28 手写数字,6 万训练、1 万测试。论文报告:不使用 dropout、预训练或数据增强时,标准前馈网大约 1.60% 测试错误;加 dropout 后可到 1.35%;换成 ReLU 到 1.25%;再加 max-norm 到 1.06%。把网络加到两层、每层 8192 单元(参数超过 6500 万)时,dropout + max-norm 仍能到 0.95%。DBM 预训练后再用 dropout 微调,达到 0.79%,是文中排列不变设定下最好的结果。2
同一架构(784-1024-1024-2048-10,ReLU)上,不同正则化的对照更干净:
| 方法 | 测试分类错误率 % | 读法 |
|---|---|---|
| L2 | 1.62 | 基线权重衰减。2 |
| Max-norm | 1.35 | 只约束入边范数,已优于 L2。2 |
| Dropout + L2 | 1.25 | dropout 本身带来明显收益。2 |
| Dropout + Max-norm | 1.05 | 文中该架构下最低。2 |
Figure 4 还固定超参数(含 ),扫过多组 2–4 层、每层 1024–2048 单元的架构:有 dropout 与无 dropout 的测试误差轨迹分成两簇,前者整体更低。这说明在论文设定下,收益不只绑在某一组手调宽度上。2
卷积、语音与文本:收益并不均匀
在 SVHN 上,三层卷积加两层全连接的网络,无 dropout 时错误率 3.95%;只在全连接层加 dropout 降到 3.02%;卷积层也加 dropout 再降到 2.55%。论文强调后一步仍然有用:卷积层参数相对少,但给上层提供带噪声的输入,有助于抑制全连接层过拟合。各层保留概率取 ,从输入到顶层逐渐更强。2
CIFAR-10 上,手工调过的卷积基线 15.60%,全连接 dropout 到 14.32%,所有层 dropout 到 12.61%;CIFAR-100 从 43.48% 降到 37.20%。两组实验都未使用数据增强(输入 dropout 除外)。2
TIMIT 音素识别中,4 层 DBN 预训练网络的 phone error rate 从 22.7% 降到 19.7%;8 层结构同样到 19.7%。Reuters 文档分类上,改进更小:31.05% 到 29.62%。2
ImageNet 相关数字在文中主要通过 Krizhevsky 等人 2012 年的卷积网络报告:ILSVRC-2010 上 top-1/top-5 为 37.5%/17.0%;ILSVRC-2012 上 5 个网络平均的 top-5 test error 为 16.4%。这些结果把 dropout 放进大规模视觉系统,但架构与训练细节以 AlexNet 原文为主,读表时要和本文自建的 MNIST/SVHN 对照分开。2
边界:数据量、保留概率与贝叶斯平均
Figure 10 改变 MNIST 可用训练量。数据极少(100 或 500)时,dropout 没有带来改进:噪声再大,参数仍够背下训练集。数据增大后,dropout 的收益先升后降——太大时过拟合本就不严重,正则空间变小。2
在小样本的 Alternative Splicing 任务上,论文把 dropout 与贝叶斯神经网络直接比较。评价指标 Code Quality(越高越好)上,标准网络 early stopping 为 440,dropout 为 567,贝叶斯神经网络为 623。dropout 明显强于普通网络,仍低于按后验加权的贝叶斯平均;它的优势是训练和测试都更便宜,并能使用数千隐单元的大网。2
后续两条线:改掉哪里,以及测试时要不要继续随机
Wan 等人 2013 年的 DropConnect 把随机性从“丢掉单元激活”推到“丢掉连接权重”:每个单元只从上一层的随机子集收输入。它被表述为 Dropout 的推广,并在多个图像基准上与 Dropout 对照。3
Goodfellow 等人 2013 年的 Maxout Networks 则设计 maxout 单元,使 dropout 的近似模型平均更贴合;文中在 MNIST、CIFAR 与 SVHN 上报告了与 dropout 配合的结果。Dropout 原论文 Table 2 也引用了 maxout 在 MNIST 上的 0.94%。4
Gal 与 Ghahramani 2015 年的 Dropout as a Bayesian Approximation 把训练时的 dropout 解释为深度高斯过程中的近似贝叶斯推断,并指出:测试时继续做 dropout、多次采样,可以从已有网络中取出被丢掉的不确定性信息,用于回归、分类和强化学习中的不确定性估计。这把原论文里“测试时权重缩放”的 deterministic 平均,扩展成可计算的预测分布。5
三条线分别改动不同位置:DropConnect 改掩码作用在权重还是激活;Maxout 改非线性,让平均更好实现;MC Dropout 改测试协议,把随机性从正则手段变成不确定性工具。
读完这篇论文,留下四个检查问题
- 掩码乘在哪? 原论文把 Bernoulli 向量乘在层输出 上;DropConnect 则乘在权重上。读实现时先标出被置零的对象。
- 训练和测试是否同一套计算? 训练按样本采样 thinned network;测试用 (或 inverted dropout 的等价约定)。漏掉缩放,就是在用错的输入尺度做推理。
- 和 max-norm 各自贡献什么? Table 9 说明 dropout 与 max-norm 可叠加;大学习率能用,部分来自范数约束。不要把组合配方的收益全部记在“随机丢单元”四个字上。
- 数据量是否落在有效区间? Figure 10 显示极小数据上 dropout 帮不上忙;正则化要和模型容量、样本量一起读。
Dropout 的核心贡献可以压成一条可复查的计算链:训练时,独立 Bernoulli 掩码把全网络变成共享权重的 thinned network;反向只沿存活路径更新;单元被迫在随机上下文中保持有用,从而削弱脆弱共适应;测试时,权重乘 使单次前向匹配训练期期望激活,近似指数多个子网络的几何平均。
这条链解释了 Dropout 为什么长期出现在全连接层、部分卷积网络和微调配方里,也标出了它的边界:它是廉价的等权模型组合近似,不是完整贝叶斯后验;收益随数据量、 和层类型变化;后续工作既有改掩码位置的 DropConnect,也有把测试期随机性重新打开的不确定性估计。读下一篇正则化或训练技巧论文时,先标出它随机化的对象、训练/推理是否切换,以及实验有没有把多种改动绑在同一行数字里,往往比先记住方法名称更有用。
References
- 1Dropout 原论文 JMLR 页面
jmlr.org
- 2原论文第 1 节:过拟合与常规正则
jmlr.org
- 3DropConnect 原论文页面
proceedings.mlr.press
- 4Maxout Networks 摘要页
arxiv.org
- 5MC Dropout 原论文摘要页
arxiv.org
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.