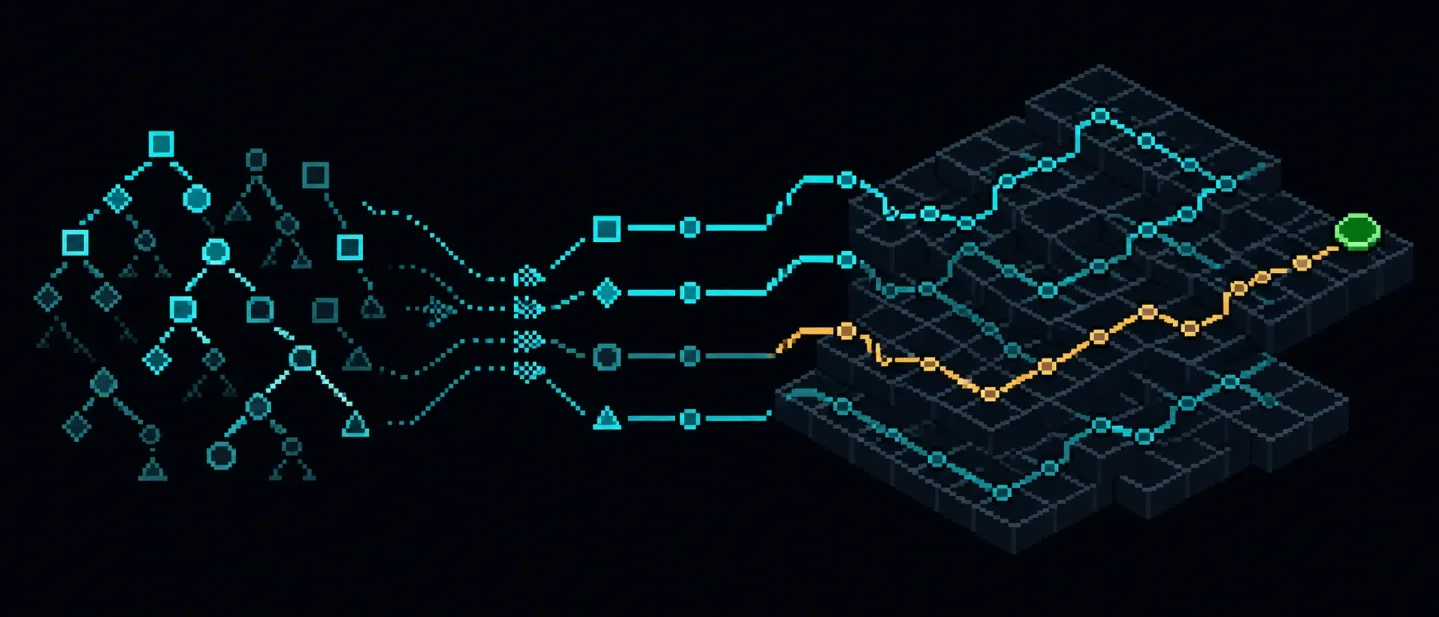
Narcissus keeps LLM proposals in context—and leaves every rule reachable
Narcissus turns imperfect LLM program proposals into task-local, context-aware search guidance, improving synthesis across SLIA, bit-vectors, DeepCoder, ARC, and ARGA while leaving persistent library learning open.
Tilman Hinnerichs, Sebastijan Dumančić, and Neil Yorke-Smith of Delft University of Technology released Narcissus: Program Synthesis Using Context-Aware LLM Approximations on arXiv on August 26, 2026. The paper reports 51.4 solved tasks out of 70 on an SLIA subset, 40 out of 100 on ARC, and 350 out of 587 on a bit-vector setting; its mechanism is a one-shot conversion of LLM proposals into cheap, context-sensitive search guidance. 1
The useful question is where this contribution sits in the DreamCoder family. Narcissus improves the search-guidance side of the lineage. It leaves persistent library growth, a trained neural recognition model, and the wake-sleep learning loop as open work.
Full summary
The problem: proposals know a language that the target DSL does not
Narcissus starts with inductive program synthesis. A grammar defines the legal target language, and input-output examples define the specification. The synthesizer must find a grammatical program that passes every example. Enumerative search can guarantee coverage of the grammar in principle, yet the number of programs grows exponentially with program size. The practical question becomes which candidate to try first. 1
An LLM can suggest useful structure while still producing an invalid or incorrect program. A fixed DSL may contain operators that rarely appear in the model's training data, so a prompt that includes the grammar still produces familiar functions from another language. Re-prompting draws another sample from the same model distribution. Narcissus instead samples a small set of proposals once, then lets symbolic search spend the large per-task budget. 1
The baseline that Narcissus targets, represented by HySynth and related work, turns proposal counts into a static rule prior. If a proposal uses
concat often, the static prior raises the score of concat everywhere. That score carries frequency, while the proposal tree also carries position: concat(x, ".") may belong at the end of a program and nowhere else. A global count discards that placement information. 1The pipeline: repair first, then mine and compile
Narcissus prompts the LLM once per task with the grammar and the input-output specification. The proposal text is parsed into an abstract syntax tree. The repair pass walks from the root, matches each node against rules that can produce the expected type, and replaces an incompatible subtree with a typed hole. The intact structure around the hole remains available as evidence. A proposal can therefore contribute its surrounding arrangement even when one operator, arity, or type is wrong. 1
The repaired trees then supply task-local macro-rules. Narcissus mines every repeated subtree with at least two nodes that occurs at least twice across the proposals. Each mined fragment becomes a macro-rule in an extended grammar. A repeated fragment can then be inserted in one expansion instead of being rebuilt node by node. Partial fragments can retain typed holes as arguments. 1
This is the first boundary to keep visible. The macro-rules change the grammar available to the current task, and the paper measures their isolated effect with augmented breadth-first search. The mined fragments are discarded when the task ends. The current implementation therefore performs per-task proposal mining, while cross-task library learning remains a future extension. 1
The heuristic: three signals attached to an expansion
At each open position in a partial program, Narcissus scores a possible grammar rule with three signals.
- Prefix alignment counts proposals that share the same root-to-hole path and then choose the candidate rule at that hole. A rule receives support because it appears in the same surrounding context, rather than merely because it appears somewhere in a proposal.
- Sub-program reuse rewards a rule or mined fragment that reconstructs a subtree repeated across proposals. This signal keeps useful local fragments available when complete proposals disagree about their larger structure.
- Regularization pulls the candidate size toward the sizes of the repaired proposals. A positive floor
Cis added to the size score, so every original grammar rule retains a strictly positive score. 1
The floor gives the method its safety property. A weak proposal can delay a solution through poor ordering, while every rule remains reachable. When the proposals carry no useful signal, the floor makes the expansions tie and the search falls back to unguided enumeration. The heuristic reorders search; it does not turn a proposal into a hard constraint. 1
Narcissus tests the same idea in two backends. Genetic search works top-down, so each candidate retains a root-to-hole context. Cost-guided bottom-up beam search builds the root last, so it anchors the corresponding signals on complete sub-programs and the parent rule being considered. The LLM is absent from both search loops; each expansion uses a tree lookup and the compiled scores. 1
Key details and evidence
The following comparison keeps four recurring questions together: what survives after the current task, where the neural component acts, what role symbolic search plays, and whether the method grows a library across tasks.
| Method | Retained object | Neural role | Search role | Cross-task status |
|---|---|---|---|---|
| Narcissus | Repaired proposals and repeated task-local macro-rules | One-shot LLM proposals; no model training | Context-aware ordering with prefix alignment, reuse, and regularization | Mined fragments are discarded after each task 1 |
| DreamCoder | Learned DSL/library abstractions and a recognition model | Neural recognition model guides search and is trained during dreaming sleep | Wake-phase search over the current library | Library and recognizer improve across tasks through wake-sleep learning 2 |
| LAPS | Reusable abstractions plus learned search guidance from language supervision | Language model supplies task and library guidance | Synthesis uses learned guidance alongside symbolic search | Library abstractions are intended for reuse across tasks 3 |
| Stitch | Compressed abstractions from a program corpus | Neural proposal generation is outside the core compression operation | Top-down synthesis uses the compressed DSL | Extracted functions are corpus-level abstractions 4 |
| LILO | A reusable, documented symbolic library | LLM guides synthesis and documentation | Stitch-style compression organizes discovered code | Library reuse is a central cross-task goal 5 |
The rows separate two meanings of "library learning." Narcissus mines fragments that make the present task cheaper. DreamCoder, Stitch, and LILO retain abstractions as reusable program vocabulary. Narcissus also uses a neural source, yet the source supplies fixed proposals rather than a trained recognition function that predicts useful rules from a partial program. The architecture therefore advances proposal compilation while leaving the lineage's persistent learning loop open.
Five domains, two search backends
The experiments cover string and bit-vector SyGuS tracks, DeepCoder list manipulation, ARC over the Hodel DSL, and the object-centric ARGA subset. Proposal support varies from strong on parts of SLIA to weak on BV, DeepCoder, ARC, and ARGA with DeepSeek. The evaluation combines Narcissus with EUSolver's divide-and-conquer decomposition for BV, ARC, and ARGA. 1
On the 70-task SLIA subset with GPT-4o proposals, Narcissus plus genetic search solves 51.4 tasks on average, and Narcissus plus bottom-up search solves 49.0. The static-prior baselines solve 32.2 and 48.0 tasks with the corresponding backends. The AUC gap is larger than the final-count gap: genetic Narcissus reaches solutions earlier, with a normalized AUC of 32.2% versus 18.2% for static genetic search. 1
The proposal-quality comparison is also informative. Direct GPT-4o proposals solve 31% of the SLIA tasks, while direct DeepSeek-V4-Flash proposals solve 20%. Narcissus raises the DeepSeek proposal set to 32.6 solved tasks out of 70, roughly 47%, which exceeds direct GPT-4o sampling and matches the static prior run on GPT-4o proposals. The result measures how much search can recover from a cheaper proposal source; it measures neither program correctness beyond the benchmark specifications nor deployment performance. 1
ARC exposes the difference between a useful proposal and a correct proposal. Grammar-valid raw proposals solve 13 of 100 tasks, while the full Narcissus search solves 40 of 100. The extra solutions come from intact fragments and arrangements that the search can recombine and correct. A proposal-like program appearing sooner is evidence about search ordering and budget use; it is separate from evidence that the proposal itself satisfies the specification. 1
BV tests the reachability guarantee under weak proposals. Narcissus plus bottom-up search solves 350 of 587 tasks, compared with 300 for unguided breadth-first search and 102 for the static guidance baseline. The static prior gives missed rules such weak scores that the beam rarely explores them. Narcissus's positive floor keeps the full grammar available, so the guidance can exploit fragments without making proposal omissions permanent. 1
The ablation study assigns different work to the three signals. With weaker DeepSeek proposals, prefix alignment is load-bearing: removing it lowers the genetic result to 24.0 tasks out of 100, while prefix alignment alone reaches 43.2. With stronger GPT-4o proposals, sub-program reuse carries more of the result: reuse alone reaches 44.2 tasks out of 70, and removing reuse lowers the full result from 51.4 to 47.2. Regularization alone stays close to unguided search, yet it protects the weak-proposal regime by preserving reachability. 1
A proposal-region experiment gives the mechanism a search-cost measurement. On SLIA with DeepSeek proposals, Narcissus reaches a proposal-like region about 12 times sooner than the static heuristic. The paper's interpretation is about where the enumeration budget goes: regularization concentrates search near the proposal sizes, while breadth-first search spends budget on small programs and the static prior spreads it across a long tail. 1
Where Narcissus sits in the DreamCoder lineage
DreamCoder. DreamCoder alternates a wake phase that searches for solutions with sleep phases that abstract solved programs into a library and train a neural recognition model through generated "dreams." The library changes the DSL available to later tasks, and the recognizer learns to guide later search. Narcissus shares the idea that symbolic enumeration needs learned guidance, yet its proposals and macro-rules live only within one task. 2
LAPS. LAPS uses language supervision to guide both reusable library abstractions and neural search heuristics. Narcissus also uses language-model output, but the output is a small proposal set compiled into a fixed task-specific heuristic. Its procedure therefore targets the cost of repeated search-time model calls rather than language-supervised cross-task library and heuristic learning. 3
Stitch. Stitch compresses a corpus of DSL programs into function abstractions. Narcissus mines recurring proposal subtrees before search, which supplies a similar shortcut inside the current task. The difference is the lifetime of the abstraction: Stitch operates on a program corpus, while Narcissus's mined fragments currently expire with the task. 4
LILO. LILO combines LLM-guided synthesis with Stitch-style compression and documentation to build a reusable library. Narcissus isolates an earlier step that LILO also makes useful: imperfect neural suggestions can seed symbolic search and provide fragments worth assembling. The paper's own next step is to carry those fragments across tasks; that step would move the method closer to the persistent-library side of the lineage. 5
Verbatim quotes
"Narcissus is drawn to a reflection: it follows the proposals the LLM leaves behind, not the LLM itself." — Tilman Hinnerichs, Sebastijan Dumančić, and Neil Yorke-Smith, Narcissus: Program Synthesis Using Context-Aware LLM Approximations. 1
"Mined fragments are currently discarded after each task." — Tilman Hinnerichs, Sebastijan Dumančić, and Neil Yorke-Smith, Narcissus: Program Synthesis Using Context-Aware LLM Approximations. 1
The unresolved test is concrete: can a future Narcissus-style system retain mined abstractions across independent tasks, train a recognizer to choose when to invoke them, and show shorter search on held-out tasks? That experiment would distinguish a task-local compiler for LLM hints from a growing DreamCoder-style program library.
References
- 1
- 2
- 3
- 4Stitch: A Language for Every Program
arxiv.org
- 5
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.
Related content
More from this channel
- REFACTOR-VLA finds a library signal in robot trajectories, then loses the motor programs
- aDSL makes 3D spatial relations executable, then lets the critic repair them
- Hypothesis Frontier 把验证器变成搜索状态,却没有学习 DreamCoder 式库
- Solver-aware decomposition trades ground-truth subgoals for tractable program search
- Neural Language Interpreter learns a program language and searches it with gradients