Grok 4.7 holds Grok 4.6's price and speed; independent testing puts it 7 points behind the leaders
SpaceXAI released Grok 4.7 at Grok 4.6's $2/$6 price and speed, on a larger base model and a longer training run, while independent testing still places it seven points behind the leaders.
SpaceXAI released Grok 4.7 on September 21 as its flagship for coding and knowledge work, at the same price and speed as Grok 4.6: $2 per million input tokens and $6 per million output. 1 It runs on a new, larger base model, trained with a longer reinforcement-learning run on a harder mix of tasks weighted toward work that takes many hours. 1 SpaceXAI is the name the lab has traded under since SpaceX acquired it in February 2026. 2
SpaceXAI's own table puts Grok 4.7 ahead of Grok 4.6 on every row and behind Claude Fable 5.1 on most of them. Independent measurement separates the two further: on the Artificial Analysis Intelligence Index, Grok 4.7 scores 46 while Fable 5.1 and GPT-6 lead at 53. 34
| Signal | Confirmed detail | What it means for you |
|---|---|---|
| What shipped | grok-4.7 on the xAI API, with a 500k-token context, a May 2026 knowledge cutoff, text and image input, and no output limit. 5 | One model slug to change on the API. |
| What's new | A larger base model, a longer RL run weighted to multi-hour tasks, and native training on the Grok Bot harness. 1 | It extends the long-running-agent work Grok 4.6 targeted. |
| What it costs | $2 and $6 per million input and output tokens below a 200k-token prompt and twice that above, at reasoning effort low, medium, high or xhigh. 56 | Cheap for its class, until a long prompt doubles the rate. |
| The catch | SpaceXAI reports 38.0% on Terminal-Bench 4.0; Artificial Analysis measures 26%. 14 | One benchmark, 12 points apart: a score is a claim until someone else runs it. |
What the vendor's table shows
Grok 4.7 is listed at xhigh effort against Grok 4.6 at high and GPT-5.6 Sol and Fable 5.1 at max. 1 Grok 4.7 beats Grok 4.6 on all seven rows, and beats Fable 5.1 on three of them: EEBench, 64.0% against 56.4%; the Harvey Legal Agent Benchmark, 19.6% against 6.7%; and DeepSWE v1.1, 71.0% against 70.0%, scored at high effort. 1 Fable 5.1 stays ahead on CursorBench 4.0, AA Briefcase v1.1, Terminal-Bench 4.0 and HealthBench Professional. 1 The price column carries half the slogan: Fable 5.1 at $10 and $50 per million tokens, GPT-5.6 Sol at $4 and $20, Grok 4.7 at $2 and $6. 1
Where it stands on someone else's scale
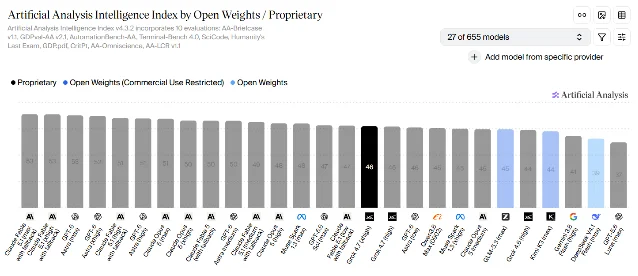
The index weights ten separate evaluations. 3 Where SpaceXAI sells the model on price-performance, Artificial Analysis has published no speed or cost figure for it at all, and records 240 million output tokens spent running the index against a median of 92 million. 3 The position comes with a lot of tokens per task.
Before you build on it
Grok 4.7 Fast, the variant served at twice the token rates, runs only in Cursor and Grok Build and is not on the public xAI API. 6 Above a 200k-token prompt the standard price doubles, and the US regional endpoint that keeps inference in the United States carries a 10% premium. 6 Cursor, Grok Build and the model gateways OpenRouter, Vercel and Cloudflare all serve the model today. 56
SpaceXAI says Grok 4.7 runs an entirely new safeguard stack and is the strongest model it has tested against refusals and jailbreaks, topping LatchBio's biosafety benchmark at 62.4% and letting 3.3% of risky dual-use cyber prompts through on HackerBench v0.3, a benchmark SpaceXAI owns. 1
References
- 1
- 2xAI joins SpaceX
x.ai
- 3Grok 4.7 (xhigh) - Intelligence, Performance & Price Analysis
artificialanalysis.ai
- 4
- 5SpaceXAI developer release notes
docs.x.ai
- 6Grok 4.7 API overview
docs.x.ai
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.