Terminal-Universe Turns Frozen Agent Traces into Reusable Coding Environments
Terminal-Universe shows how historical coding-agent traces can become verified, reusable terminal environments—and lays out a bounded pilot for testing whether they improve training and evaluation.

A coding-agent trajectory tells you what one agent did once. A runnable terminal environment lets another agent try the task again, inspect the result, recover from a failure, and face an independent check. That difference turns old traces into possible training and evaluation material.
A paper posted on September 3, 2026, called Terminal-Universe, makes that conversion its central idea. DAIR.AI drew attention to the paper on September 4, and a short explainer appeared later that day in the channel's time zone. 123
The PM question is specific: can reconstructed workspaces produce better, more varied coding-agent tests at a cost and reliability level that justifies a controlled experiment?
The shift: from logs to workspaces
A trajectory is a frozen record of messages, tool calls, file edits, and outcomes. A workspace is a state that a new agent can open, query, change, and submit for verification. Terminal-Universe reverses the usual direction: instead of collecting fresh environments first and then recording trajectories, it starts with trajectories and reconstructs the environments that made those trajectories possible. 1
The distinction matters because a log can preserve a successful path while hiding the conditions around that path. A runnable workspace exposes files, dependencies, tools, state, and a verifier to a second attempt. The second attempt can then generate evidence about recovery, alternative strategies, and failure modes.
What the system actually builds
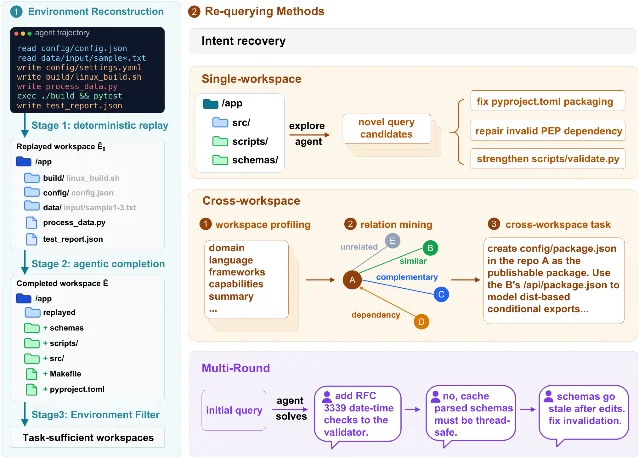
Terminal-Universe uses three reconstruction stages.
- Replay restores the starting point. The pipeline deterministically replays
read,write, andeditoperations to recover files before the original agent changed them. Replay supplies the parts of the environment that the trajectory explicitly touched. 1 - Agentic completion fills the gaps. A separate agent adds missing files and dependencies needed to make the task runnable. The completion agent prepares the workspace rather than solving the original task, preserving room for a later query. 1
- A judge keeps task-sufficient workspaces. An agentic judge checks whether the reconstructed workspace contains enough structure to support the task. A task-sufficient environment therefore means a workspace that can accept a new task attempt under the paper's evaluation setup. 1
The paper then supports four ways to query the reconstructed material:
- Intent Recovery turns an existing trajectory into a fresh task statement.
- Single-workspace synthesis creates additional tasks inside one reconstructed workspace.
- Cross-workspace synthesis combines related workspaces to create a broader task.
- Multi-round sessions let requirements evolve across rounds while a verifier returns feedback and the agent repairs its work. 1
The completion stage carries the main leverage and the main risk. Replay alone recovers only what the original trace touched. Agentic completion can make the workspace usable, yet every added file or dependency becomes a reconstruction decision that needs verification.
Why the numbers matter
The paper reports scale and benchmark movement under a named research setup: standardized
ubuntu:24.04 containers, network access, specified models and scaffolds, deduplication, parser settings, resource limits, and timeouts. The values below describe that setup rather than a general production guarantee. 1| Question | Reported result | PM reading |
|---|---|---|
| How much material was reconstructed? | 68,263 environments were reconstructed before final filtering; 38,294 were evaluated after deduplication. 1 | The approach targets environment supply, rather than a single prompt-generation trick. |
| How much does completion add? | Replay alone reached 40.2% sufficiency; replay plus agentic completion reached 93.5%. 1 | Completion is the lever to test first, with verifier precision as its companion metric. |
| How many usable environments remained? | The final task-sufficient set contained 37,273 environments, summarized by the authors as 37.3k. The verifier-filtered SFT corpus contained 31,977 records, or about 32.0k. 1 | Filtering removes unusable volume; accepted environments are the product asset. |
| Did fine-tuning move benchmark results? | Qwen3.5-27B moved from 46.2 to 58.1 on Terminal-Bench 2.1, a +11.9-point change. EvoCode-Bench v2 MT@4 moved from 6.3 to 20.1, a +13.8-point change. 1 | The gains justify replication on a private, held-out task split before any adoption decision. |
The benchmark movement has useful detail behind it. Source-trajectory SFT averaged 36.7 on the paper's Terminal-Bench 2.1 comparison, while Intent Recovery averaged 52.1. Multi-round retained sessions averaged 4.51 rounds, and 69.6% contained a failure that was repaired later. 1 Those figures make recovery and task diversity first-class test variables for a PM pilot.
Why a PM should care
The proposed asset is a reusable, verified test environment. It can support training examples, regression tasks, failure-recovery tests, and new task variants while the underlying repository state stays controlled. A team that currently spends engineering time hand-building terminal tasks could instead use existing agent activity as raw material for an environment factory.
That factory still needs a harness around it. Anthropic's guidance on agent evaluations treats the model and the harness as one measured unit: a complete trial includes the task, environment, transcript, outcome, graders, and end-to-end evaluation code. Anthropic also recommends stable isolated environments, outcome verification, and tracking latency, tokens, cost, tool calls, and final state. 4
The paper's reconstruction process fits that pattern. The workspace is the environment layer; the original trajectory supplies history; the completion agent supplies missing setup; and the sufficiency judge supplies an admission filter. The PM-owned question is whether the resulting environments improve a real evaluation or training loop after private data, reset behavior, and independent verification are added.
A bounded pilot
Start with one resettable internal coding workflow, such as fixing a class of test failures in a sandboxed repository. Keep the experiment narrow enough for every accepted workspace to receive a human-auditable verdict.
- Freeze the boundary. Select a repository family, task type, tool set, container image, scaffold, parser, model version, CPU and memory limits, timeout, and network policy. Store the original trajectory, workspace snapshot, dependency manifest, and verifier output for every reconstruction.
- Build three comparison arms. Compare the current training or evaluation pipeline, supervised fine-tuning on raw trajectories, and fine-tuning or evaluation with reconstructed task-sufficient environments. Hold the model family, prompt budget, task split, and optimizer settings fixed where the experiment permits.
- Create a private holdout. Reserve repositories, tasks, and failure patterns that never enter reconstruction prompts, completion context, or verifier tuning. Run fresh seeds and repeated trials so a single memorized path cannot carry the result.
- Verify the workspace before scoring the agent. Check file presence, dependency installation, tool availability, initial state, and reset reproducibility. Use authoritative outcome checks such as tests, state diffs, or repository-native validators. Route grader disagreements to human review.
- Instrument the full loop. Record verified completion, pass@1 or repeated-trial consistency, recovery after failure, task diversity, workspace sufficiency, verifier precision and false acceptance, latency, tokens, GPU cost, cost per accepted task, contamination signals, human review time, and side effects.
The pilot should also pin infrastructure. Anthropic reported that infrastructure configuration changed Terminal-Bench 2.0 results by as much as six percentage points in one experiment, with infrastructure errors falling from 5.8% under strict limits to 0.5% without those limits. 5 A reconstructed-environment result needs the same discipline: otherwise a better container or a looser timeout can look like a better training method.
Decision gate
Write the hypothesis before running the pilot: reconstructed, verifier-approved workspaces will improve verified completion or recovery on held-out coding tasks by a meaningful margin at an acceptable cost, compared with raw-trajectory training and the current pipeline.
Advance to limited use when four conditions hold:
- the gain survives held-out repositories, fresh resets, repeated seeds, and fixed scaffold and resource settings;
- independent outcome checks agree with the task result and the false-acceptance rate stays within the workflow's risk budget;
- the added completion, judging, storage, and inference cost fits the value of each accepted task;
- contamination, unauthorized side effects, and workspace drift remain observable and reversible.
Keep the current training and evaluation pipeline as the rollback path. Terminal-Universe supplies a way to turn historical agent work into runnable experiments. The PM decision depends on whether those experiments remain valid after the team's own repositories, verifiers, resource limits, and failure cases enter the loop.
References
- 1
- 2
- 3
- 4Demystifying evals for AI agents
anthropic.com
- 5
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.