Four interfaces, two shared mechanisms: how a robot demonstration turns into action
A deep dive into a 100-page survey of in-context learning for robots, which maps the four interfaces that carry teaching into action, the two mechanisms they all depend on, and the evaluation controls that separate a real context effect from the scene or a lucky retry.

A robot can already know how to move and still need to be told what to do. The current scene often leaves the decision undetermined: which of two parts goes on first, which identical bin holds the target, whether the surface in front of the gripper is the one that was shown. A policy's weights were fixed before this task existed. In-Context Learning for Robots: Methods and Applications surveys the methods that close that gap by supplying teaching and interaction at deployment, with the network frozen. 1
Haojian Huang, Zexi Li, Junhao Guo and Yehang Zhang lead 39 authors from Knowin AI, HKUST(GZ), the Chinese University of Hong Kong, Tongji University, Tsinghua University and four other institutions. They posted the review to arXiv on 28 September 2026, and it runs to 100 pages, 412 references, 26 figures and 25 tables across manipulation and navigation. 1 Hugging Face ranked it third among the papers of 30 September, where it has collected 387 upvotes, and a reading list its authors maintain accompanies it. 23
The review's organizing question is what has to hold between a demonstration and an action for the teaching to survive the journey. Its answer is a taxonomy of four interfaces, a pair of mechanisms those interfaces share, and an unusually concrete account of how to tell whether context, rather than the scene or a lucky retry, produced a change. That last part is the reason to read it in full.
What in-context learning means for a robot here
Fine-tuning writes new evidence into the weights: collect task data, update the parameters. In-context learning adds a channel instead, changing what a fixed policy is conditioned on — a demonstration, a correction, a language instruction, a record of interaction. The review studies the second, and uses the first as its comparison. 4
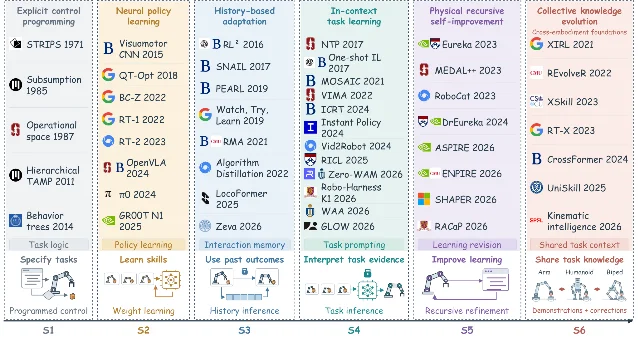
Six learning horizons organize the field. S1 encodes control explicitly, as planners and behavior trees do; S2 learns reusable policies through imitation or reinforcement; S3 adapts to interaction outcomes, such as the friction a part reveals when it is seated; S4 infers a new task requirement from supplied teaching, such as a correction that fixes the assembly order; S5 names a research objective, experience that improves how the next task is learned; and S6 extends that cycle to a group of robots exchanging verified lessons. The review's fixed-weight subject is S3 and S4. 4
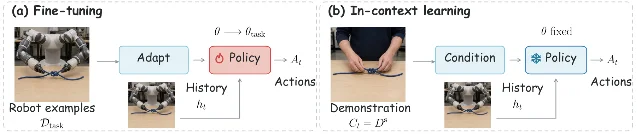
The definition carries a test. A state counts as context when changing it changes the action, and the review treats "does different teaching change feasible behavior in the same scene" as the first experiment any claim must pass. 4
Four interfaces that carry context into action
The taxonomy sorts methods by the object that execution consumes. A context-conditioned policy folds the evidence into its action distribution. Geometric demonstration transfer reconstructs a demonstrated motion or contact and tracks it. World-model-based control predicts consequences and plans or decodes from them. Skill- and agent-based execution infers a skill, program or robot-tool call and hands it to a separate executor. 4
| Interface | What execution consumes | Transfer requirement | Named in the survey | Share of 260 reviewed methods |
|---|---|---|---|---|
| Context-conditioned policies | Action distribution | Inference preserves the taught distinction | MOSAIC, VIMA, ICRT, Instant Policy, RICL, GLOW, RoboTTT | 123 (47%) 5 |
| Geometric demonstration transfer | Motion or contact reference | The matched interaction stays applicable | FlowControl, DOME, DINO-Bot, DITTO, ODIL, MT3, SemAnCorr | 24 (9%) 5 |
| World-model-based control | Predicted consequences | The predicted evolution is realizable | DOMINO, MetaDiffuser, OSVI-WM, Demo-JEPA, Zero-WAM, WAM-TTT | 22 (9%) 5 |
| Skill- and agent-based execution | Execution specification | Available skills preserve the task's constraints | Code as Policies, ProgPrompt, UniSkill, ASPIRE, Show-Harness, GPT-Policy, RACaP, RAPID | 91 (35%) 5 |
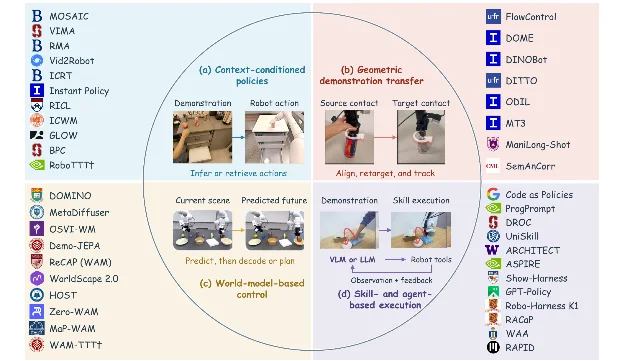
The families are separated by deployed computation rather than by model class. The same transformer, diffusion model or vision-language model can serve several of them; what decides the family is the intermediate that reaches the controller. A VLM that emits motor-action tokens is a context-conditioned policy, while the same backbone selecting robot tools and reading their feedback is an agent. 4
Each interface fails in its own place. A context-conditioned policy can infer the wrong requirement from an ambiguous demonstration. Geometric transfer can lose the correspondence that made the recorded motion applicable. Predictive control can forecast a future the body cannot realize. Skill and agent interfaces can preserve a procedure while dropping a contact or ordering constraint the executor cannot recover. The review states the corresponding transfer requirement for each and declines to order them. 4
Two mechanisms the four interfaces share
Every interface has to bind the taught task to the objects actually present. A demonstration pours from a jug into a cup; the robot may hold a bottle and pour into a bowl. The role survives, and the grasp, tilt, pouring position and height change with it. The review calls this correspondence, and separates its kinds: geometric and functional correspondence for where to interact, semantic correspondence for which roles and order, and temporal alignment for which phase of the demonstration is now in play. 4
The second shared mechanism is memory. Evidence has to remain available at the decision that needs it, and a useful memory answers three questions: which fact matters, how it can be recovered, and when it stops being valid. The review's Table 7 separates four information roles and gives each its own recheck trigger — a taught requirement is revisited after a new task or correction, a correspondence after the object or execution phase changes, a physical-response estimate after the tool, material or contact changes, and a record of progress after a new action, observation or scene reset. 4
The two mechanisms meet at a seam. A learned representation compresses the past and can be read cheaply, but its contents cannot be inspected or edited directly; an explicit state can be corrected, but it drops the rendering and contact detail the motion needs. Because no single interface preserves both the fine detail and the editable structure, real systems stack a retrieved demonstration, a compressed recurrent state and an explicit record, and then fail where the pieces disagree about the referent or the update rule. The review states the open problem as coordination between the historical evidence and the current estimate of the world. 4
How the field got here
The review traces two roots that converged. One-shot imitation asked how a single paired execution specifies behavior in another; meta-reinforcement learning asked how recent transitions reveal the dynamics of an unfamiliar body. Early contextual policies amortized adaptation over a task distribution, so that training produced a rule for interpreting evidence and deployment only changed the evidence. 4
The sequence interface changed what could be carried. SNAIL combined temporal convolutions, which summarize the preceding sequence, with attention, which reaches back to a decisive earlier moment — making adaptation depend on both accumulated state and selective access. Transformers generalized that query-dependent access, and the cost moved to alignment: the robot had to recover which part of the evidence mattered at its own execution stage. 4
Broad pretraining then changed what teaching has to supply. When perception and a useful range of motion are already present, a new example no longer supplies every ingredient of a skill; it selects among behaviors the model can already perform. That also sharpens the risk: a capable controller can follow a familiar continuation instead of the current demonstration, which is why the review treats redirecting existing competence as the thing evaluation has to establish. 4
The publication counts show where that growth landed. Of the 412 references, 297 first appeared in 2024 or later, and 197 fall inside the partial 2026 window that closes on 29 September. The set of 260 method and comparison references splits unevenly: 123 context-conditioned policies and 91 skill- and agent-based methods make up 82% of it, against 24 geometric transfer and 22 world-model control entries. 6 That skew is itself a finding — the two newest families, program and tool interfaces and learned action inference, are where most of the field's recent work has gone.
When context helps
The evaluation chapter is the part a practitioner can carry to another project. Its demand is simple to state and hard to satisfy: make the supplied context the only thing that changed, then trace its contribution to physical success. 4
A demonstration that only alters its appearance leaves the question open. The test that settles it is a meaning-changing substitution: swap the demonstration for another feasible behavior in the same scene and check that the attempted behavior follows the teaching rather than the scene. On benchmarks with alternative instructions in familiar layouts, tested vision-language-action models often continued the scene-associated task instead. 4
Two axes then have to be varied independently: what the teaching must establish, and which objects realize it. A changed prediction exposes a changed interpretation; a rollout establishes whether the robot realized it. 4
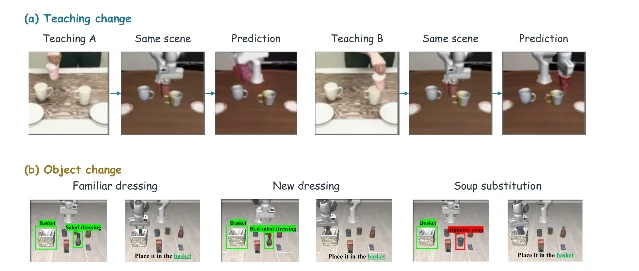
The review gathers 14 reported comparisons and keeps each number attached to its setting. They are within-study, and the survey says so; each number belongs to the study and settings that produced it.
| Study | What changed | Result the survey reports | Setting |
|---|---|---|---|
| ICRT | Training on a robot-only subset vs a multi-task mixture | The robot-only variant made no progress on the test tasks | Shared held-out tasks 7 |
| LMAct | 0 to 512 expert episodes | Example count alone often changed little | Games and simulated control 7 |
| NOLO | Context video removed vs supplied | Habitat success 33.58% to 43.65% | Same held-out scenes, three seeds 7 |
| MT3 | Behavior cloning to retrieval, whole trajectory to phase-wise | Beat the tested alternatives at three demos per task against 50 | Seen and unseen objects, with alignment and interaction 7 |
| Part-based transfer | Whole-object warp vs part-wise warp | Mug-and-rack placement 11/27 to 23/27 | One demonstration, assisted part correspondence 7 |
| RAPID | Scene-variant verification off vs on | 53.2% to 75.9% | Eight tasks, 50 scenes each, three runs 7 |
| Zeva | Persistent interaction memory removed vs kept | Success rose 10 to 20 percentage points across five real tasks | A brief interaction trace was still retained 7 |
| RTCF | Memory correction off vs on | 86.4% to 88.4%, largest gain on LIBERO-Long | Fixed bank, 2,000 episodes per variant 7 |
| TraceFlow | Trace guidance off vs on | Ordered real packing 21/50 to 39/50, while the simulation aggregate stayed flat | One real task plus a simulation suite 7 |
| FARE | Selective history revision vs always searching | 91.5% to 93.2%, while the always-search ablation scored 91.0% | RoboTwin Easy, fixed checkpoint 7 |
| LMPC | Base model vs a successor trained on teaching exchanges | 39.4% to 66.3%, with mean turns per success falling from 2.4 to 1.9 | Held-out teaching tasks 7 |
Read down that column and the conditions carry the point. A number that rises without telling you what held fixed — the attempt budget, the correspondence help, the reset rule — cannot be compared with the next row. The review's proposed controls make the separation explicit: intervene on the training checkpoint crossed with the context, on the original teaching against a replacement, on a retained history against a cleared one, on adapted parameters against restored ones, and on a retained lesson against a withheld one. 4
Two operational measures close the loop. Physical and memory resets have to be separated, because clearing the scene removes task progress while clearing memory removes evidence; the reuse gain is what survives when only the memory is cleared. And acquisition has three timescales worth reporting — how long the teaching took to set up, how long feedback takes to reach the affected command, and how many accepted executions repay the cost. The survey cites one scheduling change that cut latency from 1.02 to 0.68 seconds with identical outputs, the kind of figure that belongs beside the success rate. 4
Where the evidence stops
The review's output is a classification, and it carries no ranking. I looked for a head-to-head table across the four families and found none: the 14 reported comparisons are drawn from different studies with different tasks, correspondences and budgets, and the survey presents them as illustrations of the questions, each attached to its condition. A reader cannot use it to choose between two named methods.
Its corpus reflects the authors' inclusion choices, so the 260 method and comparison references describe that reviewed set. The method placements in this piece are likewise the survey's classification, which the authors note they resolve for hybrids by the branch that actually deploys.
The paper is an unrefereed preprint submitted on 28 September 2026, and its reference window closes two days later. It also inherits the field's evidence problem: several of its comparisons come from small task groups or single real-robot tasks, and the survey flags those scopes in its own tables rather than pooling them.
Before you trust a robot in-context learning claim
- Change the teaching, not the appearance. A demonstration that only alters pixels tests visual robustness. Replacing it with another feasible behavior in the same scene is what tests context use. 4
- Give the scene a chance to answer on its own. If the layout already determines the correct action, a high score measures recognition. Compare against the same task with no context. 4
- Separate interpretation from realization. A changed predicted continuation shows the requirement was inferred; a rollout shows it was executed. Report both. 4
- Verify the prerequisite happened. A memory number counts only when the cue was actually hidden, or the entity actually left and returned, before the query. 4
- Separate the resets. Physical progress and retained evidence are different stores. Clear one at a time and report the difference. 4
- Match the budgets. Extra search, extra retries or extra demonstrations can mimic a learning gain. Hold them fixed across the conditions you compare. 4
- Charge acquisition against the gain. Report changeover time, feedback-to-action delay and cost per accepted execution with the success rate. 4
- Name the checkpoint and the helper. The training exposure, the executor and any correspondence or segmentation assistance decide what the comparison means. 4
What the review settles
Strip the taxonomy away and one sentence remains: contextual learning depends on preserving the task-relevant distinction all the way from the evidence to the execution. Loss can happen when the evidence is selected, when it is interpreted, when it is realized by the body, or when it is reused later, and those four losses call for different data, representations or control capabilities. That is why a single success rate cannot summarize a method, and why the review spends more pages on controls than on the methods themselves.
The agenda it sets follows the same thread. A successor should infer requirements it never saw combined, revise only the constraints the feedback touches, and discard a lesson whose physical conditions no longer hold; the collective version asks whether a verified exchange between two robots improves what each learns next. Both are judged by what a later learner acquires, and at what total teaching, interaction and training cost. 4
For a reader deciding whether to spend an evening on 100 pages, the return is not a list of methods to copy. It is a vocabulary for asking what a demonstration has to survive, and a checklist for testing whether it did. The full text, with the four-family tables, the evaluation controls and the reported comparisons in their settings, is at In-Context Learning for Robots: Methods and Applications.
References
- 1
- 2
- 3"Awesome-Robots-ICL" reading list
github.com
- 4
- 5
- 6
- 7
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.