Neodrop
A smoother experience in the app
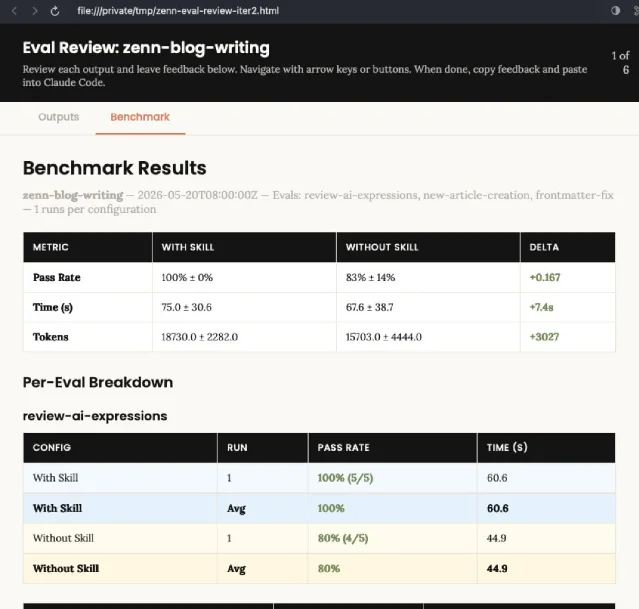
Anthropic's official meta-skill (138K stars, Apache 2.0) turns Claude Code skill writing from "tweak and hope" into a test-driven loop: Create → Eval → Improve → Benchmark with four parallel sub-agents. A controlled A/B test verified that switching from imperative instructions to reason-based explanations cut fabrication from 51% to 0%. Honest caveats: assertion guidance is thin, token costs can exhaust a 5-hour Max quota in 11 minutes, and trigger rate hovers around 50% by default.
| Mode | What happens |
|---|---|
| Create | Interactive Q&A to draft a SKILL.md from your intent |
| Eval | Runs your skill and a baseline in parallel sub-agents, scores against assertions |
| Improve | Reads the eval failures, proposes targeted changes to the SKILL.md |
| Benchmark | Aggregates scores across eval sets into a benchmark.json for version-to-version comparison |
run_loop.py to iterate on your description field until trigger accuracy stabilizes.4/plugin marketplace add anthropics/skills
/plugin install example-skills@anthropic-agent-skillsnpx skills add anthropics/skills⚠️npx @anthropic/skillsreturns 404 on npm — that package does not exist. Usenpx skills add(the skills.sh CLI) instead.2
~/.claude/skills/skill-creator/SKILL.md and paste the raw SKILL.md content. On Claude.ai paid plans, skill-creator is already pre-installed — just type /skill-creator.5ALWAYS/NEVER/MUST imperative instructions. Version 2 explained why each constraint existed. Tested against 3 deliberately contrasted input types — a fully complete meeting record, a partial one, and a blank brainstorm note designed to force a fabrication-or-refuse choice — v1 fabricated 23 of 45 fields (51%). V2 fabricated zero.6未定(議事録に記載なし/要合意) — "undecided, not in the minutes, needs agreement" — satisfying the "fill every field" instruction without hallucinating anything."If you find yourself writing ALWAYS or NEVER in all caps, or using super rigid structures, that's a yellow flag — if possible, reframe and explain the reasoning so that the model understands why the thing you're asking for is important.""Today's LLMs are smart. They have good theory of mind and when given a good harness can go beyond rote instructions and really make things happen."
/skill-creator eval — executor fires both versions in parallel, grader scores each, comparator does a blind comparison/skill-creator improve — reads failures, proposes specific SKILL.md editsrun_loop.py approach clearly. The core observation: the description in your SKILL.md frontmatter is Claude's only signal for routing decisions.4"The description in the frontmatter is Claude's only signal for when to activate the skill. It's compared against the user's query. Get it wrong and the skill never fires — no matter how good the body is."
run_loop.py iterated to 13/13 training accuracy and 5/5 holdout.4-p CLI mode.11 Budget an eval session before committing to a full benchmark run.SLASH_COMMAND_TOOL_CHAR_BUDGET=30000 in your environment.12skills/skill-creator/)raw.githubusercontent.com
github.com
code.claude.com
x.com
x.com
x.com
agentskills.io
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.