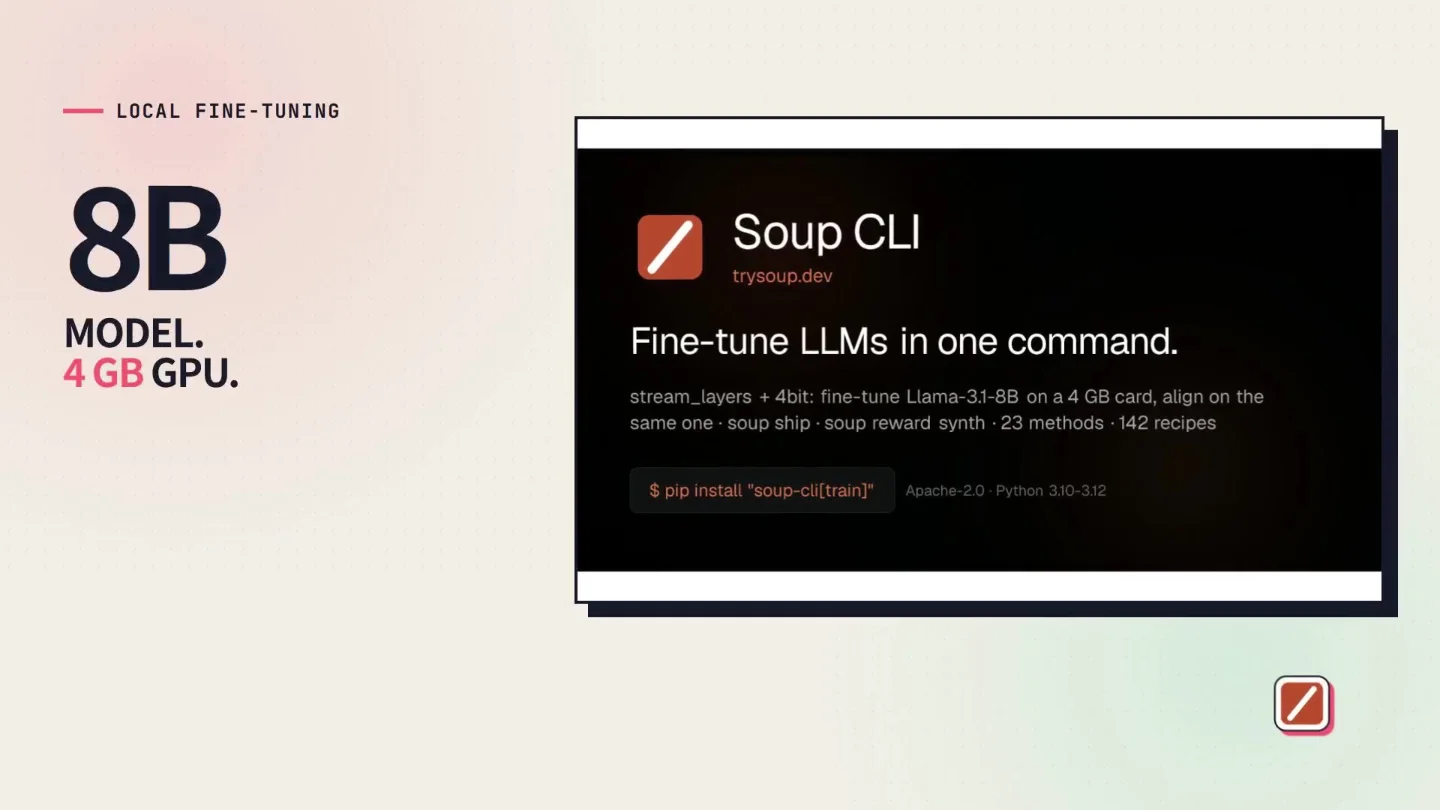
Soup CLI fine-tunes an 8B model on a 4 GB laptop GPU
Soup CLI's beta layer-streaming mode keeps the frozen base model in system RAM or on NVMe, then copies one decoder layer into the GPU at a time. The project's RTX 3050 laptop test fine-tuned Llama 3.1 8B with a 3.32 GB peak on a four-gigabyte card. 1
The reported 119.6 tokens per second needs a qualifier: it was measured before the version 0.73.0 correctness repair and has not been rerun on that laptop. The project later reproduced the same 3.32 GB memory peak on an H100, but that remains project-published testing rather than a broad independent benchmark. 2
The practical takeaway: Soup makes local fine-tuning look possible on hardware that normally cannot hold an eight-billion-parameter model in VRAM. You still need enough system RAM or NVMe storage, Python 3.10 through 3.12, and patience for a beta path that can be slower than resident training. 2
References
- 1Soup CLI repository
github.com
- 2Soup CLI — layer streaming details
trysoup.dev
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.