Mistral Large 4 scores 82% on the cyber test Claude and GPT-6 refuse to take
Mistral's trillion-parameter flagship posts a real cybersecurity score, a mid-table position on the independent index, two published prices for the same tokens, and weights due only after the preview they describe.

"ML4 pushes the frontier of open-weight performance."
That is how Mistral opens the announcement for Mistral Large 4, published on 6 October, and the same post dates the weights to "end of this month" 1. Until they arrive, the frontier open-weight performance on offer is a public preview through Mistral's API.
Mistral has earned some benefit of the doubt on that sentence. The French lab shipped its first models in 2023 and has since closed a €3 billion Series D led by Samsung Electronics at a valuation above €21 billion, with Airbus, ASML and HSBC among its customers 2. Large 4 is its biggest model yet, and the sales pitch is that a European enterprise can run frontier-class work under its own policy.
The engineering here is substantial. The interesting part is what Mistral chose to lead with, because the number it leads with is partly a measurement of what its competitors declined to do.
What the thing actually is
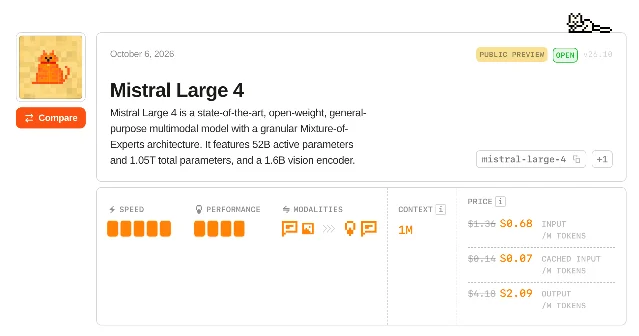
Mistral Large 4 is a sparse mixture-of-experts model with a trillion parameters in total and roughly fifty billion active per token. "Roughly" is doing real work there. The launch post says 49 billion active 1, and the model page dated the same day says 52 billion active, with 1.05 trillion parameters in total and a 1.6-billion-parameter vision encoder 3. Anyone quoting a parameter count for this model is quoting one of those two pages.
It takes text and images in and returns text, over a context window Mistral puts at one million tokens 3. Mistral trained it from scratch on 3,800 Nvidia Grace Blackwell GPUs in its own European datacentres, on a corpus spanning more than 160 languages 1. The reinforcement-learning run behind the preview is still going, and Mistral says the model shows "no signs of saturation" 1. Everything below is a reading of a model its own maker describes as unfinished. The launch itself was meant to happen in the summer 4.
The number Mistral leads with
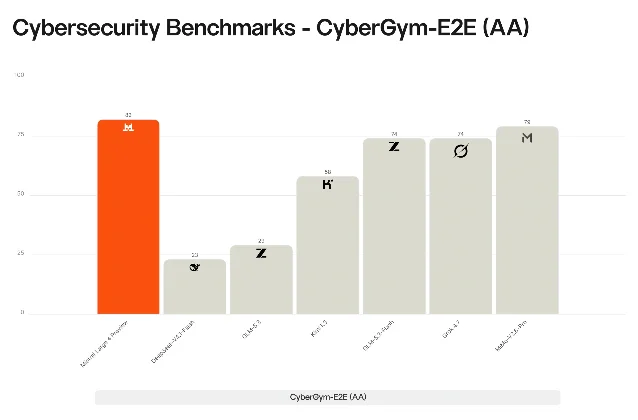
Mistral gives the largest share of the announcement to security, and the headline figure is 82%. On a test that asks a model to reproduce a real vulnerability in open-source software and then patch it, ML4 scores 82%, the highest score of any model in the field 1.
Mistral explains why, and the explanation is the story. Several leading closed models, "including Claude Opus 5.5 and GPT-6 Astra, score near zero on the same test because they refuse to perform the task" 1. The row is scoring two things at once: whether a model can do the work, and whether its maker will let it. The Decoder put the consequence plainly, noting that the test therefore measures provider policies as much as model capabilities 5.
Anyone who has spent an afternoon trying to make a hosted model finish a live incident response will recognise the second half as the part that usually blocks them. The gap Mistral is selling is real. It is also a gap that opens and closes with other companies' policy documents.
| Benchmark | Mistral Large 4 | Nearest rivals | What the row measures |
|---|---|---|---|
| CyberGym-E2E, Artificial Analysis | 82% 1 | MiMo-V2.6-Pro 79%, GLM-5.3-Flash 74%, Grok 4.7 74%, Kimi K3 58%, DeepSeek V4.1 Flash 23% 1 | reproducing a real vulnerability, then patching it |
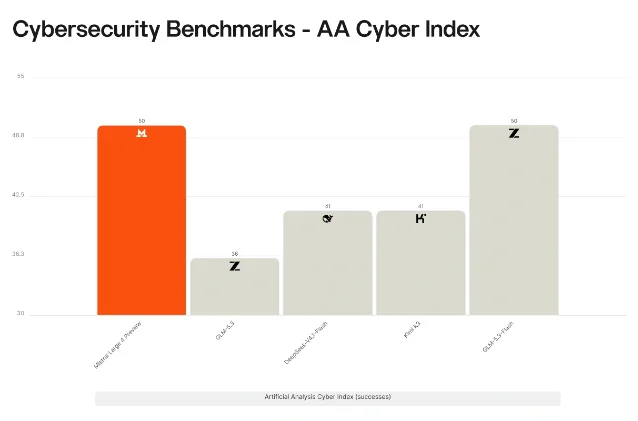
| AA Cyber Index | 50 1 | GLM-5.3-Flash 50, DeepSeek V4.1 Flash 41, Kimi K3 41, GLM-5.3 36 1 | finding and fixing security flaws across a bank of tests |
| DeepSWE v1.1 | 61.7% 1 | GLM-5.3 61%, DeepSeek V4 Pro 57%, Qwen3.8 Max 51% 4 | agentic coding, the skill Mistral sells it on |
| Dense200 | 42% 1 | GPT-6 Astra 41% 4 | locating objects inside an image |
Read Mistral's own chart of the Artificial Analysis Cyber Index and the margin narrows sharply. ML4's bar reads 50, and so does the bar for Z.ai's GLM-5.3-Flash 1. The sentence above it claims ML4 "leads open-weight models developed outside China by a wide margin" 1. Both statements hold together, and the qualifier is where the size went: the wide margin is over models built in the United States and Europe, and Mistral makes no such claim against the best Chinese open models 4.
There is a second half to the security pitch, and Mistral states it in the same section. The model also has a higher average refusal rate on malicious cyber prompts, drawn from JailbreakBench, StrongREJECT and AgentHarm, than any other open model 1. It blocks 93.3% of attacks on Lakera's B3 agent security benchmark 1.
Both claims can be true at once. Mistral publishes no account of how the model separates vulnerability research from attack preparation, and reporting on the launch has not produced one either 5. That mechanism is the whole product for a security team, and it currently rests on Mistral's word.
Where it stands when someone else keeps score
Mistral's own benchmarks put ML4 within a point of the best open models on coding and level with them on finance. Then there is the scoreboard Mistral did not run.
Artificial Analysis puts Mistral Large 4 Preview at 38 on its Intelligence Index, which combines ten evaluations that Artificial Analysis runs itself 6. Claude Opus 5.5 leads the same index at 58 7. Between them sit several open-weight models, among them MiMo-V2.6-Pro at 46, Qwen3.8 Max and GLM-5.3 at 45, Kimi K3 at 44 and GLM-5.3-Flash at 42 7.
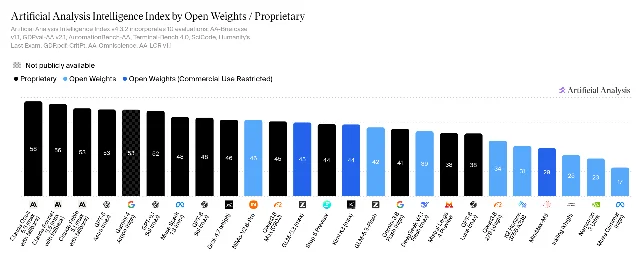
Set that against where Mistral has been. Its predecessor, Mistral Large 3, scored 9 on the same index, and the most recent Mistral Medium 3.5 reached 14 5. Coming from single digits to 38 is a genuine recovery, and it still leaves the model twenty points behind the leader and behind six open-weight rivals.
One operational detail does not appear anywhere in the launch. On the Intelligence Index, ML4 generated 200 million output tokens, against a median of 81 million across the models measured 6. Artificial Analysis calls the model "very verbose" and puts it at $1.13 per completed task 6. Price per token and price per finished job are different numbers, and here they pull apart.
What it costs, and what you can take home
Mistral lists two rates for the same tokens on the same page, and a buyer should know which one they will be billed at before signing anything.
| Line item | Lower published row | Higher published row |
|---|---|---|
| Input, per million tokens | $0.68 | $1.36 |
| Cached input, per million tokens | $0.07 | $0.14 |
| Output, per million tokens | $2.09 | $4.18 |
Source: Mistral's model page for Large 4 3.
The Decoder reports that the preview bills at the lower figure, with the higher one marked as the standard rate once the preview ends 5. Artificial Analysis prices the model at the higher one 6. The two published versions differ by exactly a factor of two, so ask which applies. The cache discount is worth the question too: a cached input token bills at $0.14 against $1.36, a tenth of the rate 6.
Taking the model home has to wait. Mistral dates the weights, the architecture details, the extra benchmarks, the post-training method and the licence all to the end of October 15. Until then, the routes in are the API through Mistral Studio 8 and a red-teaming programme.
That programme deserves a second read. Cybersecurity leaders, "vetted partners" and state authorities get the same model "with reduced moderation and expanded cyber capabilities" 1. So the group whose refusal problem is already solved is a vetted list, and for everyone else the route in is the API. Because the capability can be pointed at a target as easily as at a patch, Mistral also says it monitors traffic through that API 4. Traffic monitoring is a reasonable thing for a security vendor to do, and it is also the kind of provider-level control the launch text is written against.
The verdict
Judged as a release, Mistral Large 4 is a serious model with a narrow and genuine edge. It wins the one cyber test where the strongest closed models decline to compete, it lands mid-table on the general index, and it is priced low enough to try. The independence story is still a promise with a date on it: the weights, the licence and the architecture notes are all due at the end of the month, and every route into the model today runs through Mistral's own servers and its traffic monitoring.
So the fit is specific. If you run a security team that keeps hitting refusals on hosted models, and you can work through an API, the preview is worth a week. If your reason for wanting ML4 is the reason Mistral leads with, a model you can run under your own policy on your own hardware with no provider able to change its terms, then you are waiting for the end of October with everyone else.
One condition. When the weights and the licence land, read the licence before the benchmarks. If it restricts commercial use, the sovereignty argument shrinks into a hosted relationship with a European vendor. That may still be exactly the purchase you want, and it is a smaller one than the launch describes.
References
- 1Introducing Mistral Large 4
mistral.ai
- 2
- 3Mistral Large 4, Mistral Docs
docs.mistral.ai
- 4Mistral Large 4: Europe's A.I. Hope Is Back
trendingtopics.eu
- 5
- 6Mistral Large 4 Preview, Artificial Analysis
artificialanalysis.ai
- 7Artificial Analysis Intelligence Index
artificialanalysis.ai
- 8Mistral Studio
console.mistral.ai
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.