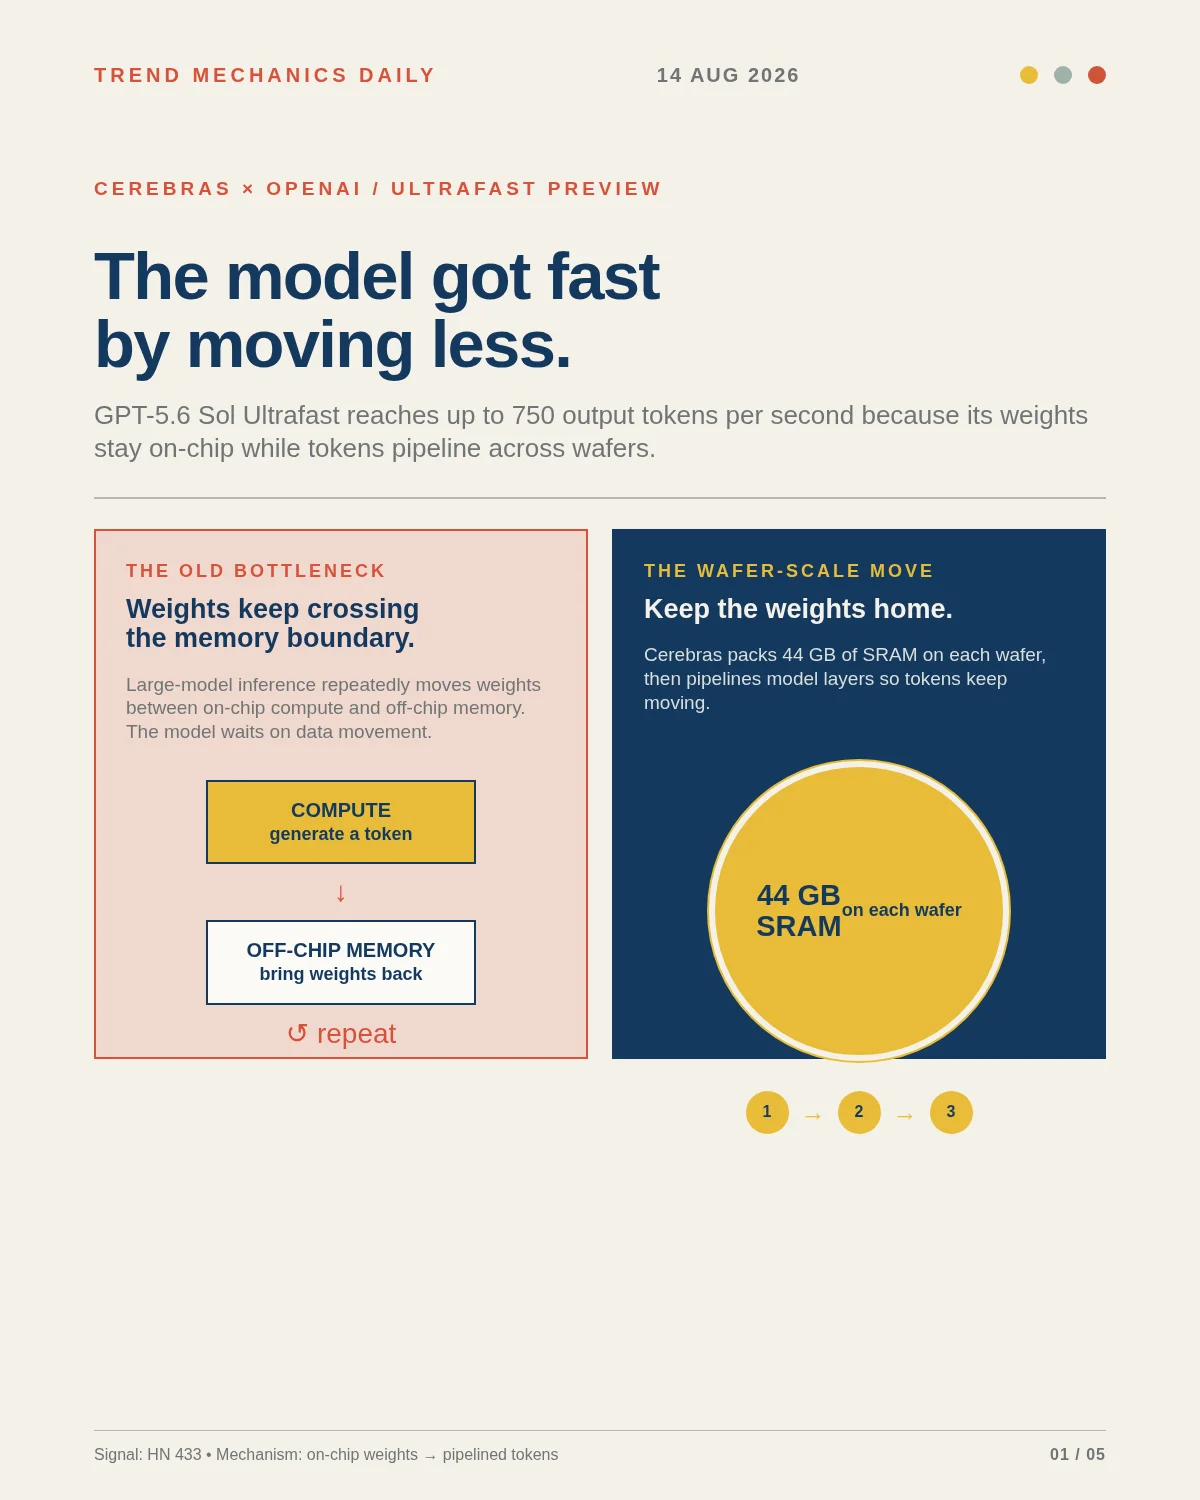

On Aug 13, Cerebras and OpenAI previewed GPT-5.6 Sol Ultrafast: up to 750 output tokens per second and up to 14× Standard processing in the OpenAI API, initially for a select group of customers. The launch had reached 433 points on Hacker News when checked. 123
Why is it fast? Cerebras describes frontier inference as a data-movement problem. On GPUs, large-model weights must be moved between on-chip memory and off-chip storage while generating successive tokens. Its wafer-scale design packs 44 GB of SRAM on each wafer, keeps weights on-chip, and pipelines tokens through model layers across wafers. Less repeated movement leaves more bandwidth for the token stream. 2
That matters because shrinking the wait changes the workflow: OpenAI points to incident response, live research, voice support, and other interactive work where the situation is still changing. The boundary is just as important: this is a limited preview, and Cerebras says performance comparisons can vary by workload, configuration, date, and models tested. Speed changes the interface; it does not remove the need to judge the result. 12
References
- 1OpenAI Ultrafast preview
openai.com
- 2Cerebras: Accelerating GPT-5.6 Sol Ultrafast
cerebras.ai
- 3Hacker News item
news.ycombinator.com
Comments