Neodrop
A smoother experience in the app
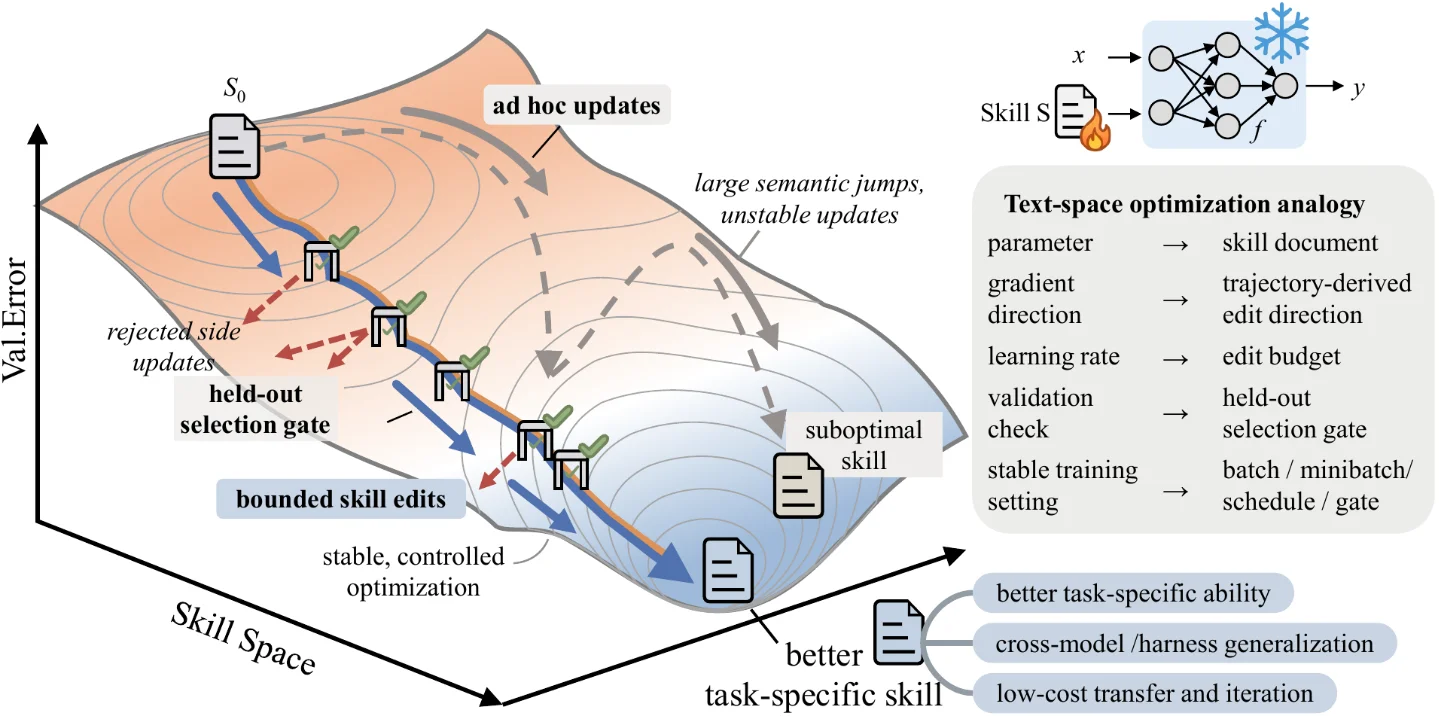
Microsoft Research's `microsoft/SkillOpt` (MIT, 8.2K stars, v0.1.0) is a Python framework that replaces manual skill-file guessing with a validated, bounded training loop — rollout → reflect → aggregate → select → update → gate — applied to your agent's Markdown skill document while the LLM itself stays frozen. On GPT-5.5, it averaged +23.5 points across six benchmarks; a Codex-trained SpreadsheetBench skill transferred to Claude Code with +59.7 points. The June 15 SkillOpt-Sleep preview extends the same discipline to nightly offline self-evolution of your own coding-session transcripts.
best_skill.md file, typically 300–2,000 tokens, that your agent loads at runtime with zero extra API calls. 2"The breaking point isn't whether a team can change a skill, it's that they can't guarantee the change is an improvement. Three failure modes recur: no step-size control, so skills drift; no validation, so a fix that reads as reasonable gets written in and can quietly regress performance; and no negative memory, so the same failed edit keeps coming back."
| Deep learning | SkillOpt text-space equivalent |
|---|---|
| Trainable parameter | Skill document (Markdown) |
| Gradient direction | Trajectory-derived edit patches |
| Learning rate | Edit budget per step |
| Validation check | Held-out selection gate |
| Momentum / slow update | Epoch-wise longitudinal reflection |
| Negative feedback | Rejected-edit buffer |
ReflACTTrainer and runs in six stages per optimization step: 2ADD / DELETE / REPLACE patches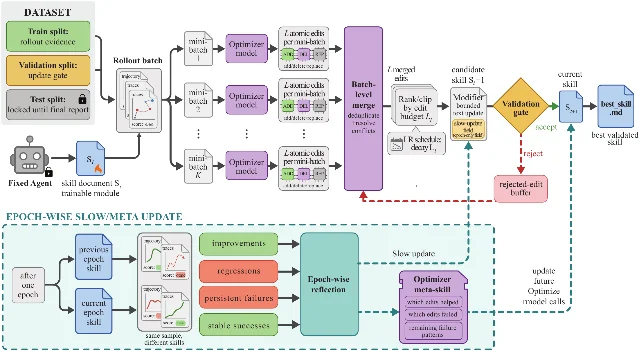
pip install skillopt          # core package, Python ≥3.10
pip install skillopt[claude]  # adds Anthropic Claude backend
pip install skillopt[webui]   # adds Gradio dashboard on port 7860
pip install skillopt[alfworld] # adds ALFWorld benchmarkpip install skillopt does not include it. Clone from GitHub instead. 5git clone https://github.com/microsoft/SkillOpt
cd SkillOpt
pip install -e ..env file (copy from .env.example). SkillOpt supports Azure OpenAI, plain OpenAI endpoints, Anthropic Claude, local Qwen via vLLM, and MiniMax. One quirk: it reuses AZURE_OPENAI_* env variable names even for plain OpenAI — there's no separate OPENAI_API_KEY knob. 4python -m skillopt_sleep.experiments.run_experiment \
--persona researcher \
--assert-improves# config.yaml
task: spreadsheetbench
target_model: gpt-5.4
optimizer_model: gpt-5.5
seed_skill: ./skills/my_spreadsheet_skill.md
epochs: 4
batch_size: 40
minibatch_size: 8
learning_rate: 4 # edit budget per step
lr_min: 2 # cosine decay floor
n_workers: 16python -m skillopt.run --config config.yamloutput/: best_skill.md, per-epoch snapshots in skills/, slow-update and meta-skill logs, and runtime_state.json for auto-resume. If the run is interrupted, re-running the same command picks up from the last completed step. 4# Claude Code — installs /skillopt-sleep command into plugin cache
/plugin marketplace add ./plugins/claude-code
# Codex
bash plugins/codex/install.sh # adds skillopt-sleep skill
# Copilot — register as MCP server
python plugins/copilot/mcp_server.pyplugins/run-sleep.sh is not copied into the plugin cache, causing sleep.sh to fail with a missing-runner error. Manual copy workaround: 7cp plugins/run-sleep.sh ~/.claude/plugins/skillopt-sleep/ClaudeCliBackend hardcodes a --bare flag that breaks subscription-token auth. If you're on a Claude subscription (not API key), every model call silently returns score 0 — the fix is pending in issue #68. 8| Benchmark | Before | After | Gain |
|---|---|---|---|
| SpreadsheetBench | 41.8 | 80.7 | +38.9 |
| OfficeQA | 33.1 | 72.1 | +39.0 |
| LiveMathematicianBench | 37.6 | 66.9 | +29.3 |
| DocVQA | 78.8 | 91.2 | +12.4 |
| SearchQA | 77.7 | 87.3 | +9.6 |
| ALFWorld | 83.6 | 95.5 | +11.9 |
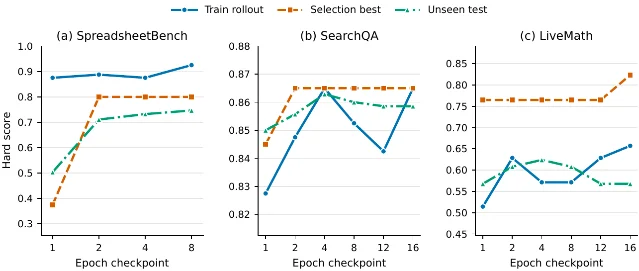
"The agent gets better the more you use it, with no weight training and zero inference-time overhead."
recall_k=20 (pulling 20 most-similar past tasks for contrastive reflection) gained +4.5 points. 6"On saturated or noisy benchmarks the effect is flat within run-to-run noise — single-seed baseline variance here is ±1–2 pts, so treat sub-~1.5 pt differences as noise."
"A growing pile of skills is not the same as skills that get better... This isn't memory. Memory recalls what happened. This changes what the agent is good at."
"DSPy is a different, complementary layer. It compiles declarative LM pipelines and optimizes program structure; SkillOpt optimizes the external skill state a frozen agent loads. You can run them together."
"SkillOpt works exceptionally well for procedural, tool-heavy tasks where success is binary or numeric. It is less effective for subjective tasks where defining a good outcome is itself the challenge."
github.com
arxiv.org
venturebeat.com
microsoft.github.io
github.com
github.com
linkedin.com
flowtivity.ai
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.
