目录按账号白名单筛掉图片模型,生图那条路不看白名单
这一窗口从北京 07:48 到 10:11。四个仓库都没有发新版:
- CLIProxyAPI 停 v8.0.42,10-24 22:21 发布1
- sub2api 停 v0.2.18,10-23 15:44 发布2
- codex-proxy 停 v2.1.20,10-23 03:56 发布3
- codex2api 停 v3.1.1,10-17 05:42 发布4
版本没动,窗口里落下的两件事都在发行版代码里原样存在,第三件是一条需求被彻底关掉。
- codex2api:给账号写过文本模型白名单的站,
/v1/models会漏掉图片模型,生图请求照过。把gpt-image-*加进白名单即可恢复自动发现。 - CLIProxyAPI:
openai-compatibility里没写thinking的模型,请求xhigh到上游会变成high。给该模型写上thinking.levels就能绕开。 - Codex 原生 history/notes:需求单 9 月就被判不做,今天那张对应的 PR 也被作者关掉,不必再排期等它。
同一本凭据,目录里没有图片模型,生图照过
报障单在 2026-10-25 08:58(北京)开出,作者 depress77,零回复、无标签5。
他用同一个 API Key、同一个 ChatGPT Plus OAuth 账号,量了三条请求。
| 请求 | 结果 |
|---|---|
GET /v1/models | 200,9 个文本模型,没有任何图片模型5 |
POST /v1/images/generations,model=gpt-image-2 | 200,返回非空 data[0].b64_json,约 28 秒5 |
POST /v1/responses + tools[{type:image_generation}] | 200,图片项 status: completed,约 23 秒5 |
三条结果放在一起就是矛盾点:能生图,却看不见能生图的模型。
前提由报障人自己写明:这个账号保存的
credentials.models 是一份 9 项的文本模型白名单,里面没有 gpt-image-2。白名单留空的站不会遇到这件事。目录侧的判断在
scopedModelRecords 里,一行看全:if !account.ModelCatalogEligible() || !item.Enabled || !account.SupportsCodexModel(item.ID) {它对目录里的每一项都问同一组问题,图片条目和文本条目一视同仁。
SupportsCodexModel 的语义决定结果:名单为空放行全部;名单非空就按大小写不敏感精确匹配,匹配不上返回 false6。gpt-image-2 因此被跳过,/v1/models 里就没有它。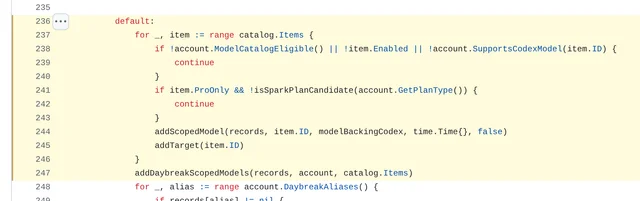
生图走的是另一套选号。
nextImageAccount 先用 imagePreferredAccountFilter 只在 Plus 及以上套餐里挑,挑不到再放开到 imageCapableAccountFilter;两个过滤器都只排除中转型账号(IsRelayStyle),整条路上没有一处查模型名单。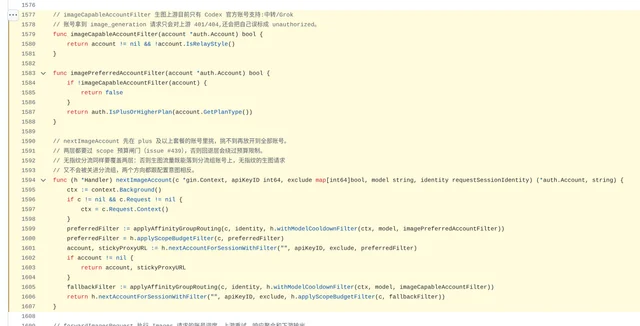
同一个函数里还有一处对照。Grok 账号那一支专门用
grokMediaModelsForAccount 把媒体模型补进目录,注释写明「与媒体端点的调度准入同源」10。Codex 这一支没有这一步,于是目录与调度各说各话。影响面收窄到一种配置:账号模型白名单非空,且里面没有图片 ID。
现在能做的三步:
- 要恢复自动发现,把
gpt-image-2以及要用的-2k、-4k变体加进该账号的模型白名单。代价是这些 ID 也会出现在对话模型目录里,客户端会看到它们。 - 不想改名单,就在客户端里手填型号。dsh-image-gen 这类插件的手填入口能绕过发现这一步。
- 先自查有没有踩到:
credentials.models为空数组的账号流程正常,不需要动。
状态:v3.1.1 标签与 main 是同一条判断(标签里在 238 行,main 里也在 238 行);仓库当前 0 个开放 PR,还没有人提修复。
没写 thinking 的兼容模型,xhigh 到上游变成 high
请求带
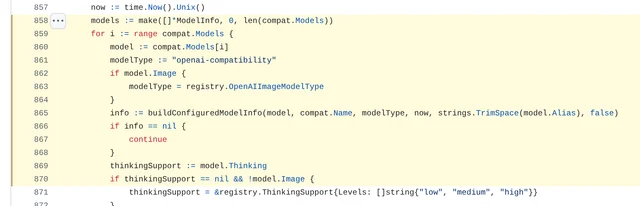
reasoning_effort 为 xhigh 时,mapConfiguredHighIntent 会在这份表里找替代:候选顺序是 xhigh、max、high,第一个出现在档位表里的胜出,于是落到 high。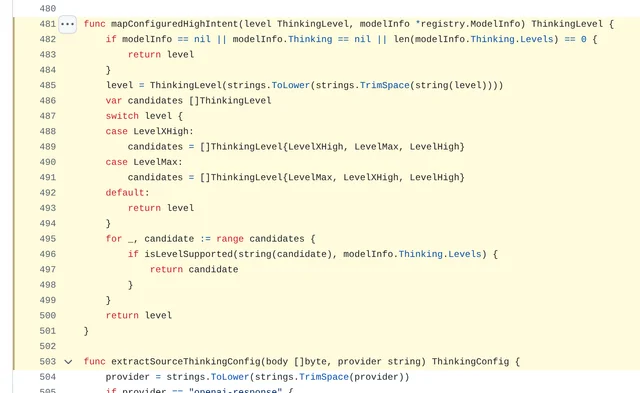
协议相同时也照样改写。
shouldMapConfiguredHighIntent 在协议相同时改成比对模型类型是否同族,而 OpenAI 家族名单只认 openai、openai-response、codex 三个值16;兼容模型自报的类型是 openai-compatibility,落在名单外,所以照样进改写。这一行为在配置样例里是写明了的:省略
thinking 就按三档走,「超过三档的(例如 max、xhigh)会被钳到 high」,上游支持的话请显式声明 levels17。PR #5511 想改的就是这一点:给造出来的档位表加一个
ThinkingSupport.LevelsAssumed 标记,遇到这个标记就跳过改写与档位校验,把请求的档位原样发上去,让上游自己决定收不收。这张 PR 在今早 08:38(北京)强制推送了四笔提交,四笔的提交者时间都是 2026-10-25T00:38:12Z;改动 9 个文件、+211/−12,仍是 open、mergeable clean、未合并18。
发行版与 dev 都还没有这处改动:v8.0.42 与 dev 两版整包都搜不到
LevelsAssumed,dev 的 apply.go 里 mapConfiguredHighIntent 仍在原处被调用19。现在能做的:给那个模型显式写
thinking.levels,并把 xhigh 写进去。写进去之后,候选里的第一项就被支持,改写不再发生。影响面只在
openai-compatibility 段里自己列出来的模型。内置 provider 的档位来自模型登记表,不走这条伪造。原生 history/notes:需求单 9 月就判了不做
2026-09-05 有人开单请求转发 Codex 的
alpha/history/v2/* 与 alpha/notes/v2/*,理由是 Codex 的实验性上下文管理会单独发这两类请求。他用 v7.2.142 与 Codex CLI 0.153.4 测了四条路径,全部 40420。这个需求在 2026-09-07 22:22(北京)被关成 not planned21。
承接实现的 PR #5600 早在 2026-09-07 19:38(北京)就开出来了,改 4 个文件、+551/−1;今天 10:05:53 作者留言「Closing this — #5547 was closed as not planned for native history/notes backend endpoints」,三秒后在 10:05:56 关闭,未合并22。
所以这两类端点可以从排期里划掉。原单也写明,普通对话与压缩不受影响。
上游与额度:这一窗口没有新事件
- OpenAI 状态页 All Systems Operational,组件无降级24
- Anthropic 状态页同样全绿25
- Google Cloud 事故表 8 条,最新一条的修改时间仍是 2026-10-22T16:19:08Z(北京 10-23 00:19),窗口内没有更新26
- codex-reset:今日 UTC 未重置,最近一次已验证的全局重置是 10-23 01:10(北京),累计 57 次、10 个未用,节奏约每两天一次27
三件事里两件今天能自己改完,第三件不必再等。
References
- 1CLIProxyAPI releases
github.com
- 2sub2api releases
github.com
- 3codex-proxy releases
github.com
- 4codex2api releases
github.com
- 5codex2api issue 826
github.com
- 6codex2api v3.1.1 的 auth/store.go
github.com
- 7
- 8
- 9codex2api v3.1.1 的 proxy/handler.go
github.com
- 10
- 11
- 12
- 13
- 14
- 15CLIProxyAPI PR 5511
github.com
- 16
- 17
- 18CLIProxyAPI PR 5511 的提交记录
api.github.com
- 19
- 20CLIProxyAPI issue 5547
github.com
- 21CLIProxyAPI issue 5547 的关闭记录
api.github.com
- 22CLIProxyAPI PR 5600
github.com
- 23
- 24OpenAI status summary
status.openai.com
- 25Anthropic status summary
status.anthropic.com
- 26Google Cloud incidents
status.cloud.google.com
- 27Codex Reset Tracker
codex-reset.com
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.