AssemblyAI Voice Agent API: One unified pipeline for real-time voice applications
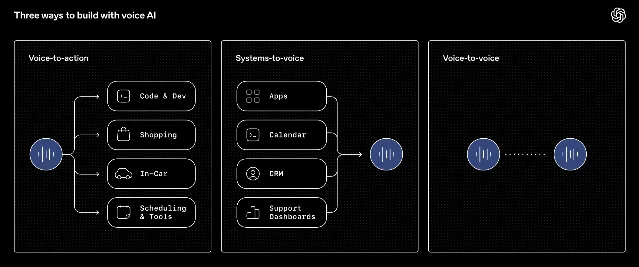
AssemblyAI's new Voice Agent API collapses the STT + LLM + TTS pipeline into a single managed endpoint, with sub-300ms round-trip latency in production benchmarks.

The STT→LLM→TTS pipeline is structurally lossy — it transcribes tone, hesitation, and interruption intent into silence. This brief explains what native audio reasoning replaces it with, compares GPT-Realtime-2 and Gemini 3.1 Flash Live on benchmarks that predict real PM failure modes, and closes with three concrete decisions every voice-AI product team needs to make before launch.

| Benchmark | GPT-Realtime-2 | Gemini 3.1 Flash Live | What it measures |
|---|---|---|---|
| Big Bench Audio | 96.6% | 95.9% (high-thinking) | General audio language understanding |
| Conversational Dynamics | 96.1% (#1) | Not disclosed | Interruption handling, turn-taking |
| ComplexFuncBench Audio | Not disclosed | 90.8% (vs. 71.5% prior gen) | Multi-step tool calls in a voice context |
| Pricing | $32/$64 per 1M audio in/out tokens | $0.50/$3.00 per 1M text/audio in tokens (Live API) | — |
xhigh, you get deeper reasoning and higher latency. At minimal, you get 1.12s first audio with shallower processing. The right default is low for conversational flows and medium for tool-heavy transactions — high and xhigh are for edge cases where deliberation speed is less critical than accuracy.8low as your default and tune up only for transactions, and test in adversarial audio conditions before launchretellai.com
handyai.substack.com
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.
AssemblyAI's new Voice Agent API collapses the STT + LLM + TTS pipeline into a single managed endpoint, with sub-300ms round-trip latency in production benchmarks.