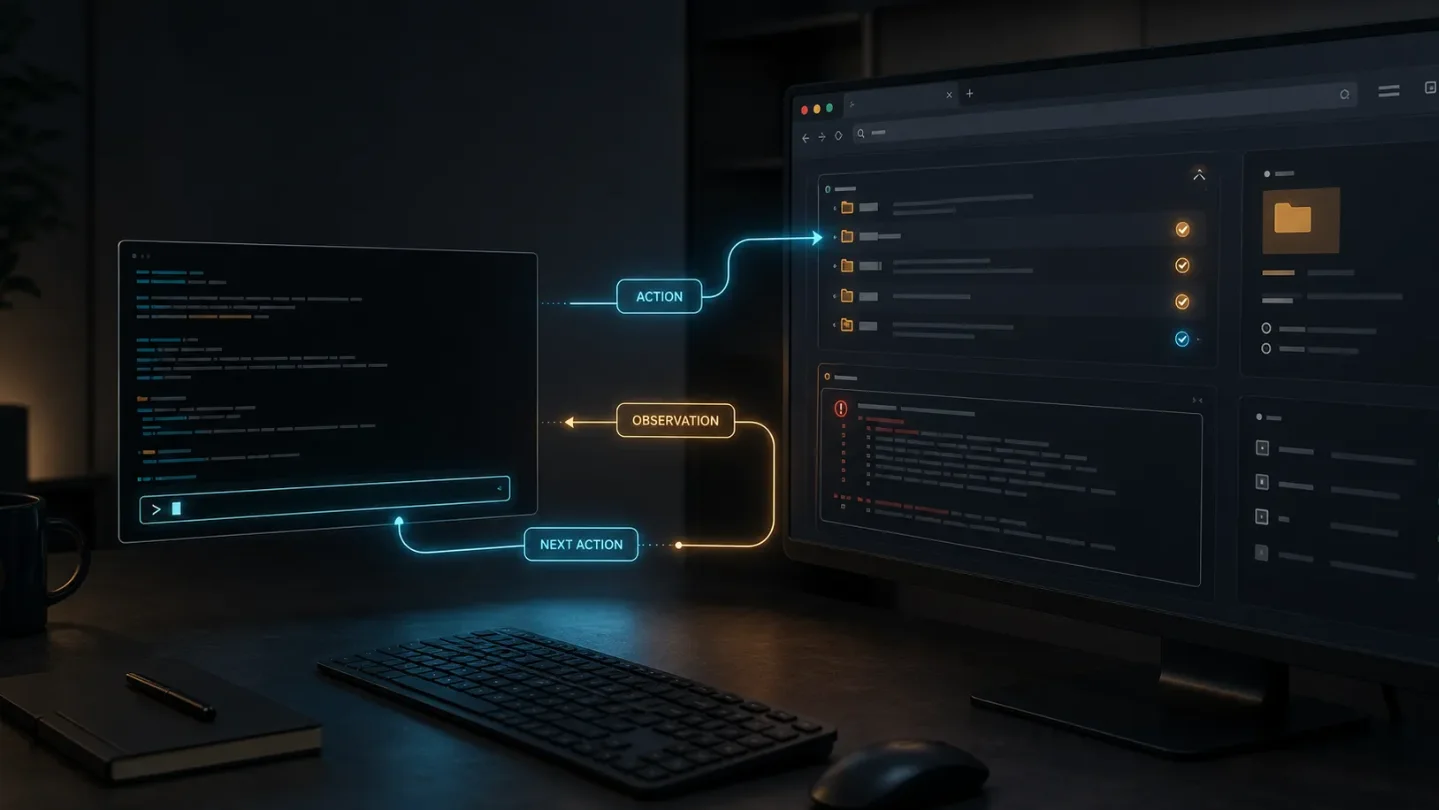
Environment feedback becomes a training signal for AI agents
ECHO and EnvRL show how adding environment-response prediction to agentic reinforcement learning can improve selected long-horizon benchmarks, giving PMs a concrete way to test whether their agents learn tool dynamics rather than memorize outcomes.

A failed tool call is usually treated as a bad outcome. New agent-training work treats it as something else too: evidence about how the environment behaves. That changes what a product team should save from an agent run. The command matters, but so does the shell response, error, file diff, or API state that came back.
Two recent preprints, ECHO and EnvRL, add environment-response prediction to reinforcement learning. Their results are still benchmark results, not production proof, but they point to a practical shift: long-horizon agents may improve faster when they learn the dynamics of their tools instead of learning only from a final success or failure.
What changed
In a normal language-model agent, the model emits an action, such as a shell command or a product-search request. The environment executes it and returns an observation. That observation might be standard output, an error, a changed file, a retrieved page, or a new state in an application.
Outcome-based reinforcement learning often uses the final reward to update the action policy while giving little direct training signal to the intermediate observations. ECHO, short for Environment Cross-entropy Hybrid Objective, adds a second target: after taking an action, the model also learns to predict the environment tokens that follow. It keeps the policy-gradient loss on action tokens, reuses the forward pass used by GRPO, and does not require extra rollouts. 1
The idea is easiest to see in a terminal agent. A command that fails with a missing dependency still tells the model something about the machine. A command that changes a file tells it something about the repository. Those observations are not rewards by themselves, but they describe the transition caused by the action. Learning that transition can make later actions less wasteful.
ECHO reports a 2.70% to 5.17% pass@1 increase for Qwen3-8B on TerminalBench-2.0, and a 5.17% to 10.79% increase for Qwen3-14B, compared with GRPO. The same abstract reports lower environment-token cross-entropy on held-out rollouts and says the method matched expert-SFT-then-GRPO performance on held-out terminal tasks from a base Qwen3-8B model without expert demonstrations. These are reported results from one paper and one benchmark family, so they support a training hypothesis rather than a general reliability claim. 1
EnvRL makes the same move broader. It jointly trains an agent on the main RL objective plus state prediction and inverse dynamics, which asks the model to connect an environment state and an action with the resulting transition. With GRPO and Qwen-2.5-1.5B-Instruct, the paper reports ALFWorld success rising from 72.8% to 77.4% and WebShop success rising from 56.8% to 67.0%. The paper gives those benchmark results in its abstract, but not the full experimental detail or uncertainty estimates there. 2
The shared mechanism is more useful than either name. The model learns two related jobs at training time: choose actions that produce reward, and predict what the environment will say or do next. At inference time, the agent still runs its normal action and tool loop. Cameron Wolfe's July 20 synthesis describes this as using observation tokens as dense supervision while keeping RL focused on action tokens. 3
For background, the Hugging Face "RL for Agents" workshop published on April 22 and had 193,284 views when checked. It covers the surrounding engineering problems, including environments, rollouts, tool use, reward design, and multi-step evaluation. It is useful context, but it predates this specific wave of environment-modeling results. 4
Loading content card…
Why PMs should care
The product implication is not "add a world model" to every agent. It is that task success and environment understanding are different measurements.
An agent can complete a task by memorizing a narrow tool response, retrying until a lucky path works, or relying on a large number of demonstrations. A model that predicts environment transitions should be better positioned to recover when the tool returns an unfamiliar error or when the state changes between steps. But the same training signal can encourage memorization. Wolfe notes that retrieval-heavy environments and repetitive observations are especially prone to overfitting, and that low-information failures should be filtered rather than treated as equally useful supervision. 3
That creates four PM questions:
- Can the team replay a clean action-observation trajectory, including the state before and after the action?
- Is the observation stable enough to learn from, or does it contain mostly random, sensitive, or time-dependent data?
- Can the team hold out tools, environments, or task variants so it can detect memorization?
- Is there a mechanical acceptance test beyond the final language-model answer?
The X discussion around Wolfe's write-up makes the tradeoff concrete. He describes RL as teaching which actions earn reward and world modeling as teaching how the environment responds. He also calls out the need to balance the auxiliary objective, filter noisy observations, and watch held-out performance for overfitting. That is a useful practitioner interpretation, not independent validation of the preprints. 5
Loading content card…
The cost case is also more specific than "better reasoning." ECHO reuses the GRPO forward pass and adds no extra rollout or inference step, but the training job still needs more loss computation and careful data handling. A PM should compare cost per accepted task, recovery after tool errors, timeout rate, and held-out success, rather than infer savings from a benchmark percentage alone.
How to implement now
1. Instrument transitions before changing training
Add a trace record for every tool step in one pilot workflow. At minimum, retain the task ID, state summary before the action, action and tool name, normalized observation, state summary after the action, terminal status, reward or acceptance result, retry count, and sensitivity label.
Keep raw credentials, personal data, and volatile external content out of the training set. Store a replayable normalized observation when possible, such as an error class, changed-file summary, structured API result, or application state transition. If the team cannot reconstruct what changed after a tool call, it cannot tell whether environment modeling helped.
2. Choose a domain with inspectable transitions
Start with a sandboxed workflow where the environment has a stable contract and the outcome can be verified. A repository task with tests, a structured document workflow with field-level checks, or a simulated commerce task is a better first setting than an open-ended assistant with noisy web retrieval.
The first baseline should be the current policy trained or tuned with the existing outcome signal. Keep the action space, tool schemas, permissions, and stopping rules fixed. Otherwise, a new tool interface can masquerade as a training improvement.
3. Add the auxiliary objective in a reversible experiment
For an agentic RL setup, preserve the normal policy loss and add a bounded observation or state-prediction loss. ECHO is the simplest reference: predict selected environment-response tokens while optimizing the action policy. EnvRL is the broader reference: add state prediction and inverse dynamics to the RL objective. 12
Do this in a sandbox with a small model and a fixed training budget. Log the relative weight of the auxiliary loss, the distribution of observations used, and the point at which validation performance changes. Do not treat the absence of an extra inference step as proof that the experiment is free: training compute, trace storage, filtering, and evaluation still count.
4. Evaluate the environment model separately
Use three test groups:
| Test group | What it tells you | Metrics |
|---|---|---|
| Familiar tasks and tools | Whether the hybrid objective improves the target workflow | Accepted-task rate, action errors, retries, cost per accepted task |
| Held-out task variants or tools | Whether the agent learned transitions rather than memorized responses | Success, recovery after unseen errors, environment-prediction loss |
| Noisy or adversarial observations | Whether the training signal makes the policy brittle | Over-action rate, unsafe actions, timeout rate, human intervention |
A benchmark gain is useful only if it survives the second and third groups. For a customer-facing agent, also measure escalation quality and the cost of a wrong action. For a coding agent, measure test-passing changes and rollback rate, not just command completion.
5. Set the go/no-go rule before training
Continue only if the hybrid run improves accepted-task rate or recovery on held-out environments without a material increase in unsafe actions, intervention, or total cost per accepted result. Stop if training loss falls while held-out success drops, if the model memorizes volatile retrieval content, or if the trace schema cannot identify which observation caused the change.
The near-term PM opportunity is therefore modest and concrete. Preserve action-observation transitions, test whether they contain learnable environment structure, and add that signal only where a held-out acceptance test can expose overfitting. The research is promising because it uses information agents already generate. It is useful for a product only when the team can show what was learned and where it still fails.
References
- 1
- 2
- 3Agentic World Models
cameronrwolfe.substack.com
- 4
- 5
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.