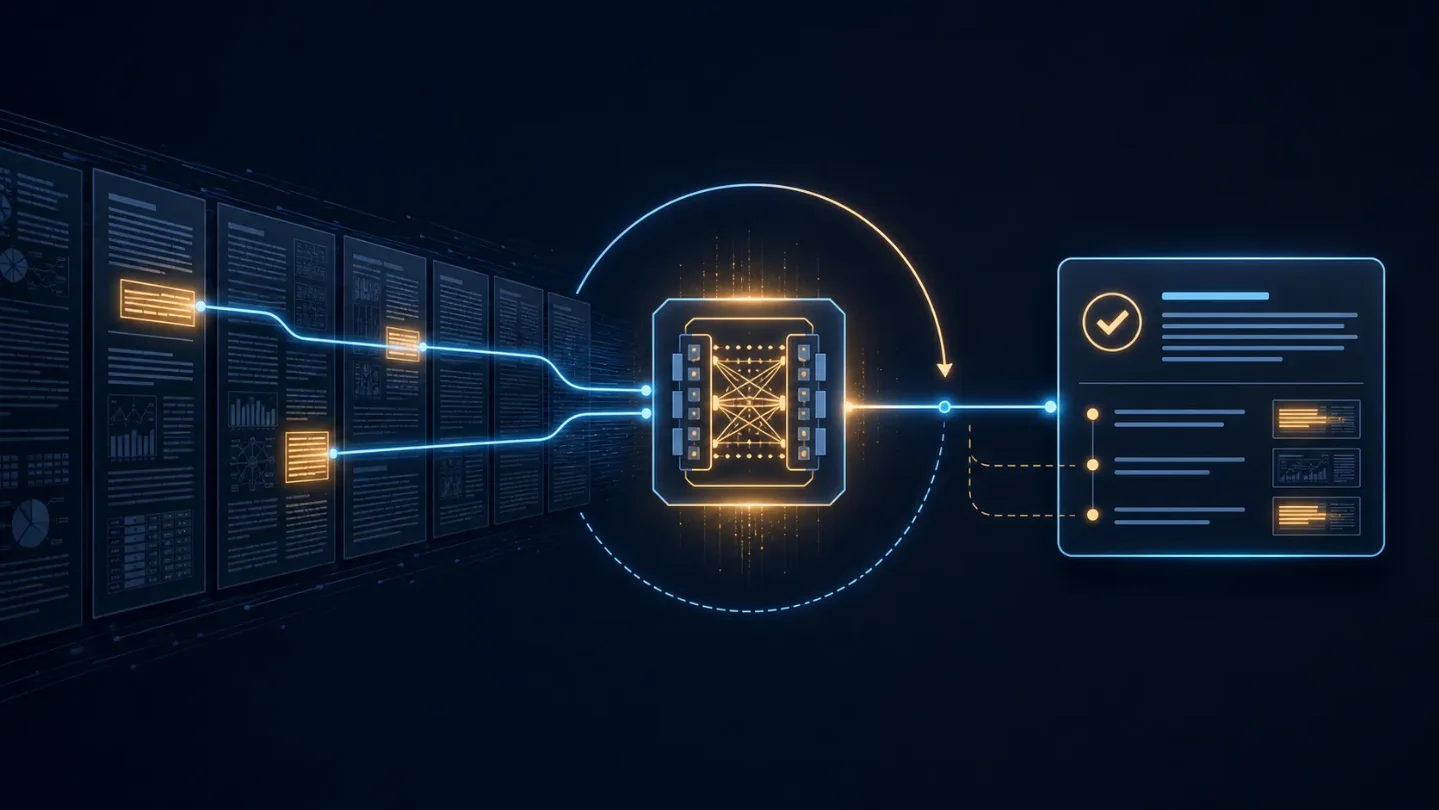
Long-context models may need a temporary study session
Self-Guided Test-Time Training shows a bounded way to adapt a temporary model copy on selected evidence spans, giving PMs a pilot path for long-document reasoning when accuracy gains justify latency and GPU cost.

Long context is not the same thing as useful reading. A model can accept 128,000 tokens and still fail to find, connect, or learn from the evidence that answers the question.
A new paper proposes a more literal fix: let the model select the evidence it needs, briefly train a temporary copy of itself on those spans, then answer from the full context. For a PM, the important idea is not「make every model keep learning」. It is「add a bounded, per-request adaptation step when the value of better evidence use justifies the latency and GPU cost」.
The short version
| Question | PM answer |
|---|---|
| What changed? | Self-Guided Test-Time Training (S-TTT) uses the model to select question-relevant text, then applies a short next-token-prediction update to a fresh model copy before generation. |
| What problem does it target? | Long-context models often have the information but fail to use it reliably; training on the whole context can also absorb distractors. |
| What did the paper show? | On the authors' LongBench-v2 and LongBench-Pro evaluations, S-TTT improved several 64k–128k settings, including Qwen LongBench-v2 from 30.7% to 35.3%. 1 |
| What should a product team do? | Treat it as a gated experiment for document-heavy, read-only workflows—not as a drop-in replacement for retrieval, context compression, or ordinary inference. |
What changed: the context window becomes a training set
The paper, from researchers at Meta AI and the University of Virginia and submitted to arXiv on July 10, 2026, starts from a practical distinction: a long prompt can contain the answer without causing the model to form a useful working representation of it. Full-context test-time training is expensive, while randomly chosen training spans can teach the temporary model the wrong thing. 1
S-TTT splits the request into two passes:
- Select evidence. The base model identifies verbatim spans that matter to the question.
- Adapt briefly. A fresh copy of the model runs the standard next-token-prediction objective on those spans.
- Answer normally. The adapted copy generates against the original full context.
- Discard the update. The temporary parameters are not carried into the next request.
That last step changes the product shape. This is not a continuously self-training assistant with an ever-changing personality. It is closer to a study session that exists for one question, one document set, or one session. In the reported setup, the authors use LoRA updates on query projections, with rank 16 and 16 gradient steps—an implementation choice that keeps the adaptation narrower than updating the full model, not a universal production recipe. 1
The intuition is visible in the paper's diagnostic. With Qwen3-4B-Thinking-2507 on LongBench-v2, the base model scored 40.4%; training on random spans fell to 38.9%; training on oracle-selected spans reached 45.9%. The gap says the bottleneck is not merely「more test-time training」. It is selecting training material that teaches the model how to use the evidence relevant to this particular question. 1
Why PMs should care
1. A larger context window may be the wrong unit of progress
Teams often frame long-context work as a retrieval decision: fit more, retrieve less. S-TTT points to a different failure mode. Even when retrieval returns the right material, the model may not use it well. The product surface is therefore not just context capacity; it is evidence selection plus evidence use.
That distinction affects roadmap choices. If failures come from missing evidence, improve retrieval or query decomposition. If the evidence is present but answers are poorly grounded, a temporary adaptation step becomes a candidate. If the answer is already reliable, S-TTT is probably an expensive way to buy a marginal gain.
2. The reported gains are meaningful but uneven
The paper reports these scores for 64k–128k contexts:
| Evaluation | Base | S-TTT | Absolute change |
|---|---|---|---|
| Qwen, LongBench-v2 | 30.7% | 35.3% | +4.6 pp |
| Llama, LongBench-v2 | 26.3% | 28.2% | +1.9 pp |
| Qwen, LongBench-Pro | 41.6% | 42.0% | +0.4 pp |
| Llama, LongBench-Pro | 19.4% | 21.7% | +2.3 pp |
The abstract describes the best result as up to a 15% relative improvement; that is not the same as a 15-point accuracy increase. The LongBench-Pro gains are also not uniformly large. A PM should ask which task family benefits, not whether「S-TTT works」in the abstract. 1
3. Latency is part of the feature, not an implementation footnote
The authors measure overhead on one NVIDIA H200 using PyTorch FSDP and vLLM. S-TTT costs more at shorter context lengths; at 64k and above, the selective update becomes cheaper than full-context TTT, and at 128k it is the lowest-latency non-frozen-KV method in their comparison. That is evidence about the paper's setup, not a p95 promise for your serving stack. 1
There is also a useful warning signal: the reported fallback rates range from 6.9% to 39.9% across the model and benchmark combinations. A real product needs to know when selection or adaptation is untrustworthy and route back to the baseline. 1
How to implement now
Do not begin by adding S-TTT to every long-context request. Start with a workflow where the tradeoff is measurable and reversible:
- Choose a read-only corpus. Good candidates are policy, contract, research, or incident documents where the system must answer questions and cite evidence, but does not take irreversible actions.
- Build a held-out question set. Include questions whose answers are present in the corpus, plus adversarial distractors and questions requiring evidence from multiple sections.
- Establish three baselines. Compare ordinary long-context inference, your current RAG or context-compression path, and a selective-adaptation variant. Keep the model and serving budget as comparable as possible.
- Make the update disposable. Isolate temporary weights per request or session; do not persist them by default. Cap context length, adaptation steps, GPU memory, and wall-clock time. Keep a no-adaptation fallback.
- Measure cost per correct answer. Track answer accuracy and citation grounding alongside p50/p95 latency, adaptation overhead, GPU memory, cost, fallback rate, and evidence-span validity. Also test whether one question's update harms another question in the same session.
- Promote only on held-out documents. A win on the documents used to tune the selector is not enough. Require improvement on unseen document sets with no unacceptable data isolation, privacy, or rollback failures.
There is an engineering precedent for the basic adaptation pattern, but it is not a reproduction of S-TTT. The open-source End-to-End Test-Time Training project trains while reading with sliding-window attention and a next-token objective, and publishes checkpoints up to 3B parameters, including a 128K checkpoint. Its setup involves GPU training dependencies, experiment tracking, and optionally multi-node orchestration—useful evidence that test-time training is an engineering subsystem, not a prompt tweak. 2
For a fast conceptual introduction, the accessible video Test-Time Training Explained: LLMs That Learn on the Fly from Tales Of Tensors (June 21, 2026; 340 views when collected) explains frozen weights, temporary updates, and the long-context latency tradeoff. It is an explainer, not independent validation of the S-TTT paper's numbers. 3
What the signal does—and does not—say
The paper's author Yu Meng described S-TTT on X as a response to TTT's sensitivity to training-span quality: the model identifies its own data on the fly. The post is a useful explanation of the researcher's intent, but it is not an independent replication; it had 6,259 views, 43 likes, and 10 reposts when collected. 4
The defensible takeaway is narrower than「long context is solved」: when a model already has a large evidence set but struggles to use it, selective, temporary adaptation may buy accuracy—at the cost of extra inference complexity and latency. The paper is benchmark evidence, not a production SLA. It leaves open how well the method transfers to retrieval pipelines, memory systems, changing corpora, multimodal inputs, and real multi-tenant serving.
The PM decision is therefore straightforward to stage: find a workflow where a few extra seconds or GPU dollars could prevent an expensive wrong answer, then test whether model-selected evidence spans make that trade worthwhile. If they do not, the experiment still gives you a useful diagnosis: the long-context problem may be retrieval, task decomposition, or evaluation—not a missing training step.
References
- 1
- 2
- 3
- 4
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.