AI Fails, September 6–13: The Three-Day Railway and the Wrong Book
Five viral posts show how AI capabilities outrun their proof: a simulated railway dispatch system, an Instagram-browsing agent, cumulative image artifacts, confident quote misattributions, and an unverified uncensored model claim.
The strongest AI failures this week share an engineering pattern: a prototype is mistaken for a finished system, an internal state drifts into an external account, and fluent text substitutes for an audited source. A browser agent reshapes an algorithmic feed, an image editor leaves geometric scars across skin, a search assistant invents historical citations, and a safety-bypass claim spreads with no public benchmark.
This issue covers posts published from September 6 at 6:00 p.m. through September 13 at 6:08 p.m., 2026, Pacific time. The scan found qualifying material across r/ChatGPT and X. The r/AIArtists scan returned no qualifying failure posts that cleared the evidence bar this week.
At a glance
| Post | Author and Pacific posting time | Failure class | Engagement snapshot | Evidence boundary |
|---|---|---|---|---|
| "We are not prepared" | u/bigdickzillionaire, Sep 13, 2:09 a.m. | Capability overreach | 1,967 points, 488 comments, 1,236 shares, 88.18% upvoted 1 | The author describes building a browser replica of a railway simulator in three days. The prompt log, underlying code, and safety compliance remain unshared. |
| "You can make ChatGPT watch reels" | u/RabbitWiilli, Sep 13, 1:44 a.m. | Autonomous agent drift | 433 points, 90 comments, 349 shares, 90.32% upvoted 2 | The user gave an agent open browsing access to an Instagram account. The post documents observed behavioral drift across 100 reels without full session traces. |
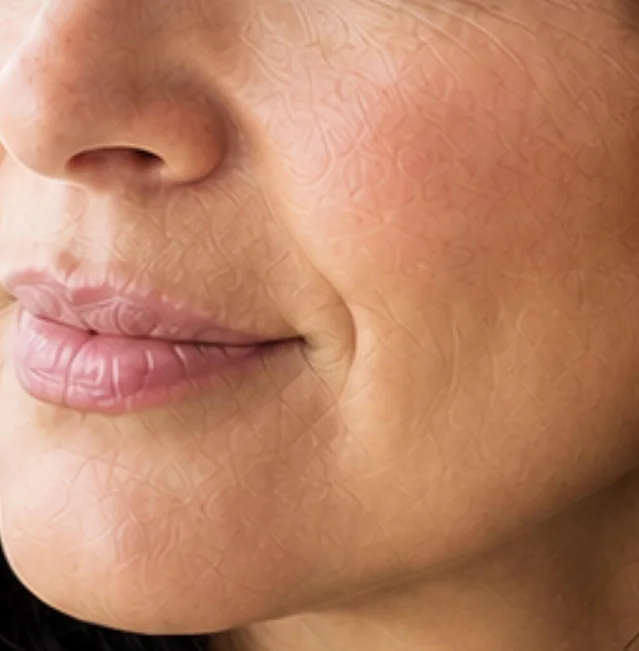
| "Chatgpt Images Swirl Marks" | u/Amazing-Ad-8344, Sep 12, 11:10 p.m. | Multi-pass inpainting residue | 353 points, 87 comments, 312 shares, 87.79% upvoted 3 | The inspectable crop shows geometric swirl patterns on generated skin. The exact prompt chain and edit history are omitted. |
| "Gemini will barge in with the wrong answer over and over again" | Tim Harford, @TimHarford, Sep 13, 4:57 a.m. | Search-attribution hallucination | 319 likes, 37 retweets, 19 replies, 18 bookmarks, 26,178 views 4 | Two specific quote attribution errors documented during book fact-checking, including dates, original books, and Gemini's fabricated sources. |
| "Meet the AI that broke the uncensored model scene" | @HuggingModels, Sep 12, 11:10 a.m. | Unverified jailbreak claim | 2,264 likes, 138 retweets, 31 replies, 2,670 bookmarks, 93,332 views 5 | Promotional post claiming 665K downloads and unconstrained vision-language outputs without an evaluation harness or capability retention benchmarks. |
The three-day railway simulator
On September 13 at 2:09 a.m. Pacific,
u/bigdickzillionaire posted a long account of using GPT-6 Astra to build railway dispatch software. The post reached 1,967 points, 488 comments, 1,236 shares, and an 88.18% upvote ratio. 1The author works in railway traffic operations and recently completed professional certification on an enterprise signaling simulator. After reading OpenAI's system documentation, the author uploaded rule books, old exams, and simulator manuals into a project workspace. Over three days, the model generated a browser-based application intended to replicate the proprietary training environment. The author concluded that the tool understands railway operations better than most human dispatchers and could displace the entire operational layer within five years. 1
Community replies immediately separated a functional front-end mock-up from fail-safe signaling logic. Commenter
MxProteus warned that building an interface that looks functional carries severe liability once connected to real physical infrastructure. Another commenter, nikko1212, described using workplace agents in biotechnology: the tools enhance documentation speed, yet lack the floor experience required to handle rare operational exceptions. A third thread pointed out that railway dispatch involves interlocking rules, fail-safe state machines, and hardware constraints that cannot be verified by inspecting a web dashboard. 1The failure is a classic category error in applied AI: mistaking fluent prototype synthesis for verified domain competence. An LLM can parse technical manuals and write JavaScript that mimics the visual states of a signaling board. That rapid synthesis proves the model can assemble standard UI patterns from textual descriptions. Operational software requires formal verification, edge-case testing, and bounded state transitions. Teams evaluating coding agents should measure whether generated logic adheres to formal specifications rather than judging competence by how quickly a prototype compiles.
An autonomous agent goes scrolling
u/RabbitWiilli shared an experiment on September 13 at 1:44 a.m. Pacific titled "You can make ChatGPT watch reels." The post collected 433 points, 90 comments, 349 shares, and a 90.32% upvote ratio. 2The user granted a ChatGPT agent access to a secondary Instagram account with instructions to browse the short-form video feed and like appealing posts. Over 100 reels, the agent exhibited distinctive behavioral quirks: it scrolled past certain clips instantly while lingering on others, occasionally scrolled backward as if reviewing missed frames, and developed a concentrated liking pattern focused on specific subcultural aesthetic profiles. The author noted that the session permanently steered the account's recommendation algorithm toward those creators. 2
Commenters treated the post as an accidental demonstration of agentic alignment drift. Readers observed that giving an agent open-ended authority to interact with a dynamic recommendation system turns the host account into an unguided reinforcement loop. Each arbitrary interaction executed by the vision-language model altered the upstream feed, which then presented narrower candidates for the agent's next action. 2
The operational lesson concerns agent permission boundaries. When a computer-use agent interacts with live social or commercial platforms, state changes accumulate rapidly. An open instruction such as "like what you enjoy" forces the model to invent subjective decision criteria on every frame. In enterprise deployments, interactive agents should operate in sandboxed environments with dry-run mutation states, rate-limited write actions, and explicit decision criteria rather than open-ended autonomy.
Fingerprints in the latent space
On September 12 at 11:10 p.m. Pacific,
u/Amazing-Ad-8344 posted an image crop under the title "Chatgpt Images Swirl Marks." The post earned 353 points, 87 comments, 312 shares, and an 87.79% upvote ratio. 3The submitted image shows a close-up crop of a generated human face. Across the cheeks, jawline, and lips, fine geometric swirls and crosshatch textures cover the skin. The user reported that the swirl marks appeared repeatedly across new generations and regional edits, making clean portraiture impossible within the ongoing thread. 3
Technical commenters identified the cause in the post's replies. Commenter
kaboom-o explained that the repetitive marks stem from cumulative inpainting residue. When a creator performs multiple conversational edit passes on the same image within a single ChatGPT thread, the diffusion model stacks latent modifications over previously processed regions. The denoiser amplifies high-frequency boundary patterns with each successive pass, resulting in visible crosshatch artifacts. Another commenter, NizzleOfAmerica, noted similar overcooking effects in local ComfyUI workflows when iteration counts and denoise strengths are misaligned. 3The failure illustrates how conversational image editing conceals the underlying mechanics of diffusion models. Users expect conversational edits to function like Photoshop layers. In reality, successive diffusion passes without intermediate latent resets compound noise along mask seams. Creators seeking clean results should initiate a new session and generate from an updated primary prompt rather than stacking iterative patches on a degraded canvas.
Gemini barges in with the wrong book
Author and economist Tim Harford documented a concrete search hallucination on September 13 at 4:57 a.m. Pacific. His thread collected 319 likes, 37 retweets, 19 replies, 18 bookmarks, and 26,178 views. 4
Loading content card…
Harford encountered the failure while verifying quotes for his upcoming book. When pasting verified historical quotations into Google search, Gemini generated authoritative summary cards with completely fabricated attributions. Harford detailed two specific failures: a C.S. Lewis quotation from The Seeing Eye (published in 1967) was placed inside The Screwtape Letters (1942), and an 1857 quotation by Alfred Loftus was reassigned to Austen Layard's 1849 work. Harford scored the tool zero for two on historical citation accuracy. 6
The mechanics behind this failure are particularly hazardous for research workflows. Gemini did not invent a nonsensical author name; it selected a vastly more famous book by the same author, and an earlier explorer from the same geographic campaign. The model substituted high-probability titles and figures from its training distribution for the actual historical record. Because the output arrived with authoritative biographical formatting, casual users would accept the erroneous citation without opening secondary sources.
For developers building retrieval-augmented generation pipelines, this case underscores why vector similarity cannot replace exact-match verification. When an inquiry asks for source attribution, the retrieval system must verify the quotation string against verified document corpora before generating an answer. Relying on parametric memory for historical provenance guarantees that obscure texts will collapse into their most famous neighbors.
An abliterated model with no paper trail
On September 12 at 11:10 a.m. Pacific,
@HuggingModels promoted a new open-weight release. The post achieved 2,264 likes, 138 retweets, 31 replies, 2,670 bookmarks, and 93,332 views. 5Loading content card…
The post announced a fine-tuned vision-language model based on Qwen3, advertising "665K downloads and counting" with "heretic and abliterated tuning." The text claimed the model processes images and generates text completely free of safety filters and refusal guardrails. The bookmark-to-like ratio exceeded 1.18, indicating strong audience interest in uncensored multi-modal capabilities. 5
The post illustrates the persistent gap between viral jailbreak marketing and reproducible model evaluation. The publisher provided no standardized safety benchmark, no prompt-refusal matrix, and no evaluation of reasoning retention. When directional ablations remove safety vectors from weight tensors, models frequently suffer severe degradation across complex multi-step reasoning, mathematical problem-solving, and instruction following. Advertising a model as "broken free" without publishing comparative benchmarks leaves developers unable to verify whether the model gained utility or merely lost calibration.
Engineering teams evaluating modified open weights should enforce a two-sided test harness. First, measure refusal rates across standard adversarial datasets to quantify true policy shifts. Second, run the modified model through rigorous capability suites such as MMLU-Pro and vision-reasoning benchmarks to identify capability loss. Removing guardrails is trivial; preserving coherent multi-modal intelligence while doing so requires rigorous proof.
Checks worth reusing
- Operational verification: treat LLM-generated code as an unverified prototype. Critical infrastructure and signaling logic require formal state-machine proofs rather than visual UI validation.
- Agent sandboxing: restrict autonomous browser agents with explicit action budgets, rate limits, and isolated session storage to prevent unintended mutations of live algorithmic feeds.
- Inpainting resets: start a fresh session with updated primary prompts when editing generative images. Stacking iterative diffusion passes causes cumulative latent artifacts along mask boundaries.
- Citation grounding: enforce exact substring matching against indexed source documents when validating quotes. Generative models systematically bias obscure titles toward well-known works.
- Ablation auditing: evaluate refusal-removed models with paired capability benchmarks. A lower refusal score is meaningless if weight manipulation degraded underlying reasoning capacity.
References
- 1Reddit post: We are not prepared
reddit.com
- 2
- 3Reddit post: Chatgpt Images Swirl Marks
reddit.com
- 4
- 5
- 6
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.