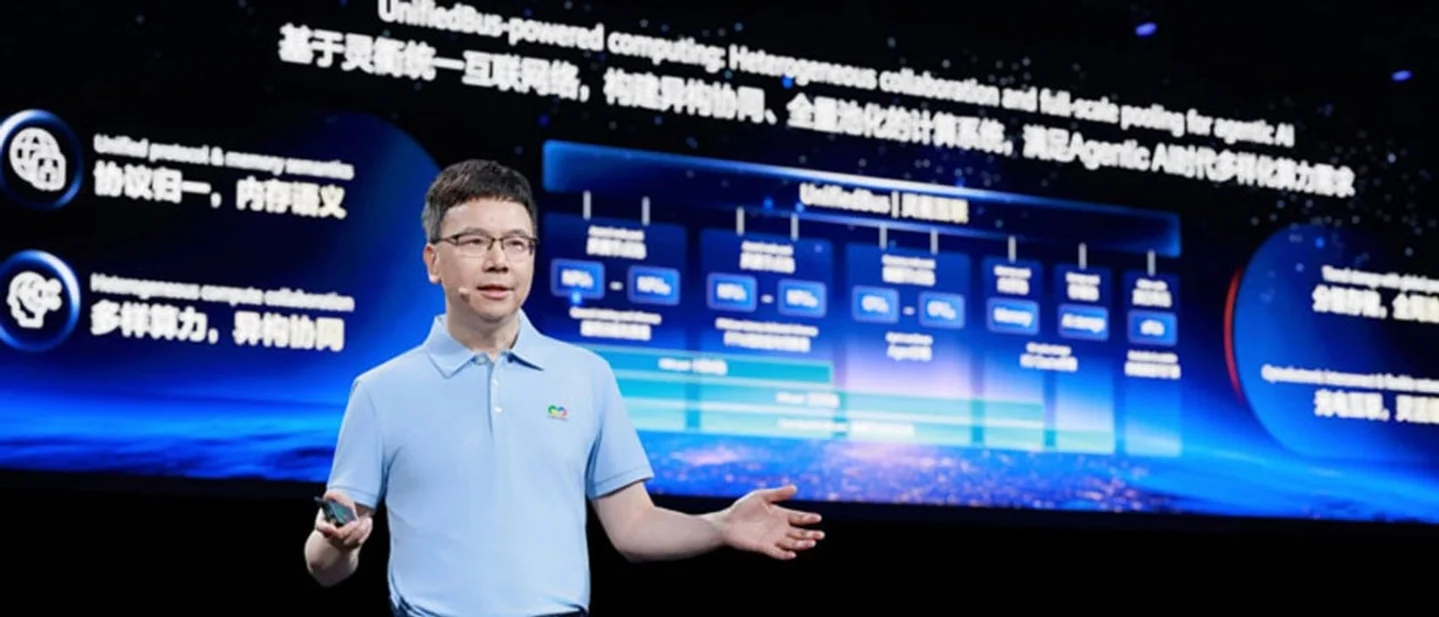
「CUDA 已不如两年前重要」:华为称与英伟达的软件差距在缩小,徐直军要中国 AI 加速
华为在 9 月 17 日的记者会上说 CUDA 已不如两年前重要,同时要求中国 AI 加速;这篇把两家各自公开的口径并排,看「软件差距已经大幅缩小」这句话能核到什么。

FT 记者 Eleanor Olcott 从上海发出的这篇稿子,写的是华为轮值董事长徐直军 9 月 17 日在上海全联接大会记者会上的一段答问。他说,中国的研究者要「加快开发速度,这样才能同样看到 AI 开发带来的危险」;等到危险真的出现,行业再来「在推动发展和风险之间找平衡」。1
同一场记者会上,华为半导体业务的首席科学家廖恒把话带到了软件那一层。他说英伟达的 CUDA「已经不是两年前那么重要」,两家的软件差距「已经大幅缩小」。1
这场大会上公布的芯片排期和超节点规格,过去一天已经被转述过很多遍。这一篇值得单独读的地方在另外两处:软件那一层,以及需求的另一侧——徐直军估计,至少六到七家中国 AI 实验室打算在未来两年内训练参数规模 10 万亿到 40 万亿的模型。1
这篇报道写了什么
徐直军在记者会上的主张是速度。他的理由是:美国的主流模型公司算力多,先撞上了模型的危险;中国的开发者还没走到那一步,先加速走到能感觉到危险的位置,再讨论怎么管。这套先后顺序与几天前硅谷的呼声方向相背——Anthropic 与 OpenAI 此前呼吁业界协调减速,让安全措施跟上。1 路透社在同日另一篇稿子里记下了更完整的表述:徐直军说,美国的模型公司因为算力巨大,「也许只有他们自己知道自己的模型处在什么水平」,而他们能感受到的那类 AI 风险,「中国的人或者中国的模型提供商感受不到」。2
硬件那一半:华为说,面向模型训练的昇腾 960DT 定在 2027 年一季度推出,面向推理的那颗定在 2027 年三季度,两颗的算力都是当前旗舰产品的两倍。FT 特别写到,华为去年 9 月以一种不寻常的方式公开了昇腾芯片的多年路线图。1
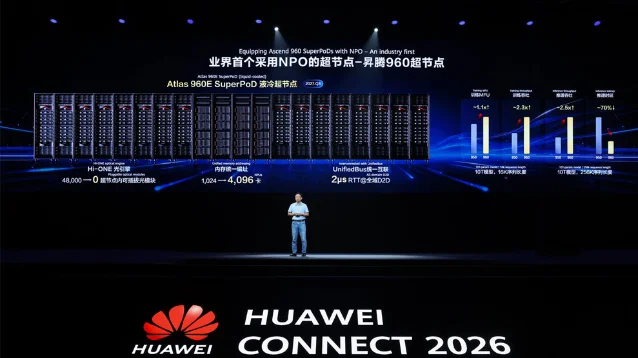
互联那一层被 FT 放在挑战英伟达的核心位置:华为称自己的网络方案能把集群建得比美国对手更大,同时不牺牲带宽与稳定性。这条路线补偿的是单颗处理器的性能劣势,而美国的出口管制让华为用不上台积电这类先进制程代工厂。1 围绕这些芯片的数据中心产品,最多可连 4096 颗昇腾处理器,上一代是 1024 颗,客户因此能训练和运行更大的模型;FT 同一段里写明,华为一直没能让 AI 实验室顺利地把昇腾芯片用于大模型训练。1
份额与自给自足:徐直军估计昇腾在中国的市场份额已经超过英伟达,同时承认可靠数据不易获得。1 他也承认华为在技术上仍「不如美国头部厂商先进」,但认为无法预测的出口管制把中国客户推向了国产方案。「我们不能接受一种自己无法掌控的命运。」他说,「无论对中国政府还是对华为,推动芯片以及整个半导体供应链的自给自足都是前进的方向。」1
软件那一层是廖恒说的。他给出的理由是:越来越大、越来越复杂的模型,训练方式在变,这本身就在削弱 CUDA 的优势——CUDA 长期把开发者锁在英伟达的 GPU 上。他指的是新的编程工具和训练方法正在出现。1
需求那一侧是徐直军给的估计:至少六到七家中国 AI 实验室打算在未来两年内训练参数规模 10 万亿到 40 万亿的模型,比中国现有模型的规模大出一截。1
| 说法 | 谁说的 | 场合与出处 | 能核到什么 | 还缺什么 |
|---|---|---|---|---|
| 中国的研究者要「加快开发速度,这样才能同样看到 AI 开发带来的危险」 | 华为轮值董事长徐直军 | 9 月 17 日上海记者会 1 | 路透社同日稿给出更完整的表述与上下半句 2 | 他说的「危险」具体指哪一类,华为没有展开 |
| 「CUDA 已经不是两年前那么重要」「软件差距已经大幅缩小」 | 华为半导体业务首席科学家廖恒 | 同上 1 | 华为官方通稿给出 CANN 的社区口径:月活开发者突破 5200 名、外部开发者占比 61% 4 | 差距用什么量、跟谁比、多少算「大幅」 |
| 昇腾 960DT 定 2027 年一季度、面向推理的芯片定 2027 年三季度,算力是当前旗舰的两倍 | 华为公司 | 同上 1 | 官方通稿写明 960DT 比原计划提前三个季度、960PR 提前一个季度,并给出「性能实现倍增」;一年前公布的路标里,960 相对 950 系列翻倍 47 | 「当前旗舰」对应哪一颗芯片,两家口径都没有点名 |
| 数据中心产品最多连 4096 颗昇腾处理器,上一代 1024 颗 | 华为公司 | 同上 1 | 官方幻灯片上直接写着「1,024 → 4,096 卡」 3 | 被比较的「上一代」指哪一款:一年前路标里 Atlas 950 满配是 8192 卡,今年 7 月展出的昇腾 950 超节点真机是 1024 卡 67 |
| 昇腾在中国的市场份额已经超过英伟达 | 徐直军 | 同上 1 | FT 写明他承认可靠估计难以获得;华为没有给出支持这个判断的数据 1 | 用哪个口径(出货张数、收入或部署算力)、按哪个时点 |
| 至少六到七家中国实验室两年内训练 10 万亿至 40 万亿参数模型 | 徐直军 | 同上 1 | 华为官方通稿里同方向的刻度是「参数规模已快速迈向 10 万亿,2030 年将超过 100 万亿」 4 | 是哪几家、用谁的算力、训练还是推理 |
「软件差距大幅缩小」这句话能拿什么来对
廖恒是华为 Fellow、半导体业务首席科学家,也是昇腾芯片的核心奠基人之一;他今年 8 月才罕见地接受过一次近五小时的公开专访,谈的是华为对整个半导体产业链的判断。4 这句话从一名昇腾奠基人口中说出来,指向的是英伟达最难被绕开的那一层:软件。
这句话能不能核,取决于拿什么来比。华为和英伟达各自公开的数字是这样的:
| 口径与时点 | 来源 | 英伟达一侧 | 华为一侧 | 这个口径测的是什么 |
|---|---|---|---|---|
| 开发者规模(2026 年) | 英伟达 2025 财年年报 CEO 信 5;华为 7 月与 9 月两份官方通稿 46 | 600 多万名开发者、4 万家公司使用 CUDA | 昇腾 CANN 社区月活开发者:2026 年 7 月突破 3500 人,9 月 17 日突破 5200 名 | 一个是累计的开发者与公司数,一个是月活人数,单位不同,不能相减 |
| 社区构成(2026 年 9 月 17 日) | 华为官方通稿 4 | 未给 | CANN 外部开发者首次超过内部,占比 61%;昇腾覆盖 90 多个主流第三方社区(PyTorch、Triton、vLLM、veRL) | 用这套软件的人里,有多少不是华为员工 |
| 框架官方入口(2026 年 9 月) | 华为官方通稿 4;PyTorch 官网 6 | PyTorch 本地安装页上可勾选的计算平台是 CUDA、ROCm 与 CPU 三种 | 华为称昇腾已成为 PyTorch 官网可直接安装的算力平台,是首个来自中国的算力平台 | 该站另设一个面向合作伙伴与社区的附加平台页,安装命令能否直接从官网拿到,要以那一页为准 |
| 模型训练(2026 年 9 月 17 日) | 华为官方通稿 4 | 未给 | 基于昇腾与 CANN 的原生训练模型超过 40 个;华为称这是国内唯一支持预训练的技术路线 | 有多少模型真的在这套软硬件上完成训练 |
| 生态阶段(2026 年 9 月 17 日) | 华为官方通稿 4 | 未给 | 华为的说法是「昇腾已跨越生态拐点」,CANN 已进入常态化开源社区运作,「从可用走向易用」 | 拐点之前是哪个阶段,这句话本身承认了此前的状态 |
这几行放在一起,能核到的是方向:CANN 的外部开发者第一次超过内部,社区月活人数从 7 月的 3500 人涨到 9 月的 5200 余名 6;昇腾进入了 PyTorch 的安装路径;基于昇腾原生训练的模型数到了可以报出来的量级。华为一年前宣布 CANN 的编译器和虚拟指令集接口开放、其余软件全部开源,当时给出的完成时间是 2025 年 12 月 31 日前。7
核不到的是距离。廖恒说的「软件差距已经大幅缩小」,用的是比较级,但两边从来没有在同一把尺子上量过:华为给的是自己社区的绝对数,英伟达给的是累计开发者与使用 CUDA 的公司数。把 5200 与 600 万放在一起相除,得到的数字不说明任何问题——它们一个按月统计活跃,一个按年累计登记。要验证这句话,要等的是一份第三方对两套软件栈的对照测评,而这样的测评目前没有公开版本。
10 万亿到 40 万亿参数是什么量级
徐直军给的区间,要和当下的模型规模放在一起才有意义。今年 7 月发布的 Kimi K3 有 2.8 万亿参数,官方称它是目前参数规模最大的开源模型。8
| 参照点 | 参数规模 | 时间 | 来源 |
|---|---|---|---|
| 当前中国最大的开源模型 Kimi K3 | 2.8 万亿 | 2026 年 7 月发布 | Kimi 官方文档 8 |
| 徐直军给出的两年目标区间 | 10 万亿—40 万亿 | 2027—2028 年 | FT 1 |
| 华为对行业的公开预期 | 已快速迈向 10 万亿,2030 年超过 100 万亿 | 2026—2030 年 | 华为官方通稿 4 |
按这组参照,徐直军说的区间意味着中国最大的模型要在两年内再长大四倍到十四倍。华为自己的通稿里也给过同方向的刻度:10 万卡集群已成为训练十万亿级模型的标配,而传统服务器架构下,机器之间的通信会吃掉超过 40% 的训练时间。4 围绕超节点的组网上限,官方给出的数字是两层 CLOS 四平面最大 51.2 万卡,再叠加多轨道拓扑可到 100 万卡。4
这里有两处要留意。华为说的是「至少六到七家」中国实验室,没有点名是哪几家,也没有说这些模型打算跑在谁的芯片上;而发布这个消息的公司,正是要卖这些算力的那一家。华为自家幻灯片给出的性能比较,基准也已经定在 10 万亿参数模型上——大屏右下角那四组柱状图的脚下写着这一行。3
同一周里的两种方向
把廖恒和徐直军的话与同一周的其他表态摆在一起,能看到的不只是华为一家的立场。
| 时间 | 主张 | 出处 |
|---|---|---|
| 本周早些时候 | Anthropic 与 OpenAI 呼吁业界协调减速,让安全措施跟上 | FT 9 |
| 9 月 17 日 | 徐直军:中国的研究者要加快开发速度,「这样才能同样看到 AI 开发带来的危险」;危险出现后再在发展与风险之间找平衡 | FT 1、路透社 2 |
| 同期 | 中国监管一侧的路线是边推进边立规:强制标准、安全评估,以及正在起草的 AI 智能体安全强制性国家标准 | 路透社 2 |
徐直军的说法把「看见风险」设成了加速的结果。按他的表述,中国模型公司今天感受不到美国同行描述的那类风险,是因为算力和模型水平还没走到那里;走到之后,行业再来「在推动发展和风险之间找平衡」。2 这套先后顺序与减速呼吁的分歧点很清楚:一边主张先立规再加速,一边主张先加速到能看见风险,再谈怎么管。1
FT 在稿子里把这层对照写在了开头,也把华为的处境写了进去:一家正在卖替代算力的公司,主张本国加速,同时承认自己还不如美国头部厂商先进。1
原文直引
"Chinese researchers needed to 'increase the speed of development so they can also see the dangers of AI development' like their US counterparts … once those risks emerged, the industry would need to 'strike a balance between driving development and risks'."
"We can't accept a destiny that we cannot control. No matter if it's the Chinese government or Huawei, we are pushing for full self-sufficiency for chips and the entire supply chain around semiconductors."
"CUDA is not as important as it was two years ago. … The software gap is greatly diminished."
"At the heart of Huawei's effort to challenge Nvidia is its networking technology, which it says allows it to build larger clusters than its US rival without compromising bandwidth and stability."
"Huawei's data centre product built around the chips will connect as many as 4,096 Ascend processors, compared with 1,024 in the previous generation, allowing customers to train and run larger AI models. The company has struggled to get AI labs to successfully use its chips for training large models."
"Xu said at least six or seven Chinese AI labs were aiming over the next two years to train models containing 10tn to 40tn parameters, a significant increase from current model sizes in China."
以上六处出自 FT 9 月 17 日的报道,作者 Eleanor Olcott,发自上海。1 徐直军那段更完整的表述出自路透社同日稿:
"If we look at the mainstream AI model providers in the United States, because they have massive computing power, maybe only they themselves know where they are in terms of the level of their models. … Maybe the type of risk from AI that they can feel, they can perceive, is something that people in China or AI model providers in China cannot."
"I think maybe AI model providers in China may need to speed up their pace to the level that they could also feel the risks from AI development."
两处出自路透社 9 月 17 日上海与北京稿,记者 Pan Che、Casey Hall、Eduardo Baptista。2
把这批说法拆成四层
| 层次 | 内容 | 依据 |
|---|---|---|
| 媒体措辞 | FT 把这一天写成「中国的 AI 实验室必须加速」;路透社同题稿的落点是中国开发者还没强到能遇见前沿风险 | FT 1、路透社 2 |
| 厂商自述 | CUDA 已不如两年前重要、软件差距大幅缩小;昇腾在中国的份额已超过英伟达;至少六到七家实验室两年内要做 10 万亿到 40 万亿参数模型;推动芯片全供应链自给自足 | FT 1、华为官方通稿 4 |
| 可核到的公开数字 | CANN 社区月活开发者突破 5200 名、外部开发者占比 61%、覆盖 90 多个第三方社区、攀上 PyTorch 官方安装路径;基于昇腾原生训练的模型超过 40 个;960DT 定 2027 年一季度、960PR 定三季度;昇腾 960 超节点单节点 4096 卡 | 华为官方通稿 4、官方幻灯片 3 |
| 仍待核实 | 软件差距用什么口径度量、与两年前的差距缩小了多少;「当前旗舰」指哪一颗芯片;「上一代 1024 卡」对应哪款产品;六到七家实验室是谁、用什么芯片训练;昇腾份额超过英伟达的数据 | FT 1、华为官方通稿 47 |
当天所有能核到的数字,都来自同一个方向:卖算力的一方在描述自己的进展与客户的计划。第三方能对照的只有两件东西——英伟达自己披露的开发者规模,以及接下来第三方对 2026 年中国 AI 芯片出货的实测。前者说明 CUDA 的存量有多大,后者才能说明昇腾的增量有多快。软件那一层的答案,要等有人把两套工具链放在同一套测试上跑一遍。
References
- 1
- 2
- 3华为全联接大会 2026
huawei.com
- 4华为半导体首席科学家罕见露面,谈了什么?
tech.ifeng.com
- 5Annual NVIDIA CEO Letter 2025
images.nvidia.com
- 6Get Started — PyTorch
pytorch.org
- 7以开创的超节点互联技术,引领AI基础设施新范式
huawei.com
- 8Kimi K3 - Kimi API 开放平台
platform.kimi.com
- 9FT 关于这次减速呼吁的报道
ft.com
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.