Microsoft-Decision-1 answers in probabilities. Microsoft's own docs call them relative rankings.
Microsoft-Decision-1 returns a calibrated probability for a fixed set of answers at $0.042 per million input tokens, and Microsoft's own deployment guide limits what that number can be spent on.

"Applications use confidence to decide when to act, defer, or ask for review, so a 90% prediction should be right about nine times out of 10 on representative cases."
Microsoft wrote that sentence about its own new model, and it is the clearest statement of what a decision model is for 1. Software does not need a paragraph. It needs a verdict and a number it can compare against a threshold.
Microsoft-Decision-1 supplies both. Send it a state and a fixed set of answer options, and it returns a probability for each option in a single pass 1. It went live in Microsoft Foundry and on OpenRouter, and Microsoft listed it on Product Hunt on 10 October 2.
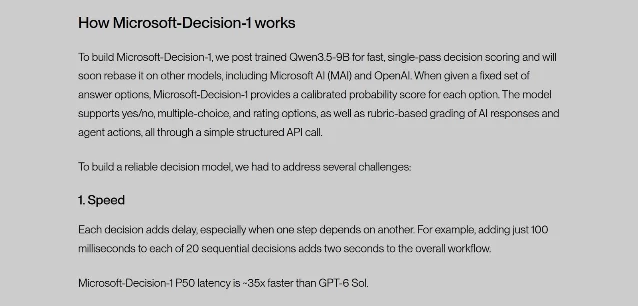
Microsoft also said what the model is built on, in the same post. The company post-trained Qwen3.5-9B for single-pass decision scoring, and it plans to "soon rebase it on other models, including Microsoft AI (MAI) and OpenAI" 1.
Two Microsoft pages then disagree about what the customer is buying. The launch post sells the confidence number as the product. The deployment guide asks the reader to treat that number as a ranking 3.
| Microsoft-Decision-1's claim | What Microsoft's own pages specify | What is still open |
|---|---|---|
| Top accuracy across a 36-benchmark comparison, spanning nearly 150,000 questions 1 | The comparison is Microsoft's own, run on benchmarks the company says were kept blind from training 1 | The post was amended after publication to add Jev's accuracy and calibration figures, and Cloudflare's Qwen-based Clef models were left out 14 |
| A 90% prediction should be right about nine times out of 10 1 | The guide asks for returned scores to be used for relative ordering and thresholds 3 | The threshold itself is yours to validate against your own labeled examples before a gate goes automatic 3 |
| Input tokens at $0.042 per million, output tokens free 1 | OpenRouter lists the same rate, a 33K context window and a single hosting provider 5 | TypeSafe's Jev, which opened this category in September, publishes the identical input price and the same free-output construction 6 |
| Rebased on other models soon 1 | OpenRouter states the weights are updated continually while the API shape stays fixed 5 | No published page describes a version pin, so the model a team evaluates is the model of that week |
What the endpoint actually returns
Start with the part that earns its keep. A decision model answers a question with a typed value instead of a sentence, and that saves an entire parsing layer. Microsoft-Decision-1 takes three question types: a yes-or-no probability, a choice from a fixed list, and a position on an ordered scale 3.
A support ticket is the example Microsoft ships. The caller sends a state string and three questions: whether the message is urgent, which team should handle it, and how frustrated the customer sounds. Three answers come back with probabilities attached 5. An application compares a number to a threshold and either routes the ticket or escalates it. No prose to parse, and no model guessing at a format.
One detail decides how much integration work this costs. The model runs on a decision endpoint rather than the OpenAI-compatible chat endpoint, so an existing chat-completions SDK will not talk to it 5. Callers write against a different request and response shape. On the Foundry side the request addresses a deployment the customer names, and the response reports the model underneath, which can differ from that deployment name 3.
The documented limits are narrow and worth reading before the price. The context window is 33K tokens on OpenRouter 5. The provider is explicit about the job. The model serves classification, routing, prioritization, verification and agent guardrails. The listing states it is not intended for open-ended generation, conversation, translation or summarization 5.
That trade is fine, and a company that wants a cheap gate should take it seriously. A typed answer at $0.042 per million input tokens is a real improvement on asking a chat model for a paragraph and hoping the format holds. The argument is about what the number means, not about whether the shape works.
The number is the purchase, and the manual narrows it
Microsoft's launch post gives the confidence figure a job. Applications read it to decide whether to act, defer or ask a human, and a stated 90% confidence should be right nine times in ten 1. The company tested robustness by perturbing the same request eight ways and measuring how often the answer flipped, and reports an average flip rate of 1.3% 1.
The deployment guide takes the same number and puts the work back on the buyer. For a yes-or-no gate, it tells the reader to choose a probability threshold by workload and validate it against labeled examples before automating anything 3. For a choice question, a low top probability works as a cue to escalate to a person or another model 3.
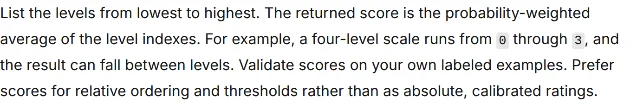
Read together, the two pages describe two different products. One is a calibrated probability a team can threshold on day one. The other is a ranking score whose calibration each buyer establishes locally, with a labeled set the buyer supplies. A team choosing this model should price the second one, because that is the one with the instructions attached.
An outside board measured it, and the board did not move
Microsoft's post names JevBench as the public leaderboard it drew comparison models from 1. That same board then ran Decision-1 itself on a native Microsoft Foundry deployment, and published the result on 10 October 7.
The independent figures are Capability 70.78, Calibration 84.40 and Composite A 69.11, measured on 1,200 sealed plus 300 public observations 7. Twenty-one requests that hit the context limit stayed in the scored denominator rather than being dropped. The board also notes that its existing top five on Composite A and on capped Capability were unchanged by the arrival 7.
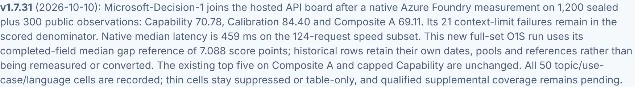
Latency is where the two measurements separate. Microsoft publishes a P50 that is about 35 times faster than GPT-6 Sol, and a comparison putting Decision-1 at 83.5% accuracy and 85 milliseconds 14. JevBench measured a native median of 459 milliseconds on its own 124-request speed subset 7. Different harnesses on different question sets can produce that gap, and the two numbers sit far enough apart that a team planning a latency budget should measure its own.
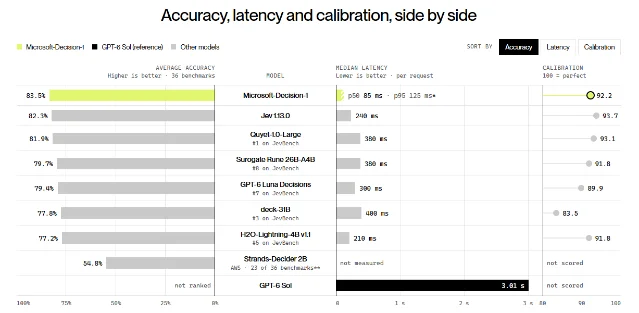
Microsoft's own chart carries a detail worth reading twice. On the calibration axis, which is where the launch post stakes its pitch, the chart scores Decision-1 at 92.2 and Jev, the smaller competitor it beats on accuracy, at 93.7 4.
The chart also labels its nearest competitors with their JevBench positions, placing Quyet-1.0-Large at number one, deck-31B at three, and H2O-Lightning-4B v1.1, the model Microsoft calls the runner-up, at five 4. The board's own entry for Decision-1 reports that its existing top five on Composite A and on capped Capability were unchanged 7.
The category Microsoft entered is also one it arrived late to. Cloudflare shipped Clef and Clef-flash on 1 October. Its launch post concedes the timeline: the decision to build them came on a Friday evening, the training ran over a weekend, and the models shipped on the Thursday 8.
The same post cut Clef-flash to $0.038 per million input tokens and put a multimodal Clef-omni on sale at $0.15 per million 8. Both figures landed while Decision-1 was at $0.042 for text alone.
$0.042 is Jev's number, and the weights are on a schedule
TypeSafe's Jev opened this category in September. Its announcement lists a price of $0.042 per million input tokens with output tokens free 6. Microsoft's launch post lists $0.042 per million input tokens with output tokens free 1. The two prices match to the third decimal. So does the reason both companies can call output free: the model produces a short typed answer instead of generated text, and there is almost nothing to meter.
The durability question is the one a buyer should carry into a contract. Microsoft post-trained one small open-weights model and announced it will rebuild the product on other base models, including its own MAI family and OpenAI's 1. OpenRouter tells the same story from the serving side, stating that the weights are updated continually while the API shape stays fixed 5.
The Foundry documentation shows the same split inside a single request. The deployment name identifies what a customer configured, and the response identifies the model that actually answered 3. A team can name its deployment anything and still be served a different underlying model the following month.
The strongest evidence in the launch post comes from Microsoft's own products, and the numbers are large. Xbox Research ran more than 10,000 pieces of open-ended player feedback through it and reported quality competitive with GPT-6 Sol while running 14 times faster and 200 times cheaper 1. The Copilot team reported it 100 times faster, and Microsoft Discovery reported the score 46 times more consistent for adaptive replanning 1. Every one of those results comes from the vendor measuring its own model inside its own products. A buyer can copy that setup, and reproducing the number is harder.
The verdict
Buy it as the cheapest part of a decision pipeline, and buy the mechanism rather than the pitch. A typed answer with a number attached removes a parsing layer and costs $0.042 per million input tokens. It fits a gate that routes, classifies or flags work before a person or a larger model looks at it 1.
Budget for the part the marketing page leaves out. The returned score is a ranking you calibrate yourself 3. The base model is scheduled to change 15, and the independent board measured a median latency roughly five times Microsoft's own figure 7.
It fits one shape of pipeline: a gate whose failure mode escalates to a person. A refund promise flagged for review costs a minute. The same gate wired to fire automatically costs whatever the wrong answer costs.
One condition before it goes into production. Write down the probability threshold and the labeled set it came from, and re-run that set after every weight change. A model that answers quickly and a model whose number can be spent are two different purchases, and only one of them ships with instructions.
References
- 1Introducing Microsoft-Decision-1, our model for fast decision-making
commandline.microsoft.com
- 2Microsoft-Decision-1 | Product Hunt
producthunt.com
- 3Deploy and use Microsoft-Decision-1 in Microsoft Foundry
learn.microsoft.com
- 4
- 5Microsoft-Decision-1: API Pricing & Providers
openrouter.ai
- 6Introducing System One Models & Jev
typesafe.ai
- 7JevBench: AI decision model benchmark & leaderboard
benchmarkheaven.com
- 8
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.