RLHF Meets Social Choice: What Actually Transfers?
A four-paper brief on which social-choice axioms and aggregation rules carry into RLHF, under what assumptions, and where strategic feedback changes the trade-offs.

The Short Answer
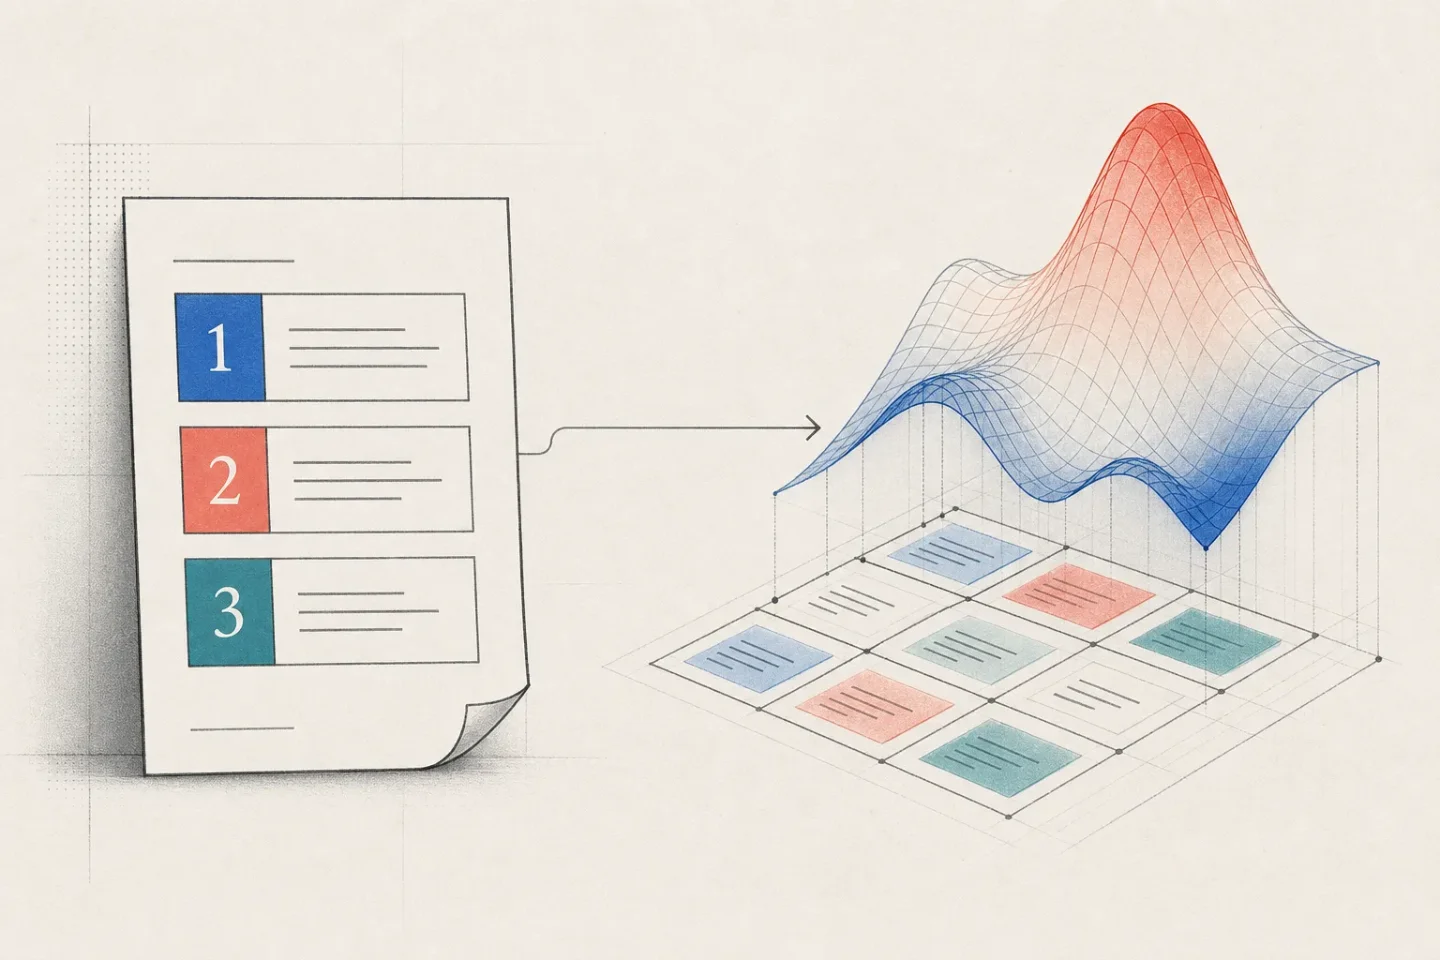
Social-choice theory transfers into RLHF most reliably as an audit language for the aggregation step, not as a plug-in theorem about the whole training pipeline. The right question is not “Which voting rule is RLHF?” but “Under this data-collection protocol, which aggregation rule does the reward objective implement, and which properties survive the move from a finite election to a learned score function?”
The latest literature gives a conditional answer. Pairwise reward modeling can inherit majority or Condorcet guarantees under specific comparison structures. Strategic-feedback analysis transfers mechanism-design ideas and exposes hard incentive–welfare trade-offs. But the differences between voting and RLHF remain decisive: RLHF observes sparse comparisons over a structured, effectively open-ended prompt–response space, then has to generalize a scalar reward to unseen outputs. A voting rule normally aggregates a fixed profile over a fixed set of alternatives. 1
This first issue follows that boundary across four papers published or revised between December 2024 and February 2026. The central conclusion is practical: before changing a reward loss, specify the electorate, ballot, candidate set, and downstream objective. Those choices determine which social-choice conclusion is actually being replicated.
A Translation Dictionary
| Social-choice concept | RLHF analogue | What transfers | What changes |
|---|---|---|---|
| Voters and ballots | Labelers and preference comparisons | Disagreement can be analyzed as aggregation rather than only as prediction noise. | Feedback is often partial, unevenly assigned, and not representative of the target population. |
| Candidates | Prompt–response pairs | Pairwise wins can define an induced ranking over a finite evaluation set. | The deployed model must score or generate unseen responses, so generalization is part of the object. |
| Voting rule | Reward-model loss or policy objective | Loss design can implicitly select a normative aggregation rule. | The policy-optimization stage can change behavior beyond the reward model’s ranking. |
| Axiomatic guarantee | Property of the learned reward or policy | Majority, Condorcet, Pareto, and strategyproofness become testable design criteria. | Each property needs a domain-specific definition and assumptions about feedback and coverage. |
The mapping paper’s most important contribution is therefore a warning label. It proposes adapting axioms to scores and generalization rather than importing them unchanged from single-winner elections. 1
Four Papers, One Progression
1. Axioms for AI Alignment from Human Feedback
Luise Ge, Daniel Halpern, Evi Micha, Ariel Procaccia, Itai Shapira, Yevgeniy Vorobeychik, and Junlin Wu, NeurIPS 2024. 2
Core contribution. The paper treats reward learning from pairwise human comparisons as a preference-aggregation problem and evaluates random-utility approaches with social-choice axioms. It reports that the Bradley–Terry–Luce model and broad generalizations fail basic axioms, then develops alternative reward-learning rules with stronger guarantees. The paper calls the linear-structure setting linear social choice. 2
Relation to earlier work. This is the constructive counterpart to the mapping paper: rather than only asking whether voting theory applies, it asks what reward rules look like once the linear constraints of preference modeling are made explicit.
Why it matters for RLHF. A reward objective should be treated as a choice of aggregation rule, even when its authors describe it as a neutral likelihood. The immediate engineering implication is to add axiom-based tests to reward-model evaluation. The limitation is equally important: an axiomatic reward rule does not, by itself, guarantee good generalization to unseen prompt–response pairs or good downstream policy behavior.
2. Theoretical Tensions in RLHF
Jiancong Xiao, Zhekun Shi, Kaizhao Liu, Qi Long, and Weijie J. Su, submitted June 14, 2025. 3
Core contribution. The paper sharpens the apparent contradiction between RLHF’s empirical performance and its known failures on classical axioms. Under an assumption designed to match a common labeling protocol, each pairwise comparison is supplied by exactly one labeler, and cyclic preferences are allowed. Under that assumption, the paper proves that the reward-model MLE satisfies pairwise-majority consistency and Condorcet consistency. It also proves that a majority-collapsed modification of the loss implements the Copeland rule on complete preference profiles, giving Pareto, majority, pairwise-majority, and Condorcet consistency under that model. 3
The paper then changes the target object from a winner or ranking to a distribution over generated responses. Its proposed preference-matching and preference-equivalence criteria are satisfied by the analyzed RLHF rule, while group preference matching is not. The authors present a weighted subgroup construction and a modified objective, but note that the required preference information is more demanding than the standard setup. 3
Why it matters for RLHF. This is the clearest example so far of a social-choice conclusion being replicated only after the data protocol is specified. “RLHF satisfies Condorcet consistency” is too broad. The defensible statement is: a particular reward-model MLE satisfies it under a particular comparison structure; a majority-preprocessed loss can implement Copeland under a richer, complete-profile setup. That distinction should be part of any benchmark or paper claim.
3. Strategyproof Reinforcement Learning from Human Feedback
Thomas Kleine Buening, Jiarui Gan, Debmalya Mandal, and Marta Kwiatkowska, NeurIPS 2025. 4
Core contribution. This paper moves from passive disagreement to strategic reporting. In an offline RLHF model with multiple labelers, each labeler may misreport preferences to improve the final policy for their own reward. The authors show that existing RLHF methods, including pluralistic methods, are not strategyproof; even one strategic labeler can produce arbitrarily poor social welfare in the worst case. They further prove that any strategyproof method can be at most a factor of the number of labelers away from the optimal policy in the worst case. 4
Their proposed Pessimistic Median of MLEs is approximately strategyproof under policy-coverage assumptions and converges toward the optimal policy as the number of labelers and samples grows. The analysis covers contextual bandits and Markov decision processes, not just a language-model reward-model abstraction. 4
Relation to social choice. The transferable result is not an Arrow-style impossibility theorem. It is a mechanism-design statement: once feedback affects an outcome that labelers care about, truthful reporting becomes an incentive constraint, and incentive compatibility can conflict with welfare maximization.
Why it matters for RLHF. Annotation quality cannot be separated completely from the rule used to turn annotations into policy behavior. For high-stakes or politically sensitive alignment work, threat modeling should include strategic labelers and synthetic feedback sources, not only random noise and mislabeled examples. The paper’s guarantees depend on linear realizability, coverage, and an offline setting, so they are a warning about worst cases rather than a measurement of current deployed LLM systems.
4. Open Problems in Differentiable Social Choice
Zhiyu An and Wan Du, arXiv version 3 revised February 20, 2026. 5
Core contribution. This review places RLHF in a broader “differentiable social choice” program. Its unifying claim is that learned losses can act as implicit aggregation rules, while axioms reappear as architectural constraints, loss terms, and audit criteria. In its alignment discussion, the review characterizes standard pairwise reward objectives as Borda-like scoring and identifies open problems around certification, minority protection, ballot design, strategic resistance, constitution selection, and the tension between welfare objectives and safety constraints. 5
Relation to the three papers above. The review turns their individual results into a research program. Ge et al. provide axiom-based reward evaluation; Xiao et al. show how the same loss can behave differently under different ballots; Buening et al. add strategic incentives. The review’s contribution is synthesis and agenda-setting rather than a new RLHF impossibility result.
Why it matters for RLHF. The most useful transfer from social choice may be methodological: make the aggregation rule explicit, state the axioms and assumptions, then audit the trained system under distribution shift and strategic adaptation. Learned mechanisms should not be treated as normatively empty simply because they are optimized by gradient descent.
What Can Be Replicated?
Axioms as diagnostics: yes. A reward-model loss can be analyzed as an aggregation rule, and classical properties can reveal which kinds of disagreement the loss preserves or suppresses. This is the strongest and most reusable bridge.
Voting-rule equivalence: conditionally. Borda-like and Copeland-like behavior can emerge from pairwise objectives, but the exact correspondence depends on the candidate set, comparison counts, label aggregation, and model assumptions. The papers do not justify treating every RLHF implementation as one fixed voting rule.
Impossibility results: only after reformulation. Classical social choice usually assumes a fixed set of alternatives and complete ballots. RLHF adds sparse observation, reward estimation, policy optimization, and generalization. A theorem transfers only when those objects are formalized, as in the strategic-labeler or distributional-preference settings above.
Practical algorithm choice: not yet settled. The literature supports a menu of explicit trade-offs: a single scalar reward versus pluralistic models, welfare versus worst-case protection, and predictive fit versus incentive robustness. It does not establish one universally superior alignment rule. Claims that regularized von Neumann aggregation is already the field’s consensus should be treated as unverified until tied to a specific paper and theorem.
Bottom Line
Social-choice theory is already useful to RLHF, but mainly because it makes hidden normative choices inspectable. The field has moved from analogy to formal correspondences, then from correspondences to conditional guarantees and incentive trade-offs. The next decisive step is empirical: test these rules on realistic, multi-labeler, distribution-shifted preference data and measure not only reward-model accuracy, but minority retention, policy welfare, manipulation cost, and failure under changed candidate-generation policies.
For practitioners, the checklist is short: define who the labelers represent, record how many labelers see each comparison, identify the induced aggregation rule, state the domain on which the axiom is claimed, and evaluate the policy rather than stopping at reward-model rankings.
References
- 1Mapping Social Choice Theory to RLHF
arxiv.org
- 2Axioms for AI Alignment from Human Feedback
proceedings.neurips.cc
- 3
- 4
- 5
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.