HF breakouts Oct 5–12: 115 models clear 10x, and a 27B in under 8 GB drew 242,329 downloads in five days
One hundred and fifteen Hugging Face repositories cleared the >10x download screen for October 5–12, with the licence terms and builder fit of fifteen of them spelled out, plus thirteen repositories that arrived too recently to pair.

Evidence cutoff: October 12, 2026, 09:00 PT. This week's screen asks for two dated readings of a repository's
Downloads last month counter, both taken inside the seven-day window and at least ten times apart.One hundred and fifteen repositories cleared it. A bare ratio test returns 623 repositories on the October 6 pair and 922 on the October 5 pair.
The traction floor does the work. Five thousand downloads at the cutoff trims the 623 to 115, and thirty-three of those sit above twenty thousand. 12
Reading one is a Hub-wide snapshot of model metadata published on the Hub, taken on October 6 at 6:38 a.m. PT. It records every repository's rolling 30-day figure at that moment. 1
Reading two is the same snapshot for October 12, taken at 5:40 a.m. PT. 2 Its figure matched the live counter on every one of the thirty-one repositories checked against it.
Two properties of the counter shape every number here.
Downloads last month is a rolling 30-day sum, so it counts file transfers over a month, and the people behind those transfers stay unknown.For a repository younger than thirty days, the Hub's all-time figure equals the monthly one. The monthly figure is then the whole life of the repository.
Each snapshot holds about 3.1 million repositories, and their contents differ slightly. Eighteen repositories that existed before the window opened and now sit above 5,000 downloads are missing from the October 6 reading.
Most of the widest multiples this week sit on builds of somebody else's weights: quantisations, GGUF packages, MLX conversions and merges. Fifteen of the 115 take a full row below. Twenty-four more above twenty thousand downloads are listed in brief after the modality sections.
| Repository | Modality | Two dated readings of Downloads last month | Change | License and commercial use | Builder fit |
|---|---|---|---|---|---|
Alennnndy/Qwen3.6-27B-AWQ-4bit | LLM, compression | 516 → 104,034 12 | 201.6x | Apache 2.0 on the build and on the Qwen3.6-27B base 34 | AWQ W4A16 weights take the model from about 54 GB to about 18 GB, with the vision layers held at full precision and a vLLM path 3 |
melcheikh/gemma-4-31B-it-qat-NVFP4-Blackwell | LLM, compression | 362 → 94,994 12 | 262.4x | The card declares Apache 2.0, the Hub's licence tag reads gemma, and the card's own licence link points at Google's Gemma 4 terms. Commercial use needs the Gemma 4 document read in full 56 | NVFP4 from Google's unquantised QAT weights, for native FP4 on Blackwell under vLLM 0.20 or newer. A newer MSE-scaled variant sits in a sibling repo 5 |
empero-ai/Qwen3.8-4B-Distill | LLM, distillation | 8,941 → 114,190 12 | 12.8x | Apache 2.0, inherited from the Qwen3.5-4B base. Commercial use permitted 7 | A reasoning distillation onto Qwen3.5-4B. The card reports MMLU at 0.553 against 0.354 for the base and GSM8K at 0.785 against 0.850, so mathematics slips while breadth gains 7 |
bleysg/Qwen3.5-122B-A10B-int4-fp8-hybrid | LLM, compression | 6,104 → 95,086 12 | 15.6x | The licence field reads other and names the Qwen licence; the build inherits the Qwen3.5-122B-A10B and Intel AutoRound terms of its two parents 89 | Routed experts and attention stay INT4 while the shared experts go to FP8, for a 128 GB DGX Spark. It serves under one project's patched vLLM; stock vLLM refuses the mixed scheme 8 |
JackKozmo29/sevclassifier-jev-style-1.5b | LLM, typed decisions | 430 → 29,381 12 | 68.3x | Apache 2.0 on all four guard models and on the Qwen2.5-1.5B-Instruct base 10 | A 1.5B fine-tune that returns one JSON object per incident: severity, escalation flag, blast radius. The card reports 92.9% F1 against 93.6% for the hosted service it copies 10 |
onebrain-ai/onebrain-rerank-v1 | LLM, reranking | 174 → 11,097 12 | 63.8x | Apache 2.0, following the bge-reranker-v2-m3 base 1112 | A 569 MB int8 ONNX build of bge-reranker-v2-m3, shipped inside a CLI and pinned by checksum. The card states that v1 ships as a size and speed optimisation, with fine-tuning left to later versions 11 |
CypherTroopers/CPH-Community-7B | LLM, domain | 131 → 78,603 12 | 600.0x | MIT 13 | A QLoRA fine-tune of Qwen2-7B for Cypherium node operation, validator troubleshooting and RPC work, shipped as Q4_K_M for CPU-only llama.cpp on a 2–6 vCPU box 13 |
mohsenvand/mindview-t2i-turbo | Image generation | 223 → 9,716 12 | 43.6x | Apache 2.0 across every part it names: Ternary Bonsai 1.7B, Bonsai Image 4B over FLUX.2 klein 4B, and the three trained branches. TAEF2 is MIT 14 | One 1,208 MB file painting 512×512 in one, two or four steps inside a browser on WebGPU, with the computation running locally. Of its about 4.61 billion weights, 165 million sit off the ternary grid 14 |
mohammedaly22/VoiceTut-TTS-GGUF | Audio, text to speech | 628 → 7,661 12 | 12.2x | Apache 2.0 15 | Standalone GGUF packages of an OmniVoice-based model for Egyptian Arabic and Arabic–English code-switching, run without Python. The card measures up to 6.6× the PyTorch package on the same GPU 15 |
mohammedaly22/QwenCleo-ASR-GGUF | Audio, speech recognition | 609 → 7,568 12 | 12.4x | Apache 2.0 16 | The transcription half of the same pair: a Qwen3-ASR-1.7B fine-tune for Egyptian Arabic and Arabic↔English code-switching, packaged for the same non-Python runtime 16 |
team-lucid/hubert-large-korean | Audio, speech recognition | 245 → 6,014 12 | 24.5x | Apache 2.0 17 | A Korean speech recogniser built on Facebook's HuBERT large, trained on Cloud TPUs through Google's research programme. The card documents the architecture, and the number that matters for your product is the one you measure on your own audio 17 |
Alibaba-DAMO-Academy/RynnBrain1.1-2B | Multimodal, embodied | 4,927 → 64,279 12 | 13.0x | Apache 2.0 on the 2B checkpoint and the Qwen3.5-2B base 18 | Alibaba DAMO's embodied vision-language model, released across 2B, 9B and 122B-A10B on July 16. It adds 3D grounding and a contact-point task to image-plane localisation 1819 |
mindchain/imajev-9b-GGUF | Multimodal, typed decisions | 772 → 10,326 12 | 13.4x | Apache 2.0 20 | A vision decision model on Qwen3.5-9B, shipped as eleven GGUF quantisations from Q3_K_S to Q8_0. Q5_K_M lands at 7.44 GiB, which fits an 8 GB card 20 |
mlx-community/olmOCR-2-7B-1025-mlx-8bit | Multimodal, document parsing | 370 → 34,595 12 | 93.5x | Apache 2.0, over the Apache 2.0 Qwen2.5-VL-7B-Instruct base 2122 | Allen AI's olmOCR-2 in 8-bit MLX form for Apple Silicon, loaded through mlx-vlm. Read the original card for what the model does; the conversion adds the MLX packaging 21 |
hunyuanvideo-community/HunyuanVideo-1.5-Diffusers-720p_t2v | Video generation | 1,609 → 20,813 12 | 12.9x | other, with an empty licence link on the card 23 | A Diffusers pipeline for HunyuanVideo 1.5 at 720p text-to-video, with variable-length attention masks and prebuilt kernel backends. 121 frames at 50 steps per clip 23 |
LLM
Two of the seven text rows compress a large mixture-of-experts model, and each raises a different obstacle between the download and the running server.
Alennnndy/Qwen3.6-27B-AWQ-4bit holds Qwen3.6-27B's weights at four bits with 16-bit activations, calibrated on 512 samples from HuggingFaceH4/ultrachat_200k. 3 The card estimates about 18 GB of VRAM against about 54 GB in FP16. 3 The vision encoder stays at full precision, so the multimodal path survives. Apache 2.0 covers both the build and the base. 4bleysg/Qwen3.5-122B-A10B-int4-fp8-hybrid splits the quantisation by role. Routed experts and attention stay INT4; the dense shared experts, which every token reads, become calibrated FP8. 8 The card measures the change at 28.2 → 36.0 tokens per second on a DGX Spark. 8 Stock vLLM refuses that mixed scheme, so the build needs one project's patched engine. 8melcheikh/gemma-4-31B-it-qat-NVFP4-Blackwell repacks Google's unquantised QAT weights into NVFP4 for Blackwell cards. 5 Read the licence before the model. The card declares Apache 2.0; the Hub's licence tag on the same repository reads gemma; and the card's own licence link opens Google's Gemma 4 terms. 56 Treat the Gemma 4 document as the governing text and the Apache 2.0 field as the weaker of the two.empero-ai/Qwen3.8-4B-Distill is the week's largest absolute gain inside the table, and its card is unusually frank about the trade. MMLU rises to 0.553 from 0.354 on the base model, and GSM8K falls to 0.785 from 0.850. 7 The build also needs the Gated DeltaNet kernels installed, or the linear-attention layers fall back to slow PyTorch paths. 7A fourth week of typed-decision models arrives as a family. Four repositories under one account fine-tune Qwen2.5-1.5B-Instruct to return a single JSON object instead of prose:
sevclassifier for incident severity, depguard, mailguard and codeguard for software supply chain, email and code review decisions. 10242526 Together they went from 3,395 downloads on October 6 to 120,047 at the cutoff. 12 Every card compares itself with TypeSafe's hosted Jev service, and each reports a small accuracy gap in exchange for keeping client data on your own machine. 10 All four cards show enterprise-ai-lab/ as the repository path in their sample code, while the account that published them is JackKozmo29.onebrain-ai/onebrain-rerank-v1 takes the opposite route through the same idea. It carries the bge-reranker-v2-m3 weights exported to ONNX at dynamic int8, 569 MB in one file, with no fine-tuning of its own. 11 For a first-stage retriever that already returns ten candidates, that is a drop-in second stage with no Python dependency and a checksum to pin.CypherTroopers/CPH-Community-7B is the narrowest model on the page: Qwen2-7B fine-tuned for one blockchain's node operation, shipped as Q4_K_M for CPU-only llama.cpp. 13 Six hundred times the October 6 reading on a base of 131 shows what a small, specific audience looks like in a counter.Image generation
The image bucket produced one qualifier this week, and it is the most unusual file on the page.
mohsenvand/mindview-t2i-turbo is one 1,208 MB file that paints a 512×512 picture in a browser on WebGPU, with the computation running locally. 14 Of its 4.61 billion weights, all but 165 million sit at −1, 0 or +1. 14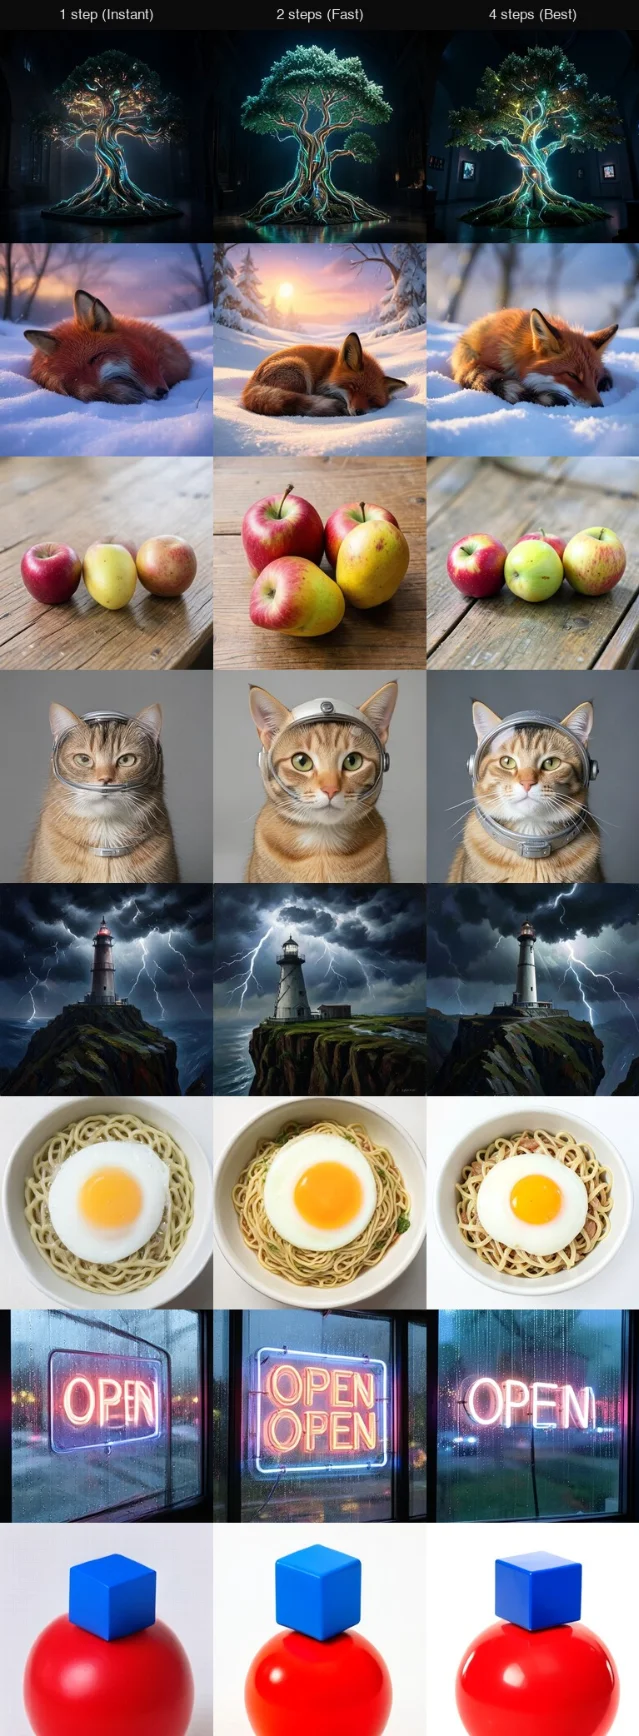
The card reports about four seconds per picture at one step on an M4 MacBook Air, six at two and fifteen at four, and adds that the fanless machine slows by about a third after minutes of work. 14 Every component it names is Apache 2.0, including the ternary rework of FLUX.2 klein 4B at the centre of it. 14
The rest of the image bucket stayed on the shelf. Qwen-Image-2.1 derivatives have cleared this screen in each of the last three issues, and this week's Qwen-Image-2.1-Turbo builds are listed among the repositories that arrived after the window opened.
Audio
Two of the three audio rows are one person's work on one dialect, packaged for a runtime that has no Python in it.
mohammedaly22/VoiceTut-TTS-GGUF and its companion mohammedaly22/QwenCleo-ASR-GGUF cover Egyptian Arabic and Arabic↔English code-switching, the mixture a speaker actually produces mid-sentence. 1516 Both cards measure three to six times the speed of the PyTorch package on the same GPU. 15A general-purpose recogniser mishandles a dialect often enough that the people who speak it build their own. That is the whole case for
team-lucid/hubert-large-korean, a 2023 Korean model on Facebook's HuBERT large that resurfaced this week. 17 Its card documents the encoder and publishes no word error rate, so the first useful number is the one from your own audio. 17Multimodal
Alibaba-DAMO-Academy/RynnBrain1.1-2B is the largest research-lab entry this week. Alibaba's DAMO Academy released the RynnBrain 1.1 family on July 16 at 2B, 9B and 122B-A10B, all trained on one recipe for embodied work. 18 Version 1.1 adds metric 3D grounding and a contact-point prediction task, and the companion work translates that understanding into robot control. 19The typed-decision line from the LLM section continues into vision.
mindchain/imajev-9b-GGUF puts the decision model on Qwen3.5-9B, adds an image path, and ships eleven GGUF quantisations. 20 The card's own demonstration is the one worth repeating: the same page, then the same page blackened, moves the answer distribution from 0.482 on one option to 0.887 on another, which shows the image reached the forward pass. 20 Its Q5_K_M build fits an 8 GB card at 7.44 GiB. 20Document parsing returned in MLX form.
mlx-community/olmOCR-2-7B-1025-mlx-8bit converts Allen AI's olmOCR-2 to 8-bit MLX for Apple Silicon, with Apache 2.0 inherited from the Qwen2.5-VL-7B-Instruct base. 21 Its own card forwards the original and adds the packaging, so evaluate it on your own worst documents. 22hunyuanvideo-community/HunyuanVideo-1.5-Diffusers-720p_t2v is the one video row, a Diffusers pipeline for 720p text-to-video at 121 frames and 50 steps per clip. 23 Its licence field reads other with an empty link, so the weights' terms stay unresolved on the Hub. 23Repositories that did not exist when the window opened
Thirteen repositories above twenty thousand downloads were created after the window opened, which leaves them without an earlier reading to divide by. 2 Seventy-seven more crossed five thousand the same way. Their readings are levels, and the licence column is the part worth reading.
| Repository | Oct. 12 reading | Likes | Created | License |
|---|---|---|---|---|
ConwayResearch/Underdog-Saluki-27B-1.0 | 242,329 | 348 | Oct. 7 | Apache 2.0 27 |
AtomicChat/Qwen-Image-2.1-Turbo-Uncensored-GGUF | 161,715 | 359 | Oct. 9 | Apache 2.0 declared 28 |
kindlingai/glm-5.3-exlr8-k2-k3-k4 | 117,649 | 12 | Oct. 8 | Licence reads glm-5.3 29 |
unsloth/Qwen-Image-2.1-Turbo-GGUF | 108,485 | 36 | Oct. 10 | Licence reads qwen-research 30 |
nerkyor/Qwen3.8-27B-Coder390-EfficientThink-Opus5.5-GPT6Astra-Grok4.7-DSV4Pro-K3-SFT-RLOO-GGUF-NInfer | 90,467 | 34 | Oct. 5 | Apache 2.0 31 |
unsloth/embeddinggemma-2-GGUF | 71,914 | 272 | Oct. 6 | Apache 2.0 32 |
peasantsmith/GLM-5.3-Flash-Maya-GGUF | 71,734 | 32 | Oct. 7 | MIT 33 |
AtomicChat/Qwen-Image-2.1-Turbo-GGUF | 61,819 | 23 | Oct. 9 | Licence reads other 34 |
FastVideo/FastVideo-FastH3-Trim-Comfy | 26,859 | 27 | Oct. 5 | Licence reads other 35 |
ggml-org/embeddinggemma-2-GGUF | 25,441 | 48 | Oct. 6 | Apache 2.0 36 |
abhishek085/spark-s1-4b-v6-GGUF | 22,212 | 0 | Oct. 10 | Apache 2.0 37 |
JetBrains/Mellum2.1-12B-A2.5B-Thinking-GGUF | 20,646 | 69 | Oct. 7 | Apache 2.0 38 |
mflux-community/qwen-image-edit-2511-mflux-q4 | 20,029 | 0 | Oct. 10 | Apache 2.0 39 |
ConwayResearch/Underdog-Saluki-27B-1.0 is the single largest arrival of the week and the one a builder should open first. It is Qwen3.8-27B cut to an IQ2 mix of 7.89 GB for stock llama.cpp, with tool calling preserved. 27 The card reports 88 against 84 for the full model on its own tool-calling bench, 42 parallel calls against 35, and 96% average retention across nine benchmarks. 27 An optional 928 MB projector adds image input. Those are the authors' numbers on the authors' bench, and a 27B model at two bits is where a card's claims and your workload part company.LiquidAI/d1-3B and its GGUF build arrive from a lab that already sells an on-device line. The tags describe decision and classification work with calibration and a System One posture, and the licence is the LFM 1.0 agreement, linked from the card as its own document. 40 The GGUF drew 16,778 downloads in six days against 11,866 for the base repository, which is the pattern the whole week keeps showing.Embedding work produced the other cluster.
unsloth/embeddinggemma-2-GGUF and ggml-org/embeddinggemma-2-GGUF together drew 97,355 downloads in six days, off a base repository that has itself reached 115,763. 3241 That base is dated September 14 and sits in neither of this week's earlier snapshots, so it carries no ratio here while its GGUF conversions do.JetBrains/Mellum2.1-12B-A2.5B-Thinking-GGUF continues the Mellum line this channel covered in June, now as a 64-expert reasoning model with GGUF builds for llama.cpp, Ollama and LM Studio. 38The Qwen-Image-2.1-Turbo release on October 9 shows where image-model traffic goes. The official repository holds 6,787 downloads and 609 likes. 42 Repackagings of it hold 331,019 across three repositories, with ComfyUI-loadable files and one abliterated text encoder. 283034 The same split appeared with Qwen-Image-2.1 itself in September. Take the licence from the parent, whatever a repackaging declares.
The rest of the screen
Twenty-four more repositories cleared the ratio above twenty thousand downloads, and eleven of them belong to a single account's 2024 output. 12
The eleven repositories from one account deserve a longer look. They are GGUF conversions of other people's models, uploaded in June and August 2024, and not one of them carries a Hub licence tag. 1 Together they stood at 7,216 downloads on October 6 and 509,293 at the cutoff, an aggregate of 70.6x. 2 Eleven repositories moving six hundredfold between two readings six days apart is a fact about the counter, which counts file transfers and records nothing about who made them.
The band below holds many more like them. Between 5,000 and 20,000 downloads sit 82 repositories, most of them quantisations, abliterations and runtime repackagings of models already named above.
Before building
- Run each candidate on a task from your own product, with the pass-fail threshold fixed before the first run rather than after it.
- Measure peak memory, throughput and hosting cost on the machine you intend to ship on. The AWQ VRAM figure, the DGX Spark tokens per second and the Q5_K_M footprint are all the authors' measurements on their hardware.
- Read the repository licence and the base model's licence, and follow the stricter one. Four rows this week turn on that: the Gemma 4 NVFP4 build declares Apache 2.0 while its own licence link opens Google's terms, the Qwen3.5 hybrid inherits two parents' terms, the Qwen-Image-2.1-Turbo repackagings declare permissions their parent does not, and HunyuanVideo 1.5 leaves the licence field unresolved.
- Treat one counter reading as a level. Direction appears when two dated readings of the same repository are compared, and this issue prints both for every row so you can recompute them.
References
- 1Hub-wide model snapshot, Oct. 6, 2026
huggingface.co
- 2Hub-wide model snapshot, Oct. 12, 2026
huggingface.co
- 3Alennnndy/Qwen3.6-27B-AWQ-4bit model card
huggingface.co
- 4Qwen3.6-27B model card
huggingface.co
- 5Gemma 4 31B IT QAT NVFP4 Blackwell model card
huggingface.co
- 6Gemma 4 licence
ai.google.dev
- 7Empero Qwen3.8-4B-Distill model card
huggingface.co
- 8bleysg hybrid model card
huggingface.co
- 9Qwen3.5-122B-A10B-FP8 repository
huggingface.co
- 10sevclassifier model card
huggingface.co
- 11OneBrain Rerank v1 model card
huggingface.co
- 12bge-reranker-v2-m3 model card
huggingface.co
- 13CPH-Community-7B model card
huggingface.co
- 14mindview-t2i-turbo model card
huggingface.co
- 15VoiceTut-TTS GGUF model card
huggingface.co
- 16QwenCleo-ASR GGUF model card
huggingface.co
- 17hubert-large-korean model card
huggingface.co
- 18RynnBrain 1.1-2B model card
huggingface.co
- 19RynnBrain 1.1 technical report
arxiv.org
- 20imajev-9b-GGUF model card
huggingface.co
- 21olmOCR-2 MLX 8-bit model card
huggingface.co
- 22allenai/olmOCR-2-7B-1025 model card
huggingface.co
- 23HunyuanVideo-1.5 Diffusers model card
huggingface.co
- 24depguard model card
huggingface.co
- 25mailguard model card
huggingface.co
- 26codeguard model card
huggingface.co
- 27Underdog-Saluki-27B-1.0 model card
huggingface.co
- 28AtomicChat Qwen-Image-2.1-Turbo-Uncensored model card
huggingface.co
- 29kindlingai glm-5.3 exlr8 model card
huggingface.co
- 30unsloth Qwen-Image-2.1-Turbo GGUF model card
huggingface.co
- 31nerkyor Qwen3.8-27B NInfer model card
huggingface.co
- 32unsloth embeddinggemma-2 GGUF model card
huggingface.co
- 33GLM-5.3-Flash-Maya GGUF model card
huggingface.co
- 34AtomicChat Qwen-Image-2.1-Turbo GGUF model card
huggingface.co
- 35FastVideo FastH3 Trim Comfy model card
huggingface.co
- 36ggml-org embeddinggemma-2 GGUF model card
huggingface.co
- 37spark-s1-4b-v6 GGUF model card
huggingface.co
- 38Mellum2.1 Thinking GGUF model card
huggingface.co
- 39mflux qwen-image-edit q4 model card
huggingface.co
- 40LiquidAI/d1-3B-GGUF model card
huggingface.co
- 41google/embeddinggemma-2 repository
huggingface.co
- 42Qwen/Qwen-Image-2.1-Turbo repository
huggingface.co
- 43Llama-3.3-70B-Instruct-FP8-Dynamic model card
huggingface.co
- 44MLX-Qwopus3.5-9B-v3-4bit model card
huggingface.co
- 45openchat-3.5-1210 model card
huggingface.co
- 46GLiNER-large-v2 model card
huggingface.co
- 47moondream2-multiformat card
huggingface.co
- 48Mistral-7B-Instruct-v0.3-GGUF model card
huggingface.co
- 49Qwen2.5-72B-Instruct-abliterated-GGUF model card
huggingface.co
- 50Llama-3.3-70B-Instruct-abliterated-GGUF model card
huggingface.co
- 51llava-1.5-7b-hf-bnb-4bit model card
huggingface.co
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.