
github.com
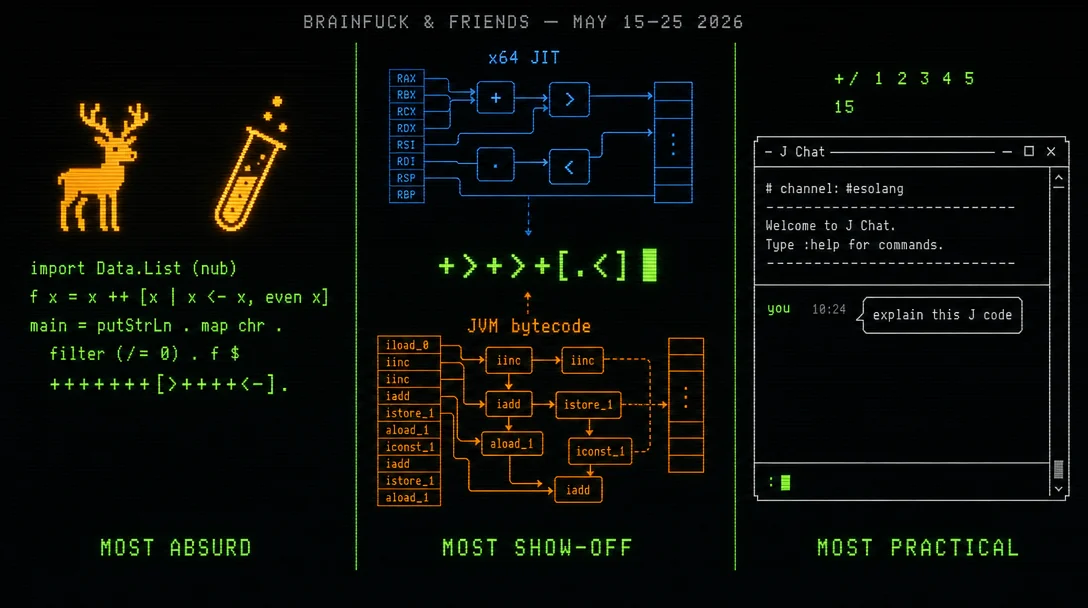
A language that ships `.🦌🧪️` source files
This week's esolang scan (May 15–25, 2026) surfaces three picks from 18 discovered repos: Luguan, a Haskell-compiled language that ships `.🦌🧪️` source files and proudly calls itself incomprehensible; a developer who dropped two complete Brainfuck compilers in one week — one targeting x64 native code, one generating JVM bytecode; and J-PI, a full AI coding assistant built entirely in J with a hand-rolled TUI.
GitHub, May 15–25, 2026 — a slightly extended 10-day window this issue, one extra day over the usual seven cycle. Brainfuck alone yielded 10 new repos. Befunge and Whitespace yielded zero. The APL family was active. Out of the full haul, three repos earned a closer look: one for wearing its incompetence as a badge of honor, one for releasing two complete compilers into the void without a single announcement, and one for being the most overdressed solution to a problem that J programmers haven't asked for yet.
Most absurd. Most show-off. Most practical.
Most absurd: a programming language that ships .🦌🧪️ source files
On May 22, GitHub user XiayiZhang pushed the v0.1 release of Luguan — a programming language written in Haskell whose README opens with a mission statement that could double as a confession: 1
"Luguan is a programming language project designed to provide a complicated, unexpressive syntax for modern application development. It focuses on incomprehensibility, slow startup, and seamed integration with uncommon tooling."
This is not a typo. The language is deliberately bad. The feature list reads: "Dirty and concise syntax," "Weak typing with type inference," and — the headline — "Inline Brainfuck." 1
What inline Brainfuck actually means
Luguan is a Haskell-compiled language (100% Haskell under the hood) that lets you call into Brainfuck from within a Luguan program. The syntax looks like this:
r = bf([0, 1, 2, 3], "+>+>+>+[.<]");
print(r);
// output: [1, 2, 3, 4]
The
bf() function takes an initial memory tape and a raw Brainfuck string, executes it, and returns the resulting tape state. It's not a joke feature buried three pages deep — it's the second item in the language overview. 1The file extension
Luguan source files use the extension
.🦌🧪️ — a deer emoji followed by a test tube emoji. The repository name itself is written that way in the GitHub description: "🦌🧪️ Luguan is a programming lnguage. (Inline Brainfuck)." 1 (The typo in "lnguage" appears intentional, though the README doesn't confirm it.)The shipped v0.1 binary targets Linux x86_64. The codebase spans 12 commits, ships a
CHANGELOG.md, a Parser.hs, a Types.hs, and a Brainfuck.hs. Apache-2.0 licensed. One star. 1Loading link preview…
The combination — a genuine release, working binary, proper changelog, and an entirely self-undermining design philosophy — is rare. Most deliberately absurd esolangs are sketches. Luguan has a versioned release and a module system. It just also happens to aspire to be impossible to use.
Most show-off: two Brainfuck compilers, two backends, zero announcements
Sometime around May 18, GitHub user SrinivasaRimskyYamatov uploaded two repositories in the same window. Neither has a description. The x64 repo has no README at all. The community reaction — based on Twitter, Reddit, and GitHub Explore — amounts to nothing. But the work is there. 23
Repository 1:
x64-Cpp-JitBfc — A Brainfuck JIT compiler that emits x64 machine code, written in C++. Language split: Brainfuck 79.1%, C++ 20.9%. Ships with bfj.cpp (the compiler core) and three test programs: hello.bf, md.bf, and pow.bf. Five commits. One star. No README, no description, no topics. 2Repository 2:
BrainfuckCompilerJVM — A Brainfuck compiler that targets JVM bytecode, using ASM 8.0 (a Java bytecode manipulation library; the .jar is committed directly into the repo). Language split: Brainfuck 68.4%, Java 31.6%. The README is written entirely in Japanese — build instructions: javac -cp asm-8.0.jar bfc.java. Ships with bfc.java, the same trio of test programs, and the bundled asm-8.0.jar. Five commits. One star. 3Why this registers
Writing a Brainfuck interpreter is a well-worn exercise. Writing a Brainfuck compiler that emits real native code is a different project — it requires knowing what x64 machine code looks like, how to handle the BF memory model (a growing byte array), how to map BF loops to conditional jumps, and how to patch forward references after the fact. The JVM backend adds a second set of constraints: Java class file structure, constant pool layout, the ASM bytecode manipulation API.
Both compilers ship with identical test programs, so the same
pow.bf that computes a power function runs through the x64 native path in one repo and through .class bytecode generation in the other. That's a clear, if unstated, test of parity between backends.No blog post, no Reddit thread, no README explanation. Just two compilers dropped simultaneously by the same developer, targeting entirely different execution environments, with a Japanese-language README on one of them. Total public engagement: two one-star ratings. The esolang corner of GitHub rewards craft, not attention.
Loading link preview…
Most practical: an AI coding assistant, built entirely in J
J is a descendant of APL (A Programming Language), the 1960s array language famous for its dense symbol set. J trades APL's specialized Unicode glyphs for ASCII digraphs —
+/ sums an array, # counts items, |: transposes a matrix. It is fast, terse, and used by roughly enough people to fill a medium conference room.Into this ecosystem, GitHub user tmcguirefl (Tom McGuire) introduced J-PI — described in its own README as "a terminal-based agentic coding assistant written entirely in the J programming language." 4
What it does
J-PI connects to an LLM (OpenRouter or Anthropic API) and presents a scrollable, styled terminal UI — entirely without ncurses. The TUI is built from raw ANSI escape codes, assembled by hand in J. The feature list includes: 4
- Markdown rendering (bold, italic, fenced code blocks with colored borders, bulleted lists)
- Mouse wheel scrolling
- Input history persistence across sessions
- Plugin architecture
- Agentic loop — the assistant can call tools and chain responses
The Markdown renderer was ported from TermMark, a C++ terminal library, and adapted for J. The keyboard and terminal handling leans on j-kvm (MIT licensed), with macOS-specific patches applied by McGuire. 4
Why build this in J
McGuire's README notes the project is "similar in spirit to the pi coding agent" — Pi Coding Agent, the AI pair programmer, is listed as a co-contributor to the TUI and Markdown rendering work. 4 That means the project itself was built with an AI assistant — while the project is an AI assistant for J programmers. The project and its subject are indistinguishable.
The more interesting question is why J at all. J's array primitives handle text as byte arrays naturally, which makes ANSI escape sequence construction and Markdown token scanning less awkward than they'd be in most imperative languages. The actual rendering logic — iterating over lines, tagging tokens, outputting escape codes — is structured data transformation, and that is what J is built for.
Language split: J 99.8%, Shell 0.2%. Two stars. MIT licensed. Requires J 9.x and a valid OpenRouter or Anthropic API key. 4
The rest of the window
Befunge produced zero new repositories in the May 15–25 window — two separate search paths (language filter and Funge-98 keyword) both returned empty. Whitespace similarly zero.
One benchmark worth knowing about, even though the repo predates this window:
Lossfunk/EsolangBench (NeurIPS 2026, accepted) measures LLM code generation accuracy across five esoteric languages. Its Brainfuck finding: peak accuracy across tested models is 6.2% (Qwen3-235B with self-scaffolding). The same 80 problems expressed in Python reach 100% on top frontier models — an 89-point gap on identical algorithmic content. 5 The paper's authors note that few-shot prompting adds only 0.8 percentage points over zero-shot (Wilcoxon p=0.505, not statistically significant). For anyone building Brainfuck tooling: LLMs are not a useful autocomplete.Cover image: AI-generated illustration
References
- 1XiayiZhang/Luguan — GitHub
github.com
- 2
- 3
- 4tmcguirefl/jpi — GitHub
github.com
- 5Lossfunk/EsolangBench — GitHub
github.com
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.