The 2× speedup your inference stack has been ignoring
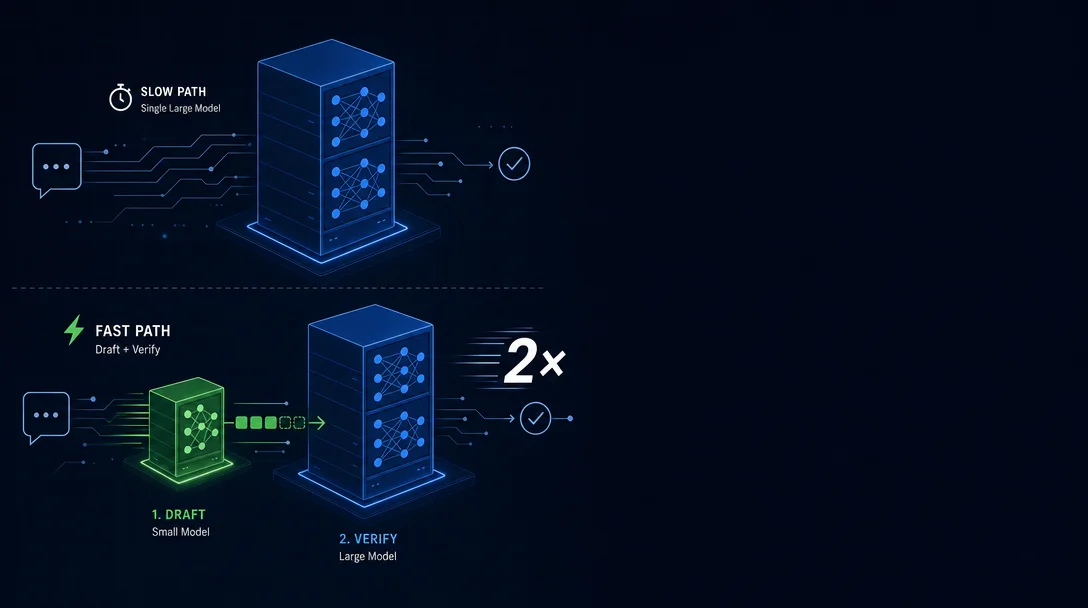
Speculative decoding has been in vLLM for a year but disabled in production because of attention drift. EAGLE 3.1, released May 26, fixes the root cause with two architectural changes — and delivers a verified 2× throughput gain with one JSON config flag. Here's what changed, why it matters, and when to turn it on.

There's a setting in vLLM that could cut your per-user token latency roughly in half. You've probably heard of it. You probably haven't turned it on.
That's not a team failure — it's the correct call based on what the technology was doing until about a week ago.
Loading stats card…
What speculative decoding actually is
A large language model generates one token at a time. Each token is expensive to produce. Speculative decoding shortcuts around it: a small, cheap draft model — often 3–5% the size of the target model — guesses several tokens ahead, and the large model verifies all of them in a single pass. Accepted guesses ship immediately; rejected ones fall back to the large model's output. The result is mathematically identical to unassisted generation — no quality trade-off. 1
The throughput gain is arithmetic: if draft guesses are right most of the time, you get 3–5 tokens out per large-model execution instead of 1. For inference workloads where the bottleneck is memory read speed rather than raw compute — most production setups at moderate concurrency — that multiplier goes straight to cost savings.
As Michael Gannotti (Principal AI Solutions Architect at Microsoft) noted:
"Speculative decoding has a marketing problem. The pitch sounds too good to be true: run a small draft model alongside your large model, guess multiple tokens ahead, verify in parallel, and get 1.5–3× throughput with zero quality loss." 2
He's right that it sounds suspicious. He's also one of the engineers who just explained why it's now safe to enable.
Why it kept breaking in production
The reason teams were turning speculative decoding off — quietly, without much documentation — is a phenomenon researchers named attention drift. 3
Here's the mechanism. As the draft model guesses deeper into the future, its attention progressively shifts away from the original prompt's anchor tokens and toward the tokens it just generated — effectively talking to itself instead of grounding on the user's input. Two architectural flaws caused this: higher-layer hidden states dominated the draft model's input in an unbalanced way, and unnormalized residuals caused hidden-state magnitudes to grow with each step, making the drafter increasingly unstable at depth. 3
The symptom: a collapsing acceptance rate. When the fraction of draft tokens the target model keeps falls below roughly 0.5, speculative decoding runs slower than no-spec baseline. Teams noticed degraded behavior in long-context and non-coding workloads, couldn't isolate why, and disabled the feature.
On May 11, Doğaç Eldenk and collaborators formally identified and named the phenomenon. 3 Two weeks later, the EAGLE team, vLLM team, and TorchSpec team shipped the fix.
What EAGLE 3.1 changes
EAGLE 3.1 (released May 26, 2026, by the EAGLE team, vLLM team, and TorchSpec team) fixes attention drift with two targeted changes. 1
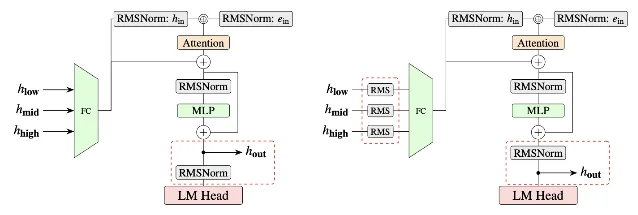
FC Normalization: an RMSNorm layer stabilizes the magnitude of inputs the draft model receives at each speculation step, preventing the runaway growth that caused instability.
Post-Norm Hidden-State Feedback: the draft model receives normalized (rather than raw) hidden states at each step, making it behave like a consistent recursive function rather than an increasingly noisy stacked transformer. 1
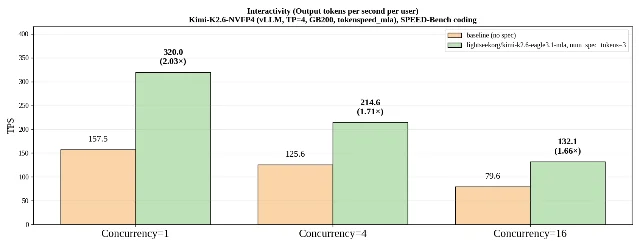
The result on long-context workloads: acceptance length up to 2× higher than EAGLE 3. On Kimi-K2.6-NVFP4 with vLLM on GB200 hardware, EAGLE 3.1 delivers 2.03× throughput at concurrency 1, 1.71× at C=4, and 1.66× at C=16 — measured on SPEED-Bench coding tasks. 1
The integration is a single PR already merged into vLLM main, shipping in v0.22.0, backward-compatible with existing EAGLE 3 checkpoints. A pretrained draft model for Kimi K2.6 —
lightseekorg/kimi-k2.6-eagle3.1-mla (3B, BF16) — is on HuggingFace. 4Gannotti's take:
Loading content card…
A complementary paper — Graft (Zhejiang University + Alibaba Qwen team, arXiv:2605.20104, May 19) — optimizes candidate tree construction rather than drafter quality: it prunes low-confidence branches and fills the freed budget via GPU-resident retrieval, no training required. On Qwen3-235B, it beats EAGLE-3 by 21.8% average; peak speedup hits 5.41×. 5 Graft uses EAGLE-3 as its base drafter, so EAGLE 3.1's reliability fix feeds directly into Graft's gains.
When to turn it on (and when not to)
The acceptance rate — the fraction of draft tokens the large model keeps — is the key variable. SyncSoft.AI's Danda Nguyen puts the break-even clearly: above 0.7 you get 1.3–2× net speedup; below 0.5 you're slower than vanilla. 6
Gannotti's practical framework: 2
- High ROI: single-user long-context inference (agents, code generation, document Q&A) — Shopify's SimGym validates this profile, where speculative decoding contributed ~6% throughput gain on structured JSON agent output on 48× B200 GPUs. 7
- Moderate ROI: concurrency 4–16 users — 1.66–1.71× speedup per EAGLE 3.1 benchmarks.
- Skip it: concurrency 16+; short prompts under 4K tokens; memory-constrained setups (the draft model takes 5–15% of the main model's VRAM).
One data point to sanity-check against: AI engineer Andrew Myers found a plain 8B draft-target setup beat EAGLE-3 by 2–3× on DGX Spark. 8 Acceptance rate, batch size, and model family alignment all have to match. Run a simple baseline first.
Three enterprise teams are already in production on vLLM speculative decoding (pre-EAGLE 3.1): Roblox (50% latency reduction, 4B tokens/week), LinkedIn (7% TPOT improvement across 50+ GenAI use cases), Amazon Rufus. 9
The one-line path to enabling it
If your team runs vLLM for self-hosted inference on an A100 or H100 cluster, the deployment command for EAGLE 3.1 with Kimi K2.6 is: 1
vllm serve nvidia/Kimi-K2.6-NVFP4 \
  --speculative-config '{"model":"lightseekorg/kimi-k2.6-eagle3.1-mla","method":"eagle3","num_speculative_tokens":3}'
The
method field stays eagle3 — fully backward-compatible. Add --enable-metrics to expose a Prometheus endpoint; monitor acceptance_rate in production to confirm the workload is compatible within minutes.Three PM actions for today:
- Check if your team self-hosts inference on vLLM. If you use managed API endpoints (OpenAI, Anthropic), this is the vendor's concern — but it's likely already running in their infrastructure without disclosure.
- Pick one long-context, lower-concurrency workload as the pilot (agent steps, code review, document Q&A). These match the profile where acceptance rates are highest.
- Wait for vLLM v0.22.0 (PR already merged to main) before treating this as production-stable, or track the PR directly if you want to move faster.
The benchmark data is from SPEED-Bench coding on GB200 hardware. Chat and multilingual workloads historically show lower acceptance rates — that uncertainty applies until you run A/B data on your own traffic. 10
Cover image: AI-generated illustration
References
- 1vLLM Blog: EAGLE 3.1
vllm.ai
- 2
- 3
- 4HuggingFace: lightseekorg/kimi-k2.6-eagle3.1-mla
huggingface.co
- 5
- 6SyncSoft.AI: Speculative Decoding in 2026
syncsoft.ai
- 7Shopify Engineering: SimGym
shopify.engineering
- 8Andrew Myers (LinkedIn)
linkedin.com
- 9
- 10LavX News: EAGLE 3.1 — trade-offs remain
news.lavx.hu

This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.