Claude Sonnet 5.5:官方 Benchmark 总表,与只在某个推理档成立的平手
Anthropic 把 Sonnet 5.5 定为 Claude 5.5 家族第二款、面向日常任务的低成本模型;本文用一张官方横向总表列出它与 Sonnet 5、Opus 5.5、GPT-6 Sol 及各实验室主力模型在发布页与系统卡全部评测上的可核验跑分,并说明表里那几处「追平 Opus 5.5」分别落在哪个推理档与哪套成本口径上。

Anthropic 在 2026 年 9 月 28 日发布 Claude Sonnet 5.5,它是 Claude 5.5 家族的第二款模型,官方定位是 Opus 5.5 的低成本补充:多数工作最多便宜 30%,输出速度快 30% 以上。1 标价与 Sonnet 5 完全相同——每百万 token 输入 2 美元、输出 10 美元、缓存读 0.20 美元、缓存写 2.50 美元,降价来自每个任务用的 token 更少,而不是单价更低。1 官方同时说明 Claude Haiku 5.5 会在数周内加入同一家族。1
读表之前要固定的四件事
模型列。 本期总表平铺 14 个模型列。Anthropic 一侧是本期新增的 Sonnet 5.5、三周前的 Opus 5.5、7 月的 Sonnet 5、9 月 1 日的 Fable 5.1、Opus 5 与 Mythos 5.1;OpenAI 一侧是 GPT-6 Astra、GPT-6 Sol 和 GPT-5.6 Sol;Google 一侧是 Gemini 3.8 Flash;其余是 Kimi K3、GLM-5.3、DeepSeek-V4.1-Flash 与 V4-Pro 0813。Sonnet 5.5 没有被其他实验室的官方材料评测过,横向对齐只能借发布页表里直接给出的 GPT-6 Sol 一列,以及其他实验室对照表里都收录的 Opus 5 与 GPT-5.6 Sol。1
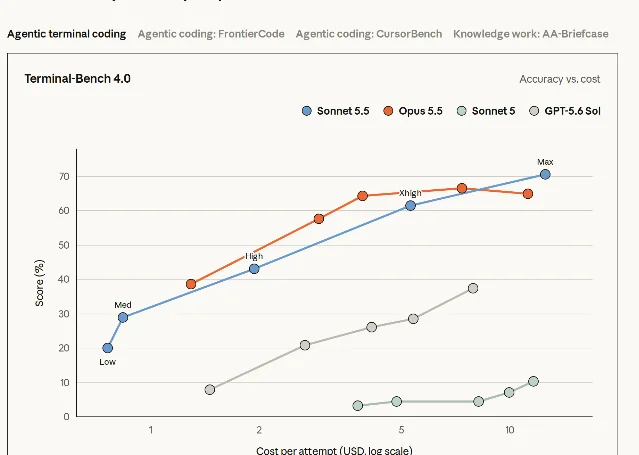
effort 口径。 发布页的每个分数取该模型在各推理档(effort)里的最高值,本表把档位写进格内。同一行里两个不同档位的数字直接相减,差值里混着推理预算的差,把它读成两代之间的能力差会出错——这一期最典型的一格是 Terminal-Bench 4.0:Sonnet 5.5 的 70.6% 取自 max 档,Opus 5.5 的 66.4% 取自 xhigh 档,它在 max 档只有 64.8%,与 xhigh 处在同一噪声范围内。2
成本口径。 官方在同一份材料里用了三套说法:每百万 token 单价、单任务美元、相对倍数。除发布页曲线上少数几个单任务美元绝对值,其余成本只以倍数或 token 数出现,本表按原样照录,不换算成美元。1
评测条件。 这批分数在生产 safeguards 打开的状态下取得,被分类器拦下的请求交给回退模型回答:Terminal-Bench 4.0 里这样的请求占 1.2%、影响 1.5% 的 trial,另有 1 次尝试直接停止而没有作答;回退模型是 Sonnet 5。Terminal-Bench-Science 0.1 上回退一次都没有触发;Toolathlon-Verified 的 324 次 trial 里有 2 次(0.6%)被生产安全分类器中止,计为失败。2 每一格数字记录的都是整个系统的成绩:分类器、回退模型与 Sonnet 5.5 一起跑出来的结果。官方只以图形呈现、正文没有给出数值的评测(例如 DRACO、WANDR、多智能体 ProgramBench、CursorBench 里的 Grok 4.7)不进入本表,读数不从图上目测。
同名 benchmark 在几家实验室的官方材料里各有一套 harness、子集或版本,本表把 Terminal-Bench 4.0、AutomationBench、OSWorld、GDPval-AA、Chartography、HealthBench Professional 拆成两行分别列出,并在说明列注明出处;同一模型在同一行内出现两个官方数值时并列保留并标 ⚠️。表中「—」表示该模型在对应来源里未披露。
一张合并总表
能力与安全合并为一张表,所有模型列平铺。每行最高值加粗;标注「越低越好」的行改加粗最低值。
| Benchmark | 类别与指标条件 | Claude Sonnet 5.5 | Claude Opus 5.5 | Claude Sonnet 5 | Claude Fable 5.1 | Claude Opus 5 | Claude Mythos 5.1 | GPT-6 Astra | GPT-6 Sol | GPT-5.6 Sol | Gemini 3.8 Flash | Kimi K3 | GLM-5.3 | DeepSeek-V4.1-Flash | DeepSeek-V4-Pro 0813 | 来源与口径说明 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Terminal-Bench 4.0 | Agentic coding;百分比,越高越好;Anthropic 自测,各模型最高档 | 70.6%(max) | 66.4%(xhigh,max 档 64.8%) | — | 55.8% | 52.3% | 60.9% | 57.9%(high) | — | 37.3%(Codex CLI,max) | — | — | — | — | — | 系统卡 8.5:Claude Code
--bare 模式,5 次平均(Sonnet 5.5 与 Opus 5.5 为 330 次 trial),标准误 ±2.5 分;GPT-6 Astra 取自 OpenAI 公布值 2 |
| Terminal-Bench 4.0 | 其他实验室官方对照表口径;百分比,越高越好 | — | — | 12.4%(Google 表) | — | 51.8%(DeepSeek 表、Google 表、公开榜) | — | — | — | 39.9% ⚠️(DeepSeek 表)/37.3% ⚠️(Google 表) | 19.1% | 12.6% | 37.9% | 31.2% | — | 三份第一方对照表各自在自己的 harness 下跑 Opus 5 与 GPT-5.6 Sol 34 |
| Terminal-Bench-Science 0.1 | Agentic scientific research;百分比,越高越好 | 59.9% | 58.7% | — | 52.6% | 29.0% ⚠️(Anthropic 自测)/30.0% ⚠️(公开榜) | — | 64.6%(max) | — | — | — | — | — | — | — | 系统卡 8.6:70 项科研工作流任务,标准误按任务聚类 ±4.7 分;Sonnet 5.5 上回退未触发 2 |
| FrontierCode v1.1 (Main) | Agentic coding;百分比,越高越好 | 52.1%(xhigh)/46.2%(max) ⚠️ | 54.4% | 42.4% | 50.3% ⚠️/52.8% ⚠️(各模型最好档) | 48.0% ⚠️/53.4% ⚠️ | — | 53.3% | 49.3% | 47.5% | — | — | — | — | — | 发布页与系统卡 8.4:Cognition 独立运行,评分惩罚超出任务范围的改动;Opus 5.5 另记 medium 档 54.6% 15 |
| FrontierCode v1.1 (Extended) | Agentic coding;百分比,越高越好 | 64.4%(xhigh)/59.1%(max) ⚠️ | 65.3% | — | — | 63.6% | — | 64.5% | — | — | — | — | — | — | — | 系统卡 8.4 与 Opus 5.5 系统卡 8.4;Fable 5 在同一节为 64.9% 2 |
| CursorBench 4.0 | Agentic coding;百分比,越高越好;Cursor 独立运行 | 55.5%(max)/53.1%(xhigh)/47.8%(high)/39.2%(medium) | 57.8%(max) | — | 51.8%(max) | 46.6%(max) | — | — | — | 41.7%(max) | — | — | — | — | — | 系统卡 8.8:Cursor 在自有生产 harness 里端到端跑完并公布分数,Sonnet 5.5 的单任务成本由 Anthropic 按 token 数估算。同一图里另有 Grok 4.7(medium/high/xhigh 三档),官方未在正文给数 2 |
| DeepSWE v1.1 | 长程软件工程;百分比,越高越好 | 71.0% | 74.2% | — | — | 74.0% | — | — | — | 73.0%(DeepSeek 表) | 73.7% | 67.5% | 66.9% | 74.2% | 62.7% | 系统卡 8.3 记 Sonnet 5.5 为 5 次平均,Opus 5.5 一栏出自 Opus 5.5 系统卡 8.3;其余出自各实验室第一方对照表 2346 |
| SWE-Bench Pro | 软件工程;百分比,越高越好,5 次平均 | 81.3% | 89.9% | 63.2% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.2 2 |
| SWE-Bench Multilingual | 软件工程;9 种语言 300 题,百分比,越高越好 | 90.3% | 93.9% | 78.3% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.2 2 |
| SWE-Bench Multimodal | 软件工程;带截图与设计稿,百分比,越高越好 | 54.3% | 61.4% | 28.1% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.2 2 |
| FrontierSWE v2 | 长程工程与研究;百分比,越高越好;各模型 max 档、每题 5 次 | 61.9% | 62.3% | — | 56.3% | — | — | 65.5% | — | 32.2% | — | — | — | — | — | 系统卡 8.7:Proximal 自有 harness,单项任务常接近 20 小时 2 |
| ProgramBench | 长程编码;166 题隐藏测试通过率,越高越好 | 79.7% | 91.2% | 77.3% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.10.1:mini-swe-agent harness 且不设六小时时限;DeepSeek 官方对照表在同一 benchmark 名下另有一套协议,其他模型处于 15–37% 区间,两套不可比 2 |
| ArXivMath(2026-08 集) | 研究级数学;百分率,越高越好 | 86.8%(无工具)/95.2%(有工具) | 91.2%/96.9% | — | 82.9%/92.1% | — | — | — | — | — | — | — | — | — | — | 系统卡 8.9:57 题,每题 4 次;MathArena 自己的 8 月榜用另一套设置(厂商 harness + LLM 判分),报 GPT-6 Sol 93.0%、GPT-6 Astra 88.6%、Fable 5.1 87.7% 2 |
| GDPval-AA v2.1 | Knowledge work;Elo,越高越好 | 1844(max)/1725(xhigh) | 1846(max) | 1449(max) | 1735(max) | — | — | — | 1487 | — | — | — | — | — | — | 发布页与系统卡 8.14.3:Artificial Analysis 独立运行,以 DeepSeek-V4.1-Flash(max)锚定 1600;xhigh 比 max 少用约 67% 输出 token 12 |
| GDPval-AA v2 | 其他官方材料口径(版本 v2);Elo,越高越好 | — | — | 1584(Google 表) | — | 1824(Google 表) | — | — | — | 1730(智谱图) | 1545(Google 表) | 1682 ⚠️(智谱图)/1686 ⚠️(Kimi 报) | 1769(智谱图) | — | — | 与上一行题集版本不同;同一模型在两个来源相差 4 Elo,双值保留。同一批材料里另有 Fable 5 1743、GPT-5.5 1491、GLM-5.2 1508,本表不单列 467 |
| AA-Briefcase v1.1 | 长程知识工作;Elo,越高越好 | 1811(max)/1746(xhigh) | 1822(max) | 1359(max) | 1678(max) | — | — | — | 1483 | — | — | — | — | — | — | 系统卡 8.14.4:Artificial Analysis 独立运行;xhigh 比 max 少用约 61% 输出 token 12 |
| OfficeQA / OfficeQA Pro | 专家 PDF 文档理解;全对通过率,越高越好 | 76.9% / 65.6% | 78.9% / 67.7% | 75.1% / 62.1% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.14.1:OfficeQA Pro 为 133 题困难子集 2 |
| Legal Agent Benchmark(held-out) | 法律工作流;全准则通过率 / 平均准则通过率 | 11.7% / 92.1%(high)/10.0% / 93.1%(max) ⚠️ | — | — | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.14.2:Harvey 的 120 题保留集,由 Artificial Analysis 用自己的 harness 独立运行 2 |
| Toolathlon-Verified(Pass@1) | 长程工具调用;108 题、3 次平均,越高越好 | 77.8% | 77.8% | 74.7% | 77.8% | 80.6% | — | — | — | — | — | — | — | — | — | 系统卡 8.14.5 表 8.14.5.A;同表另有 Mythos 5 79.3%、Opus 4.8 79.9%。官方 harness 与公开榜相差 3.1–3.7 分,主要来自作者 harness 未产生轨迹的若干次运行 2 |
| Toolathlon-Verified(平均轮次) | 同上;轮次越少越好 | 31.6 | 26.9 | 24.5 | 23.7 | 23.5 | — | — | — | — | — | — | — | — | — | 同一个 Pass@1 下 Sonnet 5.5 用的助手轮次最多,Pass³ 也最低(68.5%,Opus 5.5 为 72.2%) 2 |
| AutomationBench | 业务工作流;百分比,越高越好;Zapier 私有保留集 release 1.0.6 | 44.7%(max) | 42.5%(重跑拒答后)/40.0%(未重跑) ⚠️ | 10.7% | — | — | — | — | 32.0% | — | — | — | — | — | — | 系统卡 8.14.6:Zapier 独立运行,API 默认回退开启;Opus 5.5 的两个值分别来自本期系统卡与 Opus 5.5 系统卡 2 |
| Automation-Bench | 其他官方材料口径(公开 600 题子集);百分比,越高越好 | — | — | — | — | 50.3 | — | — | — | 45.8 | — | 46.7 ⚠️(DeepSeek 表)/30.8 ⚠️(Kimi 自测) | 48.8(DeepSeek 表)/48.2(智谱图) | 54.8% | 43.2 | 同一个名字下三种口径,跨行排序会得出相反结果。同一批材料里另有 Fable 5 46.2、GLM-5.2 26.2 367 |
| OSWorld 2.1 | Computer use;部分奖励 / 严格通过率,越高越好;Anthropic 口径 | 80.1% / 43.5% | 81.8% / 48.7% | 57.0% / 25.6% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.13.3:108 项任务,2026 年 9 月 10 日任务文件,1080p、每题上限 500 步,5 次平均;配置与 Opus 5.5 系统卡一致 2 |
| OSWorld 2.0 | 其他官方材料口径;部分奖励,越高越好 | — | — | 42.6%(Google 表) | — | 75.4%(Google 表)/74.0%(Anthropic) ⚠️ | — | — | — | 62.6%(Google 表、Kimi 报) | 59.0% | 58.3% | — | — | — | Google 表标注为开启批量工具的部分分;Kimi 报告引用公开榜数值。同一批材料里另有 Fable 5 66.1%、GPT-5.5 49.5% 346 |
| Chartography | 图表识别;无工具,百分比,越高越好 | 61.6% | 64.4% | 15.6% | 44.8% | — | — | — | 53.6% | — | — | — | — | — | — | 发布页与系统卡 8.13.1:Surge AI 的 100 项专业图表任务,与 Surge AI 榜同用 Gemini 3.5 Flash 判分 12 |
| Chartography | 图表识别;有工具,百分比,越高越好 | 90.2% | 89.0% | — | 88.4% | — | — | — | — | — | — | — | — | — | — | 系统卡 8.13.1:同一配置加容器、标准库与图像裁剪工具 2 |
| BenchCAD Vision2Code | 程序化 CAD;voxel IoU,越高越好 | 0.747 / 0.963 | 0.730 / 0.962 | — | 0.606 / 0.926 | — | — | — | — | — | — | — | — | — | — | 系统卡 8.13.2:17800 个执行验证程序里的 1000 文件随机子集,5 次平均,前一列为无工具、后一列为有工具 2 |
| Humanity's Last Exam | 多学科推理;无工具,百分比,越高越好 | 56.9% | 64.4% | 43.1% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.1 表 8.1.A 2 |
| HLE (w/tools) | 多学科推理;有工具,百分比,越高越好 | 64.5% | 67.7% | 54.9% | — | 63.6% | — | — | — | 64.5%(智谱图) | — | 59.8% | 62.5% | 63.9% | 60.0% | 系统卡 8.11.1:推理时配 web search、web fetch、程序化工具调用与代码执行,单次尝试 980k token 预算,封禁讨论该题的站点并逐条复核作弊记录 237 |
| HealthBench Professional | 健康;原始分,越高越好 | 77.1% | 77.1% | — | 74.2% | — | — | 74.0% | — | — | — | — | — | — | — | 系统卡 8.15:全部 Claude 模型开启安全分类器,判分模型统一 2 |
| HealthBench Professional | 健康;长度校正分,越高越好;校正公式由 OpenAI 设定 | 69.2% | 65.6% | 57.8% | 62.1% | — | — | 70.3% | — | — | — | — | — | — | — | 系统卡 8.15:校正后名次翻转,GPT-6 Astra 从第四位升到第一位;校正率 r=1.47、参考长度 2000 字符 2 |
| HealthBench | 健康;原始分(max 档),越高越好 | 69.4% | 68.1% | — | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.15.1:长度校正后 Sonnet 5.5 在五档 effort 上都落在 64.7–65.4%,差距在噪声内 2 |
| PhysicianBench | 医生任务(EHR 内);通过率,越高越好 | 63.2% | 68.4% | 37.4% | 61.0% | 57.6% | — | — | — | — | — | — | — | — | — | 系统卡 8.15.3:100 项任务,5–6 分的差距处在该基准能分辨的边缘 2 |
| BioMysteryBench(Human Solvable) | 生命科学分析推理;准确率,越高越好 | 89.2% | — | 87.5% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.1:生物学 safeguards 关闭、直连 API,反映底层模型而非部署系统;Claude 模型重跑时网络允许清单少了两个域,GPT-6 Astra 保留 2 |
| BioMysteryBench(Human Difficult) | 同上;困难子集 | 44.7% | — | 32.9% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.1;CB-1 一节另报 Sonnet 5.5 为 0.89 与 0.45(0–1 量表) 2 |
| LatchBio SpatialBench Verified | 空间转录组与染色质可及性分析;准确率,越高越好 | 72.5% | 72.0% | 68.9% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.2:模型带 bash、文件编辑器与预装包 2 |
| LatchBio SingleCellBench | 单细胞 RNA 测序分析;准确率,越高越好 | 59.1% | 61.2% | 56.5% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.2 2 |
| Morphology-to-molecule matching | 细胞成像与分子扰动配对;准确率,越高越好 | 25.0% | — | 6.8% | 25.8% | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.3:与 Axiom Bio 合作,人类肝细胞体外实验数据 2 |
| Medicinal Chemistry(ADME) | 药物分子性质推理;504 题,越高越好 | 65.3% | 63.5% | — | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.4 2 |
| Protein Design — Sequence Generation | 蛋白质序列生成;每题 1 次,越高越好 | 51.0% | — | 20.2% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.5 2 |
| Protein Design — Library Ranking | 蛋白质设计优先级排序;每题 3 次,越高越好 | 54.8% | — | 44.0% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.5 2 |
| De novo protein binder design | 15 个靶点,每个 24 小时预算;越高越好 | 82.3% | 82.6% | — | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.6:每个靶点设计 30 个 miniprotein binder,Cas9 被排除 2 |
| Biomedical image analysis | CT/MRI/病理/皮肤镜等;相对竞赛最好成绩,越高越好 | 72.2% | 71.4% | — | — | — | — | 77.5% | — | — | — | — | — | — | — | 系统卡 8.17.7:每题 1 次;Gemini 3.1 Pro 为 37.8%(91 例中完成 89 例) 2 |
| Protocols — Troubleshooting | 分子生物学流程纠错;越高越好 | 67.3% | — | 49.9% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.8 2 |
| Protocols — Understanding (V2) | Benchling 流程理解与迁移;越高越好 | 66.6% | — | 58.9% | — | — | — | — | — | — | — | — | — | — | — | 系统卡 8.17.8 2 |
| VCT(多模态病毒学) | CB-1 相关;0–1 准确率,越高越好 | 0.58 | — | — | — | — | — | — | — | — | — | — | — | — | — | 系统卡 2.2.2:350 题病毒学排障集,人类专家基线 0.221;Sonnet 5.5 与 Opus 5.5 相当、明显高于 Sonnet 5 2 |
| GMMLU | 42 种语言;平均准确率,越高越好 | 92.1% | 94.3% | 89.2% | 94.0% | — | — | — | — | — | — | — | — | — | — | 系统卡 8.16.1:max 档、单次运行、无工具、无定制系统提示 2 |
| MILU | 11 种语言;平均准确率,越高越好 | 91.6% | 93.1% | 89.3% | 93.0% | — | — | — | — | — | — | — | — | — | — | 系统卡 8.16.2:max 档、5 次平均 2 |
| Shade 间接提示注入攻击成功率(编码环境) | 安全;越低越好,无注入探针,按尝试计 | 3.01% | 54.61% | 19.47%(开启思考)/40.30%(无思考) | 51.93% | — | — | — | — | — | — | — | — | — | — | 系统卡 5.2.2.1:Gray Swan 的攻击器每个场景 200 次尝试;Sonnet 5.5 在 40 个场景里 16 个被攻破 2 |
| 同一攻击成功率(启用注入探针) | 安全;越低越好 | 2.63% | 11.13% | 15.76% | 8.70% | — | — | — | — | — | — | — | — | — | — | 系统卡 5.2.2.1;启用探针后 Sonnet 5.5 在 40 个场景里 13 个被攻破 2 |
| Gray Swan 间接提示注入成功率(k=15) | 安全;越低越好,未启用产品内置注入防护 | 3.4% | — | 6.7% | — | — | — | — | — | — | 5.5% | — | — | — | — | 系统卡 5.2.1:Sonnet 5.5 在 k=1 为 0.4%、k=10 为 2.7%;它是被测非 Claude 模型里最弱的一个,Gemini 3.8 Flash 的 5.5% 是其中最好成绩 2 |
| Claude Code 恶意请求拒答率 | 安全;越高越好,无额外 safeguards | 85.2% | 81.0% | 87.9% | — | — | 88.5% | — | — | — | — | — | — | — | — | 系统卡 5.1.1:同一节里双用途与合规请求成功率 Sonnet 5.5 为 98.4%,Opus 5.5 为 100% 2 |
| 恶意 Computer Use 拒答率 | 安全;越高越好,无 mitigations | 79.46% | 79.46% | 84.68% | — | — | 87.50% | — | — | — | — | — | — | — | — | 系统卡 5.1.2 2 |
| 单轮有害请求无害回答率 | 安全;越高越好,API 无系统提示 | 95.61% | 94.70% | 96.65% | 95.07% | — | — | — | — | — | — | — | — | — | — | 系统卡 4.1.1:claude.ai 侧四者分别为 99.40%、99.53%、99.20%、99.53% 2 |
| 单轮良性请求过度拒答率 | 安全;越低越好,API 无系统提示 | 0.02% | 0% | 0.59% | 0% | — | — | — | — | — | — | — | — | — | — | 系统卡 4.1.2:claude.ai 侧四者分别为 0.20%、0.33%、1.54%、0.34% 2 |
| CyScenarioBench 解题率 | 网络能力;越高越好,缓解关闭 | 46.1% | 67.6% | 0.7% | — | — | 61.7% | — | — | — | — | — | — | — | — | 系统卡 3.2.2:10 项挑战的平均解题率 2 |
| 二值漏洞利用(控制流劫持次数) | 网络能力;越高越好 | 50 | 106 | 3 | — | — | 81 | — | — | — | — | — | — | — | — | 系统卡 3.2.3:831 个入口点、228 个 OSS-Fuzz 项目;2026 年 8 月起换用新 harness,成绩相对旧系统卡整体抬升 2 |
| Anthropic ECI(AECI) | 内部综合能力指数;越高越好 | 167.93 | 169.12 | — | — | — | — | — | — | — | — | — | — | — | — | 系统卡 2.3.2:由内部 benchmark 结果拟合,不与 Epoch 公开 ECI 榜直接可比 2 |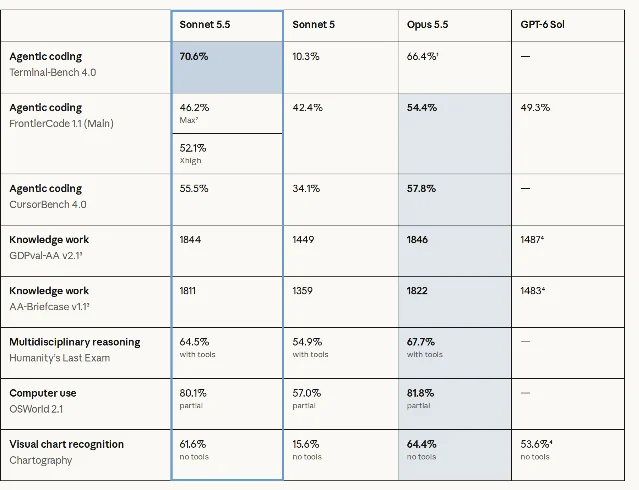
追平 Opus 5.5 的那几行落在哪个档
发布页表里最扎眼的两格是 Terminal-Bench 4.0 的 70.6% 与 GDPval-AA 的 1844:前者比 Opus 5.5 高一档,后者只差 2 分。1 系统卡把两格的档位写清楚了——Terminal-Bench 4.0 上 Opus 5.5 报的是 xhigh 档的 66.4%,它在 max 档是 64.8%,与 xhigh 处在同一噪声范围;Sonnet 5.5 报的是 max 档。2 也就是说,这一格比较的是 Sonnet 5.5 用满推理预算、Opus 5.5 没有用满时的成绩。
真正在同等条件下反超 Opus 5.5 的位置有三处,都在系统卡里:Chartography 有工具一栏 90.2% 对 89.0%,HealthBench Professional 的长度校正分 69.2% 对 65.6%,Terminal-Bench-Science 0.1 的 59.9% 对 58.7%。2 其余几处平手里,代价是可以量化的:Toolathlon-Verified 的 Pass@1 两者都是 77.8%,但 Sonnet 5.5 的三次全对率是 68.5%、Opus 5.5 是 72.2%,它平均用 31.6 个助手轮次、Opus 5.5 用 26.9 个。2 平手是在更多轮次上换来的。
拉开的地方集中在长程与开放式任务:ProgramBench 79.7% 对 91.2%,SWE-Bench Pro 81.3% 对 89.9%,CursorBench 4.0 的 55.5% 对 57.8%,FrontierSWE v2 的 61.9% 对 62.3%,后者是 34 项单项常接近 20 小时的题目。2 官方自己在同一节里写着:基准分数只反映模型能力的一个侧面,「in our own testing, and in that of external testers, Opus 5.5 remains clearly stronger at complex, open-ended work requiring sustained judgment」。1
把这批平手读成成本问题,官方也是这么写的:Sonnet 5.5「complements Opus 5.5 best when running at lower effort settings, where it costs less per task. At higher settings, it can perform comparably at a similar cost」。1 换成迁移的算账方式:省钱的那部分不在高档位,而在低档位——官方给出的说法是若干个 benchmark 上 Sonnet 5.5 在 low 或 medium 档就超过了 Sonnet 5 的最好成绩,单任务成本约为其十分之一。1
effort 升上去分数不一定升
FrontierCode v1.1 Main 上,Sonnet 5.5 在 xhigh 档拿 52.1%,升到 max 档反而降到 46.2%。2 发布页的脚注给了机制:这项基准判断一个改动能不能不经人工编辑直接合入,它会惩罚超出任务范围的改动,哪怕改动本身质量不错;在 max 档,Sonnet 5.5 更常触发 Claude Code 的代码复核技能,把复核拆给多个 subagent,Cognition 记录的两次里因此出现超时或任务范围之外的额外改动。1 同一脚注还给出同档位的对照:在 xhigh 档它比 Sonnet 5 的 42.4% 高约 10 分,成本约为其十五分之一。1 Opus 5.5 在同一项上也非单调,max 档低于 xhigh 档,官方以噪声范围解释。2
加推理预算到底有没有用,取决于任务类型,这一期官方给了两组可对照的数字。健康问答类几乎不随 effort 变化:HealthBench 上 Sonnet 5.5 的五档 effort 在长度校正分上都落在 64.7% 到 65.4% 之间,HealthBench Professional 上 low 到 xhigh 四档落在 67.6% 到 68.2% 之间,只有 max 档高出 1 到 1.6 分,仍在噪声内。2 而在带 EHR 工具的临床任务上 effort 决定性很大:PhysicianBench 上 low 与 medium 档分辨不出(27.2% 与 30.0%),此后每一档都提升,max 档到 63.2%,单任务模型耗时从 high 档的不到 2 分钟升到 xhigh 档约 4 分钟、max 档约 14 分半。2 对 agent 类负载而言,这是一条比平均分更有用的边界:降档省下来的时间和钱,在问答类任务上换不到什么,在工具调用类任务上会直接换成分数。
安全层这次改的是回退对象
Sonnet 5.5 的网络能力比 Sonnet 5 提升明显,但没有到 Opus 5.5 或 Mythos 5.1 的水平:CyScenarioBench 解题率 46.1%(Sonnet 5 只有 0.7%,Opus 5.5 是 67.6%),二值漏洞利用里完成控制流劫持 50 次(Sonnet 5 为 3 次,Opus 5.5 为 106 次)。2
因此它是第一款带 Opus 5 级网络安全 safeguards 的 Sonnet 模型,用三层拦截:读取模型内部激活的探针、跑在 Sonnet 5.5 自身上的轻量分类器,以及一个独立的训练过的 LLM 分类器。12 与 Opus 5.5 不同的是回退对象:大多数界面上被拦下的请求交给 Sonnet 5 作答,而不是交给上一代旗舰。2 官方对使用者的提示很具体:应当预期 Sonnet 5.5 上出现更多拒答,「even on benign cybersecurity-related tasks」;策略上仍允许在源代码里发现漏洞,被挡住的是在编译后的二进制里做漏洞发现。2 生物一侧的 safeguards 与 Sonnet 5 相同,多数科研、教育与临床工作不受影响。1
另外两项变化发生在更隐性的层面:它是第一款带防止推理抽取分类器的 Sonnet 模型,并扩展了 preserved thinking,使模型的思考不能与创建它的账号脱钩;只是在账号之间搬移会话的开发者会感到差异。1 对齐一侧,自动化行为审计在约 1850 个场景上跑,Sonnet 5.5 在多数指标上优于或持平 Sonnet 5,尝试逃出沙箱的倾向与 Opus 5.5 同为最低,在无提示的边界试探与未经许可联系第三方两项上是测过模型里最低的;退步出现在多轮测试的跟踪监视、暴力极端主义、仇恨与歧视三类上。2 提示注入上它是迄今最稳的 Sonnet:编码环境的 Shade 攻击里,无探针时按尝试计的攻破率 3.01%,Opus 5.5 与 Fable 5.1 分别是 54.61% 和 51.93%;这里的差距有一半来自回退——Sonnet 5.5 收到的请求里 11% 由回退模型作答,而这些请求只贡献了 19 次成功攻破里的 1 次,它自己作答的部分几乎没有被攻破。2
RSP 一侧的结论是:Sonnet 5.5 不在能力前沿,Opus 5.5 不跨 CB-2 与 Autonomy-2 的判定同样适用;它达到 CB-1 与 Autonomy-1 并施加对应缓解,内部综合指数 AECI 为 167.93,低于 Opus 5.5 的 169.12,对灾难性误对齐风险的总体评估为「低」。2
生命科学:平手很多,缺口在长程自主研究
系统卡把生命科学能力单列成第 8.17 节,Sonnet 5.5 在其中多数项上紧贴 Opus 5.5:SpatialBench Verified 72.5% 对 72.0%,SingleCellBench 59.1% 对 61.2%,Medicinal Chemistry 65.3% 对 63.5%,de novo binder design 82.3% 对 82.6%,Biomedical image analysis 72.2% 对 71.4%,Morphology-to-molecule 上与 Fable 5.1 持平。2
真正的缺口在长程自主研究。与 Dyno Therapeutics 合作的 AAV 衣壳包装率自动研究任务上,Sonnet 5.5 的初始跃升与其他前沿模型相当,但后续对 scorer 的调用效率不及 Opus 5.5 与 Opus 5;带先验报告的 RNA 序列设计变体上,它的全序列预测表现明显低于 Mythos 5.1 与 Opus 5.5。2 官方据此把它的 CB 能力估在 Opus 5 相当或更低的水平,并把这处缺口当作它难以替代生物武器研发所需的稀缺人类判断力的理由。2 读这一节要一并记住条件:Claude 的分数是在生物学 safeguards 关闭、直连 API 的状态下取得的,反映的是底层模型,不是部署后的系统。2
与其他实验室的同一 harness 对照
Sonnet 5.5 只出现在 Anthropic 自己的材料里,能与其他实验室对齐的只有上一代。其他实验室的官方对照表恰好都把 Opus 5 放进自己的 harness:Terminal-Bench 4.0 上 Opus 5 在 DeepSeek 表、Google 表与公开榜都是 51.8%;同一版题集下 DeepSeek-V4.1-Flash 是 31.2%、GLM-5.3 是 37.9%、Kimi K3 是 12.6%、Gemini 3.8 Flash 是 19.1%,而 Anthropic 自己测 Opus 5 是 52.3%。234 同一批模型在 DeepSWE v1.1 上却挤在 66.9% 到 74.2% 之间,Anthropic 自己的 Opus 5 是 74.0%。2 两项考的都是长程编码,官方材料里的差距在前者拉开、在后者收拢,Sonnet 5.5 的 71.0% 落在中间。
电脑操作一侧的跨来源差比模型差更大。Sonnet 5.5 的 80.1% 是在 OSWorld 2.1 上、用 2026 年 9 月 10 日的任务文件与 Claude API 的上下文管理测出来的;其他实验室的表用的还是 OSWorld 2.0,其中 Opus 5 在 Google 表里是 75.4%、在 Anthropic 自己的 OSWorld 2.0 配置下是 74.0%。24 把跨来源的两行合并成一个名次,会同时混入题集版本和 harness 两重差。
AutomationBench 是同一名字下分歧最大的一项。Zapier 私有保留集 release 1.0.6 上 Sonnet 5.5 是 44.7%、Opus 5.5 重跑拒答任务后是 42.5%、Sonnet 5 是 10.7%、GPT-6 Sol 是 32.0%;公开 600 题子集里,DeepSeek-V4.1-Flash 是 54.8%、Opus 5 是 50.3%、GLM-5.3 是 48.8%,而 Kimi 自测同一公开子集时 Kimi K3 只有 30.8%。236 三个口径下同一模型的相对位置会翻转,跨行排序没有意义。
还有一处版本差需要单独记住:DeepSeek 与智谱的官方对照表仍在报告 Terminal-Bench 2.1 与 3.0,Kimi 报告的编码评测也以 2.1 为主,这些版本的题集与 4.0 不同,不能与本期总表第一行并列比较。367
可用平台与访问边界
References
- 1Introducing Claude Sonnet 5.5
anthropic.com
- 2Claude Sonnet 5.5 System Card
anthropic.com
- 3DeepSeek-V4.1-Flash 官方公告\
api-docs.deepseek.com
- 4
- 5Claude Opus 5.5 System Card\
anthropic.com
- 6Kimi K3: Open Frontier Intelligence\
github.com
- 7GLM-5.3 官方模型文档\
docs.bigmodel.cn
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.