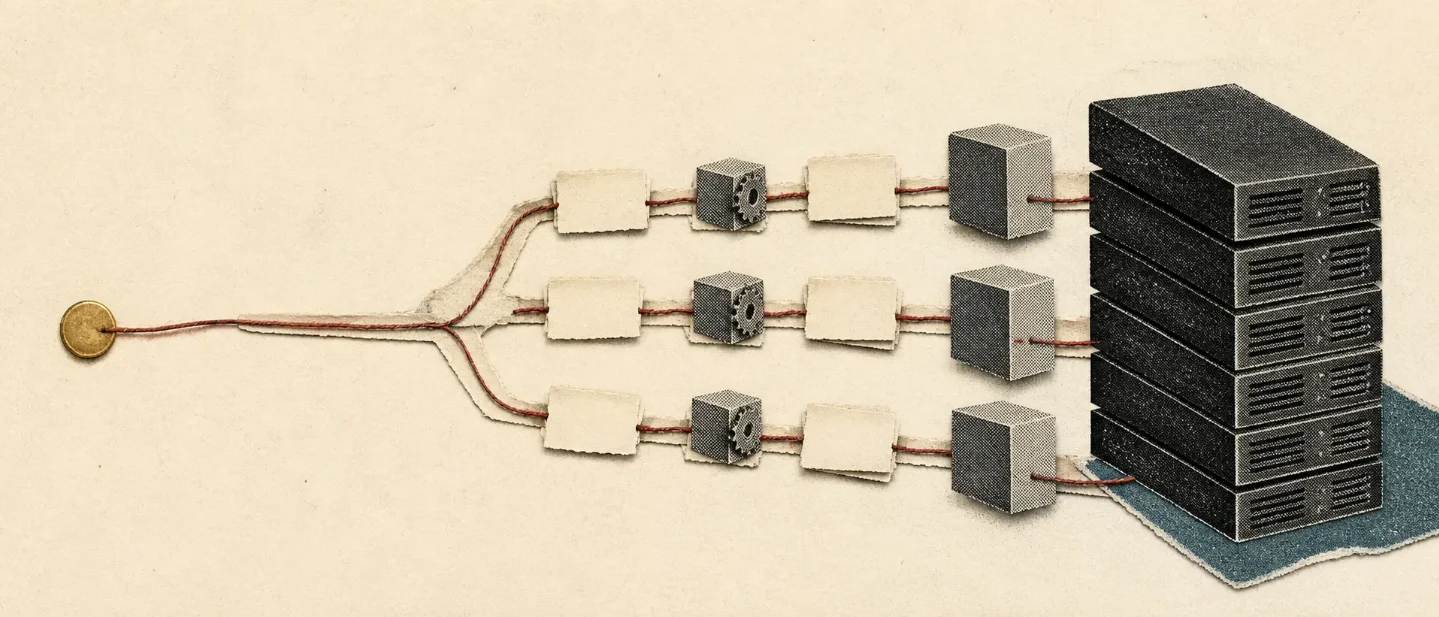
Cheaper AI tokens, costlier workflows
As model prices fall, agentic workflows can still raise the cost of each completed task; the useful unit to budget is the whole workflow, including tools, review, and recovery.
A team sees the price of a million model tokens fall and expects its AI budget to fall with it. Then an agent starts searching, checking, calling tools, retrying, and handing work to a stronger model. The bill grows.
The practical question is simple: what does one completed AI task cost?
Gartner's answer points to an uncomfortable shift. The research firm forecasts that AI inference costs per agentic workflow will increase by more than fivefold through 2028. Gartner defines the pressure through three linked changes: model economics are improving, cheaper unit costs make stronger models easier to deploy, and sophisticated workflows consume far more tokens than simple chatbot interactions. 1
The forecast concerns a workflow, rather than every model call. That distinction changes how teams should budget AI.
Falling unit prices can buy more expensive behavior
Inference is the model work used to produce an answer or take an action. A basic chatbot may read a request and return a response. An agentic workflow can break a task into steps, call a search or database, inspect the result, revise its plan, and ask another model to check the work.
Each step can be useful. Each step can also add input tokens, output tokens, tool calls, latency, and a chance of retry. Gartner says that routing a task to an agentic reasoning model costs providers at least five times as much as a basic chatbot interaction, with the gap growing as the task becomes more complex. 1
Lower token prices make this expansion easier to justify. A team can spend the saving on a longer context, a stronger reasoning model, more verification passes, or a new tool. The price of each ingredient falls while the recipe acquires more ingredients.
That is the inference paradox: better unit economics can raise the total cost of a more capable product. The business question moves from "What is the model price?" to "How many model and tool actions produce one result that someone accepts?"
The bill follows the chain
A useful budget separates four lines:
- model input and output across every step;
- tools, searches, storage, and runtime sessions;
- human review of the result;
- retries, corrections, and recovery after a failed run.
The first line is the easiest to see. OpenAI's current API pricing page lists separate rates for input tokens, cached input, cache writes, and output tokens. The same page lists charges for web search, file search, and hosted shell or code-interpreter sessions. 2 Anthropic's API pricing page likewise lists token rates alongside managed-agent runtime hours, web search, and code execution. 3
Caching can lower the cost of sending the same context again. A cache still leaves output generation, tool use, and runtime sessions in the calculation. A cheaper model can reduce the cost of one step while a longer chain adds several more steps.
Consider a document-review agent. The first model call reads the request. A second call retrieves relevant documents. A third call compares passages. A fourth call writes a draft. A fifth call checks citations. A human then fixes two errors and reruns the check.
The cost of the accepted review includes every call, every tool request, the human's time, and the rerun. The first draft is only an intermediate object. A spreadsheet that counts only the first model call will call the workflow cheap because it has priced the wrong thing.
What the fivefold forecast changes
Gartner's forecast gives product leaders a planning warning with a specific scope: the cost of an agentic workflow through 2028. Simple requests may become cheaper, routing may reduce waste, and some workflows may create enough value to justify higher inference costs.
The useful comparison is cost per accepted outcome. A team can calculate it with a simple formula:
cost per accepted outcome = model and tool charges + review time + recovery cost, divided by completed outcomes
The denominator matters. A workflow that produces ten drafts but yields six usable results has six outcomes for this calculation. A workflow that completes a task only after an expert repairs it has included the expert's repair in the numerator.
This measure also changes what "automation" means. A workflow can create value through better quality, faster response, or higher capacity. A workflow earns a cost-saving claim only when the all-in cost of the accepted result falls against a credible alternative.
The deployment test
Before a team expands an agentic pilot, the team should answer five questions with observed numbers from a real task set:
- What counts as one completed outcome? Name the result a customer, colleague, or downstream system can use without hidden reconstruction.
- How many model and tool steps produce that outcome? Count normal steps, verification passes, retries, and the long tail of difficult cases.
- Which steps need the expensive model? Route classification, retrieval, formatting, and deterministic checks to cheaper models or ordinary software when those tools can meet the requirement.
- What does a failed run cost? Include human review, correction, rerun, delay, and any action that must be reversed.
- What alternative does the workflow beat? Compare the accepted result with the current human process, a simpler model, or a narrower automation. Use the same quality standard for both sides.
A team that lacks answers to the first four questions has a measurement problem. A team with those answers still needs to compare the workflow with a credible alternative. The workflow may buy speed or quality; when its all-in cost remains higher, it belongs in a speed or quality case rather than a cost-saving case.
Cheaper tokens are useful. They create room to improve a workflow, while the workflow's economics still depend on every step that produces the result. The right unit for the next AI budget is the accepted outcome, priced across the whole chain.
References
- 1
- 2OpenAI API pricing
platform.openai.com
- 3Anthropic API pricing
anthropic.com
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.