Your GPU dashboard is lying to you
Production LLM teams are paying for GPU capacity running at 16% memory bandwidth utilization while dashboards report 90% GPU utilization — the wrong metric entirely. This brief explains disaggregated inference (splitting prefill and decode onto separate GPU pools), documents the 2026 shift to production standard (llm-d/CNCF, Baseten, Databricks), covers the emerging Attention-FFN Disaggregation layer for MoE models, and closes with three concrete PM actions.

Your infrastructure team reports 90% GPU utilization. Costs are still rising. Latency is still spiking. The dashboard is technically accurate and architecturally useless at the same time.
Here's why: in a typical production LLM deployment, memory bandwidth utilization sits at 16% — even when the compute dashboard shows a healthy number. 1 GPU utilization tracks FLOP throughput. LLM inference, specifically the decode phase, is bottlenecked by how fast you can move model weights through memory — not by how many FLOPs you can execute. Those two metrics measure different things, and the one that actually determines your cost-per-token is the one most teams aren't watching.
The fix has a name: disaggregated inference. It crossed from academic paper to production infrastructure standard in 2026. If your team is negotiating an AI serving contract, choosing an inference provider, or writing latency requirements for a product spec, this shift matters to you.
What disaggregation actually means
Every LLM inference request has two distinct phases:
Prefill processes your entire prompt in parallel. It's compute-bound — arithmetic intensity of 200–400 operations per byte — and it produces the initial KV cache. 2 This is where TTFT (time to first token) is born.
Decode generates your output one token at a time by reading the KV cache over and over. It's memory-bandwidth-bound — arithmetic intensity drops to 60–80 operations per byte, GPU utilization falls to 20–40%. 2 This is where TPOT (time per output token) lives.
Colocating both phases on the same GPU forces a compromise: neither phase gets hardware optimized for its actual bottleneck. Disaggregation separates them into independent GPU pools, each tuned for its workload.
The architecture has evolved into three distinct levels:
| Level | What gets separated | Primary win | Representative tooling |
|---|---|---|---|
| Prefill-Decode (PD) | Prefill and decode onto separate GPU pools | 2–4× throughput, lower TTFT P99 | vLLM PDD, SGLang EPD, NVIDIA Dynamo |
| Dynamic PD (DOPD) | P/D ratio adjusts in real time with ARIMA load prediction | SLO attainment 80.8% → 99.4%, P90 TTFT −67.5% | DOPD (arXiv:2511.20982) 3 |
| Attention-FFN (AFD) | Attention operators and MoE-FFN operators onto different GPU groups | Required for sub-150ms TTFT SLOs on large MoE models | AIC++ / vLLM AFD prototype (arXiv:2605.28302) 4 |
The DistServe paper (OSDI 2024, referenced in WEKA's guide) demonstrated that disaggregated serving delivers 7.4× more requests served, or 12.6× tighter SLO adherence, compared to co-located serving at equivalent hardware counts. 2 Meta's results at MLSys 2026 showed 15–25% TCO improvement from running prefill and decode on different accelerator types. 5
The production tipping point
This is no longer early-adopter territory. Several markers from the past 60 days confirm a category shift:
Loading stats card…
- Baseten ships Kimi K2.6 in production with PD disaggregation listed as a standard feature alongside NVFP4 weights (NVIDIA Blackwell GPU native precision format) and KV-aware routing — not experimental, not an option, just part of the stack. 7
- Databricks saves >80% GPU costs vs. static peak provisioning using model-unit-based autoscaling on disaggregated infrastructure, serving 125 trillion tokens per month for customers including Superhuman and Fox Sports. 8
- Xiaomi MiMo-V2.5 deployed EPD (Encode-Prefill-Decode) disaggregation in production, which doubled encoder throughput and achieved server-side KV cache hit rates averaging 93% through Hybrid Sliding Window Attention that compresses KV cache to 1/7 the size of full attention. 9
- AMD, Red Hat, and Oracle published a repeatable benchmark methodology for PD disaggregation on MI300X GPUs: disaggregated configurations in the 15–41 tok/s/user range consistently delivered 10–38% higher throughput per GPU versus aggregated deployments; a 2-node disaggregated setup outperformed a 3-node aggregated setup at high request rates. 10
NVIDIA summed it up bluntly at MLSys 2026: prefill-decode disaggregation is "real and valuable," but only if rate matching, KV transfer, cache routing, and elastic scaling are solved simultaneously. 5 That qualifier is where the engineering complexity lives — and why managed serving layers matter.
Loading content card…
AFD: the next layer (relevant for MoE model users)
If your product runs on a Mixture-of-Experts model — DeepSeek, Qwen3-235B, GPT-4 class models — pay attention to what's coming after PD disaggregation.
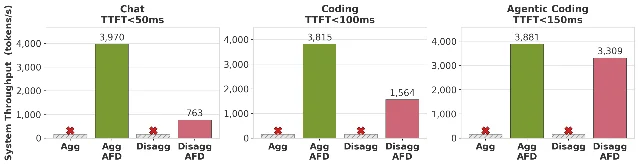
A new paper from Georgia Tech, Intel, and Google (arXiv:2605.28302, May 27) introduces Attention-FFN Disaggregation (AFD): splitting the attention operators (memory-bound) and the MoE-FFN operators (compute-bound) onto separate GPU groups. 4 The paper tested four frontier MoE models on 128 NVIDIA B200 GPUs.
The key result: under strict SLO targets (TTFT below 50ms for chat, 100ms for coding, 150ms for agentic workflows; TPOT below 15ms), AFD was the only configuration that kept DeepSeek-V3.2 operational at ~4,000 tokens/second system throughput. Non-AFD deployments hit the SLO wall and became infeasible. 4
The memory benefit is concrete: a 1M-token prefix workload requires ~298 GiB per GPU under standard deployment — exceeding the B200's 180 GiB capacity. AFD splits model weights across GPU groups, reducing the effective per-GPU requirement to ~165 GiB and making the deployment viable. 4
AFD is not production-ready yet (the prototype is a vLLM fork), and it adds communication overhead — O(layer) Attention-to-FFN transfers per request versus O(1) for PD disaggregation — requiring high-bandwidth NVLink scale-up interconnects (NVIDIA's GPU-to-GPU direct communication fabric). But it establishes the direction: as context windows and agent session lengths grow, operator-level disaggregation is the next cost lever. 4
Three things PMs should do now
1. Specify TTFT and TPOT separately in every vendor contract — not "latency."
End-to-end latency hides the split. A model taking 15 seconds to produce the first token is operating as a batch system inside a chat interface — that's a disaggregation architecture problem, not a prompt engineering problem. 11 Ask your inference provider for P95 TTFT and P95 TPOT under your expected request distribution. If they can't answer, find one who can.
2. Treat "disaggregated serving" as a vendor selection criterion, not a nice-to-have.
Perplexity, Meta, LinkedIn, and Mistral all run disaggregated serving in production. 2 Baseten and Databricks both offer it as standard infrastructure. When evaluating managed inference APIs, ask: is prefill/decode disaggregated? Is the P/D ratio tunable or fixed? Is KV cache routing cache-aware? These questions separate competitive infrastructure from commodity API wrappers.
3. If your product uses a large MoE model, file AFD as a 2027 infrastructure watch item.
The Georgia Tech/Intel/Google paper confirms that strict sub-100ms TTFT SLOs on models like DeepSeek are only achievable today on dedicated disaggregated clusters. The NVIDIA DynoSim tool — which simulates 23,608-request serving traces at 1,500× real-time speed on a MacBook Air — exists specifically to explore the cost-latency Pareto frontier of these configurations before committing to hardware. 12 NVIDIA's Dynamo serving stack already supports this simulation loop. If your product roadmap includes agentic or long-context workloads on MoE models in 2026–2027, plan for disaggregated infrastructure as a requirement, not an optimization.
Cover image: AI-generated illustration
References
- 1
- 2
- 3
- 4
- 5Modular: Three trends from MLSys 2026
modular.com
- 6KubeDojo: llm-d joins CNCF Sandbox
kubedojo.com
- 7
- 8Databricks: Reliable LLM Inference at Scale
databricks.com
- 9Xiaomi MiMo Blog: Full-Pipeline Inference Optimization
mimo.xiaomi.com
- 10
- 11
- 12NVIDIA DynoSim: Simulating the Pareto Frontier
developer.nvidia.com
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.