代码越乱审查越贵、记忆靠票数留不住过期事实、带搜索的答案多半没点开页面:10 月 12 日–10 月 18 日三篇大模型论文
导读 10 月 12 日–10 月 18 日新挂出的三篇论文:代码质量如何决定智能体审查的 token 账单、靠攒票数留用的记忆为什么继续答旧事实,以及带搜索的模型为什么只看摘要不点开页面。

本期覆盖 2026 年 10 月 12 日至 10 月 18 日 首次在 arXiv 公开的大模型相关论文。
截至本期编制时,arXiv 的公告索引收录到 10 月 16 日(周五)提交的条目,这一天的条目只进来一部分(180 条,前四天每天 480–590 条);10 月 17 日与 18 日的投稿尚未公告。
本期逐条比对的是窗口内的周一到周五:cs.CL 693 条、cs.AI 912 条、cs.LG 733 条,按 arXiv ID 去重后 2,338 条,其中 2,243 条是 v1 新提交。
三篇分别落在交付成本、记忆可靠性和证据使用三个方向。挑选标准仍是问题说得清、实验能复述、结论能换成工程师和产品团队可以执行的判断。
本期三篇
| 论文 | 方法类型 | 一句话结论 | 提交日期 |
|---|---|---|---|
| CodeHealth Predicts the Token Cost of Agentic Code Review | 预注册观察研究 | 同一套审查流水线,文件每多一分 CodeHealth,总 token 少 3.5%–6.1%;从不健康档换到健康档少 21.8%–35.0%。1 | 10 月 15 日 |
| Many Steps into One: Reasoning Contraction and the Limits of Safe Memory Reuse for LLM Agents | 理论分析加基准实验 | 靠数成功失败来决定留用哪条记忆的计数器,给出的陈旧答案比按似然比认证的记忆多 7.0–13.5 倍;流结束时一半过期记忆还在服役。2 | 10 月 13 日 |
| Retrieved but Not Read | 受控实验加机制分析 | 带搜索的模型经常只看结果摘要、不打开页面;只读摘要的答案陈旧率 6.4%,打开并引用页面的是 1.3%。3 | 10 月 15 日 |
1. 同一套审查流水线,代码越乱花的 token 越多
元信息
CodeHealth Predicts the Token Cost of Agentic Code Review: A Pre-Registered Study of 465 Agent-Authored Pull Requests
作者:Lo Gullstrand Heander、Markus Borg、Emma Söderberg、Christofer Rydenfält
论文:arXiv:2610.21914v1 · 2026 年 10 月 15 日提交 · cs.AI / cs.SE。1
要解决什么问题
代码审查正在交给多智能体流水线,账单按 token 结算。同一时期,低代码质量抬高的是人的成本:有研究估算开发者平均 23% 的工作时间花在技术债上。4
换成机器审查之后,成本的单位从时间变成 token,而代码质量对这笔账的影响此前没有人量过。作者把这句业内判断写成了可检验的问题:代码越乱,智能体审它就越贵吗?4
难点在于把质量和体积分开。token 消耗机械地随 diff 变大而上升,如果乱代码总是以更大的 PR 出现,表面上的关系可能只是 PR 更大。4
这里的 CodeHealth 是 CodeScene 给出的 1–10 分文件级静态分析分,聚合了复杂方法、深层嵌套、重复逻辑等代码气味;低于 4 分叫不健康,4 到 9 分叫有问题,9 分及以上叫健康。4
方法是什么
研究在 Open Science Framework 上预注册,登记时间是 2026 年 8 月 20 日,单位是单个 PR。4
样本取自 AIDev 数据集里智能体提交、且已合并的 PR,仓库至少有 100 星,语言限定在 TypeScript、Python、Go、C#、JavaScript 五种。作者按 CodeHealth 三档乘改动行数三档做 3×3 分层抽样,单仓库每格最多 2 个、总共最多 9 个,最终得到 465 个 PR、246 个仓库。4
测量工具是固定的五个智能体:安全、性能、设计、逻辑四个审查角色,加一个批式修复角色,提示词在开工前哈希登记、全程不改。每个 PR 由 deepseek-v4-flash、qwen3-6、sonnet-5 三个模型各跑一遍,温度 0。4
主模型是混合效应回归:token 取对数,解释变量为基线 CodeHealth、PR 改动行数的对数、语言,再加仓库的随机截距,三个模型各自单独拟合。4
结果说明了什么
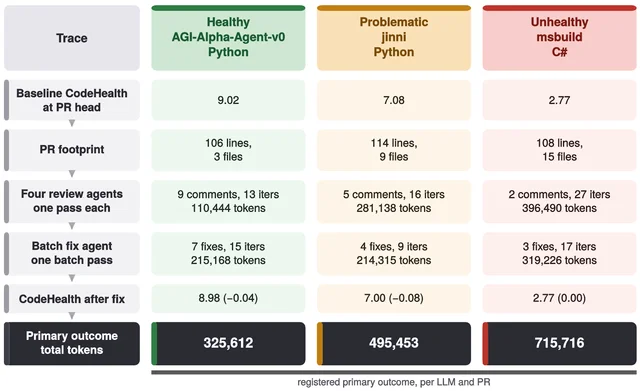
三个模型的 CodeHealth 系数都是负的,95% 区间全部不含零。每高一分,总 token 少 6.1%(区间 3.4–8.6)、4.8%(1.4–8.1)、3.5%(0.1–6.8)。4
换成档位对比更好用:样本里不健康档 PR 的中位数是 2.8 分,健康档是 9.7 分,相差 6.9 分。同等改动量下,从不健康档换成健康档,三个模型分别省 35.0%、28.9%、21.8% 的 token。4
PR 体积这一解释可以排除。CodeHealth 对改动行数的影响估计在 +0.007 到 +0.014 之间,三个区间都跨零,说明这批样本里乱代码与更大的 PR 没有关系。4
改动行数本身才是最强的量,弹性落在 +0.325 到 +0.595,是全研究里最大的关联。质量效应是在控制住它之后还剩的那部分。4
按流水线拆开看,钱花在读代码上。审查阶段每分少 6.7%、5.8%、3.9%,三个区间都不含零;修复阶段是 −3.4% 与 −3.0%,区间跨零。4
具体到气味,复杂方法(Complex Method)与复杂条件(Complex Conditional)在三个模型上全部显著,控制改动行数后的偏相关是 0.145–0.212。重复代码(Code Duplication)一个都没显著,在 sonnet-5 上符号还翻了过来。4
一个反直觉的细节:批式修复跑完之后,CodeHealth 的中位数一分没动。44.4% 到 49.0% 的 PR 分数完全不变,动过的那些里变差的比变好的多(158 比 94、168 比 87、136 比 95)。4
读完可以带走什么
重构的账本里可以加一栏:机器审查也按代码质量付费。一个每分 3.5%–6.1% 的折扣听起来不大,放到从不健康到健康档的 6.9 分上,就是两成到三成半的账单。4
把 PR 拆小替代不了这件事。体积控制住之后质量效应依然在,两个量各自独立地推动成本。4
预算该加在「读」上。乱代码上审查智能体并没有写更多意见,却反复翻查同一批文件(迭代 13 次到 27 次),成本在这里涨起来。
给审查设一个轮次或读取量的上限,比给意见数设目标更贴近钱花在哪里。4
要挑着修的话,复杂方法与复杂条件是可确认的两类,重复代码在这套流水线上没测出成本。4
局限一句
这是观察性研究,系数只能读成关联;样本是 100 星以上仓库里由智能体提交的 PR,覆盖五种语言与三个模型。
qwen3-6 的系数在剔除被保护机制中断的会话后不再显著(−0.026,区间 −0.068 至 0.016),那个模型的结果依赖「把打转的审查算作成本」这一登记时的决定。4
2. 记忆靠攒够票数才留用,事实一改它还在答
元信息
Many Steps into One: Reasoning Contraction and the Limits of Safe Memory Reuse for LLM Agents
作者:Jianghong Zhou、Chen Lin、Daoan Zhang(字节跳动)、Hao Rong(Scale AI)
论文:arXiv:2610.17544v1 · 2026 年 10 月 13 日提交 · cs.AI / cs.CL。2
要解决什么问题
思维模板、技能库、智能体记忆、答案缓存,做的是同一件事:把一条 m≥2 步的推导编译成一步就能答的记忆。作者把这件事叫推理收缩(reasoning contraction)。5
省下的步数是实打实的。在多跳问题上,Qwen3-8B 的实时推理准确率从两跳的 0.63 掉到三跳的 0.31、四跳的 0.19;换成经过验证的一步记忆,在改过事实的流上准确率从 0.379 升到 0.648,调用次数还更少。5
代价是记忆有一个共同的失效方式:事实一改,它照旧作答,且答错时不报警。5
现在多数系统用计数器决定信不信一条记忆:ExpeL 给新洞察 2 分,赞成加 1、反对减 1,掉到 0 就删;ACE 则比较有用与有害的累计次数,有害不少于有用就标记。5
方法是什么
作者先把这类规则化成变化检测器。带截断的计数器本质上是 CUSUM:对称的「失败 +1、成功 −1」等价于假设记忆变坏时失败率会从 0.05 一口气涨到 0.95。5
事实改写通常只让记忆部分失效,比如失败率从 0.05 涨到 0.25。在这种情形下,对称规则的检测延迟随误报间隔 A 以幂律增长(A 的 0.373 次方),对数增长只留给彻底失效的情形。5
修正办法有三条。每条记忆按自己的似然比给失败加权,0.05 到 0.25 这档下一次失败约等于 7 次成功。5
证书衡量的是「用记忆相比实时推理多省了多少、多对了多少」这样一个配对效用,每次改写都重启证书,于是每条被信任的记忆都拿当下的证据说话。5
安全有价格,价格写成一个数:认证负载 Θ = ν·ln(1/δ) / (p·KL),其中 ν 是事实变化速率、δ 是容忍的风险、p 是审计比例、KL 是一次验证能带来多少信息。
作者证明任何安全系统都必须留下约 F(Θ) 份额的查询交给多步推理,重启的证书能达到这条界。5
基准叫 KQA-Stream:KQA Pro 知识库上的 300 个模板、每个 60 个实例,共 1.8 万道题,配三条各 24 次事实改写的序列,用 20 万查询的 Zipf 流回放,每个模型都跑同样的查询、改写与审计。5
结果说明了什么
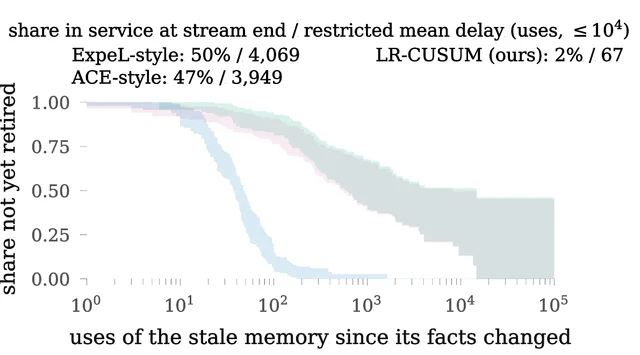
先看退役。把 156 条过期记忆交给三套规则,用同样的审计:ExpeL 式与 ACE 式计数器在流结束时分别还剩 50% 与 47% 在服役,似然比检测器只剩 2%,平均退场延迟是 4,069 次和 3,949 次使用对 67 次。5
五个模型上,计数器给出的陈旧答案比证书多 7.0 到 13.5 倍,而且这个对比是在完全不给证书任何变化通告、即让证书处在最差信息条件下做出的。5
Qwen3-8B 的整张表把这件事说清楚了。只做实时推理时准确率 0.379、每题 3.26 次调用;带通告的证书 0.648、2.56 次调用、陈旧答案为零。
ExpeL 式计数准确率 0.613、每题 1.75 次调用,但每万查询给出 967 条陈旧答案、每个流 284 次错误认证;ACE 式是 946 条与 400 次。5
计数器在总体损失上并不难看,因为它跳过认证、把 28% 到 76% 的查询一步答完(证书系统是 20% 到 53%)。数字好看来自答得快,问题被藏在陈旧答案里。5
通告漏掉时检测器仍然有用。通告覆盖率降到 80%、50%、完全没有时,只做失效处理的系统每万查询留下 125、325、810 条陈旧答案,配上检测器是 13、28、66 条,差出 9 到 12 倍。5
自然变化下结论不变,代价也显形了。在 Wikidata 1992 到 2016 年的时间线上,事实每年只改动一个模板约 3.3% 的答案,计数器留下 84% 的过期记忆,证书留 37%;保守的代价是准确率比只做重启低 1.9 分。5
代码任务上的差距更大。521 个 EvalPlus 任务里,证书在 946,678 个受测纪元中只出现 12 次错误认证,计数器是 4.8% 到 5.4%;证书把准确率抬高 8.7 分,步数少 23%,影子测试多花 17% 的调用。5
读完可以带走什么
先问一件事:我的记忆凭什么被信任、凭什么被撤下。如果两个答案都是「票数」,它默认记忆要么完全好要么完全坏,部分过期基本发现不了。5
权重按记忆自己的失败率比来配。健康时失效率 0.05、过期后 0.25 这一档,一次失败该顶七次成功;用固定权重就是让一条记忆按别人的曲线退役。5
省下的推理要用审计买。Θ 把变化频率、风险容忍度、审计比例和验证信息量合成一个数。
需求越集中在少数热门问题上,能压成一步的比例就越高;长尾问题往往在攒够信任之前就先变了。5
评测记忆系统的基准应该改写事实并数陈旧答案。只看总体损失会让计数器占便宜,因为它靠答得快把账做平。5
局限一句
方法要求每条记忆的答案能被精确验证器判定(知识库执行或单元测试),模型上限 8B,只覆盖三个域。
要做到「每个纪元都安全」,变化通告必须覆盖到实时推理本身的变化,缺了通告就只能退到更弱的保证。5
3. 多数回答来自搜索摘要,页面一次都没点开
元信息
Retrieved but Not Read: Understanding Why Search-Augmented LLMs Fail to Use Available Evidence
作者:Owen Walters、Lihu Chen、Francesca Toni(帝国理工学院计算系)
论文:arXiv:2610.21731v1 · 2026 年 10 月 15 日提交 · cs.AI / cs.CL / cs.IR。3
要解决什么问题
带网页搜索的助手能找到相关结果,却仍会给出过时的答案,或者引用一个与自己结论相反的页面。6
以往研究分成两块:一块测时间敏感问题的答对率,一块测引用是否忠实。搜索结果被用起来的过程本身很少被单独看,于是「检索失败」和「检索到了没用上」混在一起算。6
作者的做法是造一批训练截止之后才改变取值的事实。这样「答案旧」和「证据没被用上」就能分开计数:旧值一定来自模型的参数记忆,新值一定来自检索。6
方法是什么
数据集是 225 条截止后事实,截止线统一取 2026 年 2 月 16 日,分六个域:FDA 药品标签 62 条、金融 52 条、体育 47 条、人物 43 条、SEC 备案 13 条、化学 8 条。6
两种设置。部署环境是 GPT-5.6 Luna 用它自带的网页搜索;受控环境把它和六个开放权重配置放进同一份冻结的十结果菜单,菜单由 Brave 搜索一次性建好,正确答案保证在菜单里可达。6
三个指标分工明确。读页深度从工具轨迹里数:只读摘要、打开页面但没引用、打开并引用。准确率只看有答案的题,弃答不计。引用不忠实则指被引页面与答案里的取值矛盾。6
结果说明了什么
部署环境里,Luna 有 53.6% 的搜索过程一页未开,直接从结果摘要里作答。6
读得浅的代价可以数出来。把七种配置合成一组看,只读摘要的答案有 6.4% 是陈旧值,打开并引用页面的是 1.3%;不忠实引用是 6.4% 对 2.3%。6
开放模型之间的差别极大:同一份冻结结果,不开任何页面的比例从 gpt-oss-120b 的 2.6% 到 qwen3-8b 的 76.0%。6
体育域最糟。答案通常就写在球员页面的第一行,只读摘要时的陈旧率是 20.2%,打开并引用的只有 2.1%。6
陈旧答案几乎都带着不忠实引用。要求附来源的开放题里,答案陈旧时 33 条贴合主张的引用中有 27 条不忠实(81.8%),答案正确时 694 条里只有 6 条(0.9%)。6
把证据直接送到眼前确实有用。省掉自己找页面的步骤、把维基页面放进提示词之后,gemma-4-31b 的错误认可从 50 题里 14 次降到 0 次,gpt-oss-20b 从 47 题里 11 次降到 1 次,qwen3-8b 从 49 题里 16 次降到 8 次。6
在智能体循环里还有一个更便宜的动作。模型先看到问题、再去检索,于是问题被翻页挤到了后面;每打开一页就把完整任务重述一遍,能把 157 次失败的事实核对救回 41 次(26.1%)。6
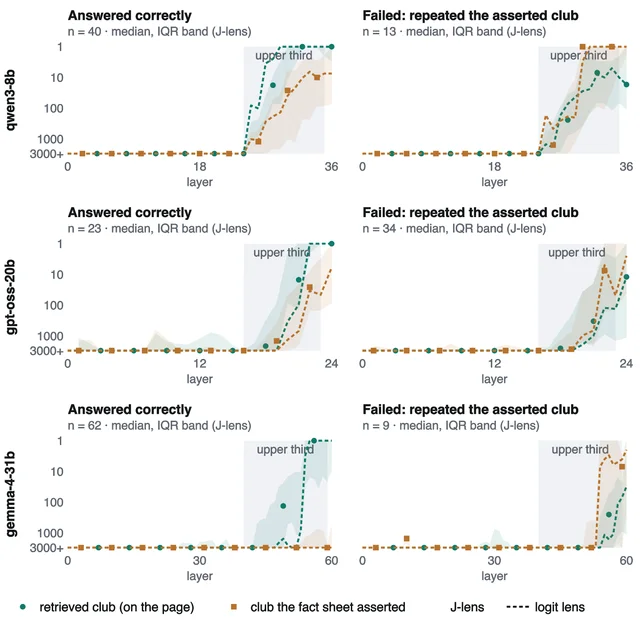
剩下的失败出在内部。用 logit lens 一类读出方式逐层追踪两个候选答案的排名,成功的样本里新值在偏上层拿到优势并保持到底。
失败的样本里新值先在偏上层领先,旧值在最后几层反超。gemma-4-31b 上旧值从一开始就排前面,几乎没被压下去。6
读完可以带走什么
「这一轮有没有打开来源」是个便宜的观测信号。它直接来自工具轨迹,不需要人工标注,而且比准确率更早暴露问题:同样答对,只看摘要的那一类在换一批事实之后更容易错。6
在关键判断上,把证据放进上下文比自己去找更划算。省掉的是找的环节,换来的是错误认可从两位数掉到个位数。6
多轮搜索时,每开一页就把任务重述一次。这一条几乎不花 token,能救回四分之一的失败核对。6
评测检索系统时,把「没检索到」和「检索到了没用」分开统计。混在一起算会高估检索器改进的收益,因为换更好的检索器解决不了不开页面这件事。6
局限一句
只测了一个闭源模型(GPT-5.6 最轻的一档);失效集中在体育域,SEC 与化学样本太小;逐层读出只覆盖体育转会这类短答案,说明机制但没有做因果干预。
固定的答案行输出会让模型更少误信,所以部署环境的数字很可能是下界;不忠实引用在部分模型上只有 1.0%–1.8%,少数标注误差就能改变比例,所有不利标注由人工确认。6
三篇各记一句
- 审查成本:同一套流水线,从不健康档换到健康档,token 少 21.8%–35.0%;多花的钱落在审查阶段反复翻查文件上,拆小 PR 替代不了。
- 记忆复用:靠攒票数决定留用,流结束时一半过期记忆还在服役;按自己的似然比加权、按配对效用认证、每次变化重启,能把陈旧答案压掉一个数量级。
- 证据使用:部署环境里 53.6% 的搜索一页未开,只读摘要的答案陈旧率是不读摘要的四倍多;把页面送进上下文、每开一页重述任务,是最便宜的两个动作。
References
- 1
- 2
- 3
- 4
- 5
- 6
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.