Inception says Mercury 3 runs at 1,068 tokens a second. OpenRouter measures 227.
Inception's Mercury 3 claims 1,068 tokens a second and a fraction of the cost. OpenRouter, serving the same servers, counts 227, and Inception's own price table turns more expensive than both rivals once the 50% badge comes off.

"Across a range of benchmarks, Mercury 3 outperforms GPT-6 Luna and Claude Haiku 5.5, while running 4–8x faster at 1,000+ tokens per second."
Inception published its launch post for Mercury 3 on 19 October, and that sentence is the first paragraph.
Mercury 3 is the newest in a line of diffusion language models. The bet behind it is that text can be generated the way images are: sketch the whole answer, then refine it, instead of writing one token at a time 1.
Two speed numbers are worth keeping side by side. Inception reports 1,068 output tokens a second. OpenRouter hosts the model, forwards every request straight to Inception, and reports 227.
What the speed number measures
Inception gives the figure with its hardware attached: "1,068 tokens per second on NVIDIA GPUs" 1.
The post names the chip vendor and stops there. It gives no GPU count, no batch size and no prompt length.
OpenRouter lists one provider for Mercury 3 and makes no routing decisions, so its number and Inception's describe the same servers 2. Its table reads 227 tokens a second at the 50th percentile, with 0.77 seconds of latency and 99.97% uptime over three days.
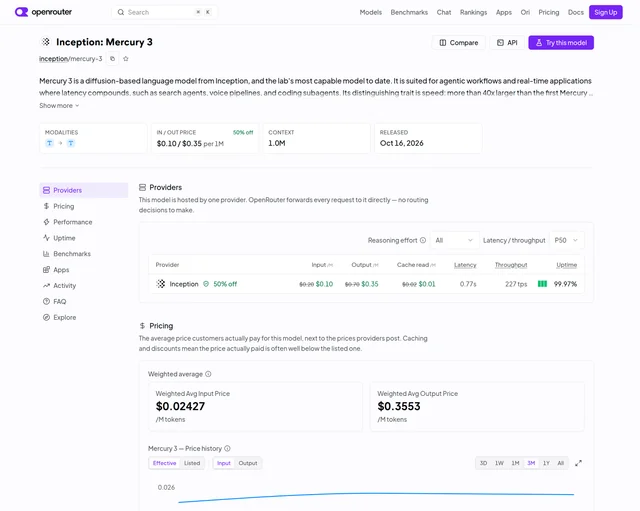
Both numbers can be honest. A vendor figure tends to be the best throughput its serving team can produce on a chosen setup. A marketplace figure is the median of what customers actually got, long prompts and cold caches included.
The gap matters because you are buying the second one. Size a support agent against 1,068 tokens a second and you staff for a capacity that thins out in production.
The Decoder reported on launch day that no independent test of Mercury 3 existed yet 3. OpenRouter's counter is the nearest thing to one, because it comes from traffic rather than a demo rig.
The table runs all three models at medium
Inception's comparison keeps its settings in the column headers, which is more than most launch posts manage. All three columns read "(Medium)".
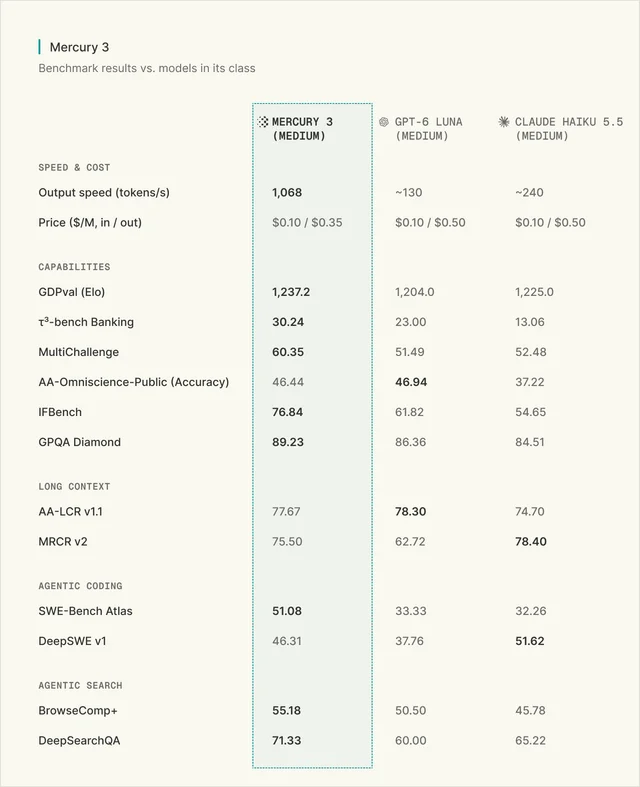
Mercury 3 wins eight of the twelve rows. The margins are uneven. Instruction following is the widest: 76.84 on IFBench against 61.82 for GPT-6 Luna and 54.65 for Claude Haiku 5.5 1.
Autonomous coding on SWE-Bench Atlas goes 51.08 to 33.33 and 32.26. GPQA Diamond goes 89.23 to 86.36 and 84.51.
The four losses fall into a pattern. Mercury 3 scores 46.44 on AA-Omniscience accuracy against Luna's 46.94, and 77.67 on AA-LCR v1.1 against Luna's 78.30.
Those two are close enough to call a tie. The other two are not: 75.50 on MRCR v2 against Claude Haiku 5.5's 78.40, and 46.31 on DeepSWE v1 against 51.62.
Then there is the setting. Inception's API takes a
reasoning_effort parameter with four values: instant, low, medium and high. For mercury-3 the default is low 4.A developer who swaps the model name in an existing OpenAI client gets the low setting. The table above was produced at medium. The default sits one notch below the configuration behind the headline.
That is worth knowing before you compare your own eval run against Inception's. Set the parameter explicitly, or the numbers will disagree for a reason that has nothing to do with your prompt.
Where the million-token window stops helping
Context length is the second headline spec: 1M tokens, up from 260K in Mercury 2.5, with a maximum output of 131,072 tokens 5.
Two of the four benchmark losses are long-context tests. AA-LCR v1.1 and MRCR v2 both ask a model to find and use something buried in a long input. Mercury 3 loses both, and MRCR v2 goes to Claude Haiku 5.5 at 78.40 1.
The long coding test tells the same story. DeepSWE v1 runs an agent through extended edit sequences, and Mercury 3 scores 5.31 points behind Claude Haiku 5.5.
A 1M context is a capacity claim: the request will be accepted. How much of it the model can use is what those rows measure, and on Inception's own table the answer is less than the window suggests.
That splits the use cases cleanly for anyone deciding this week. Short turns, tool calls and fast corrections are where Mercury 3 has evidence behind it. A repository-sized diff or a folder of contracts is where its own table sends you elsewhere.
The price column carries an expiry
The Mercury 3 card prints two prices for every line item: a struck-through list rate and a live 50% discount beside it 6. Input runs $0.20 down to $0.10, cached input $0.02 to $0.01, output $0.70 to $0.35.
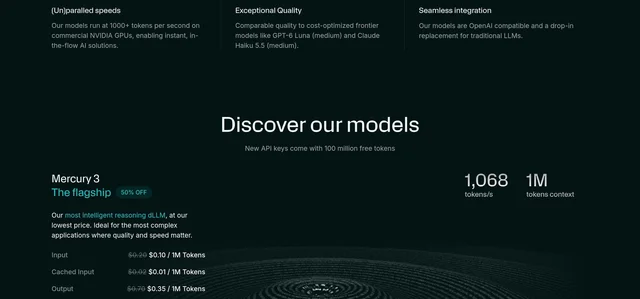
No page in the launch material states when the discount ends. The Decoder noted the same absence on launch day 3.
Now read the price row in the benchmark table. Mercury 3 sits at $0.10 in and $0.35 out. GPT-6 Luna and Claude Haiku 5.5 are both listed at $0.10 in and $0.50 out 1.
That row sets a promotional rate against two published ones. Strip the badge away and Mercury 3 costs $0.20 in and $0.70 out, against $0.10 and $0.50 for both rivals. At list price it is the dearest of the three on every line.
A worked example makes the swing concrete. Take one agent step with a 10,000-token prompt and a 500-token reply:
- At the launch price, a thousand such steps cost $1.18.
- At the list price, the same thousand steps cost $2.35.
- A rival charging $0.10 and $0.50 costs $1.25.
The launch price lands level with the competition. The list price lands close to twice it.
The models page describes Mercury 3 as running "at a fraction of the cost of other top-tier models" 6. That sentence holds while the badge is up and reverses when it comes down.
One place the list price still works: very long prompts. Inception's table quotes short-prompt input rates, and The Decoder reports that both rivals charge considerably more once the input grows 3. A 1M-token request is where $0.20 input can still win.
What survives the drop-in swap
The OpenAI-shaped endpoint is the part of this launch that holds up best. Mercury 3 takes
tools and tool_choice, returns parallel tool calls, and accepts a JSON schema in response_format 7. Setting strict on a tool definition enforces the schema. An agent framework that speaks the OpenAI dialect can point at api.inceptionlabs.ai/v1 and work.Three things will bite an integration that expects an OpenAI model.
There is no
seed parameter, temperature is clamped to the range 0.5 to 1.0, and the FAQ says bit-exact reproducibility across runs is unsupported 8. A workflow that needs the same answer twice, such as a classification or a quote, has to average over samples.Streaming arrives in blocks. The docs describe a block as "a chunk of refined text the model emits as it decodes, rather than one token at a time" 9. A UI that counts tokens as they land will read low, and one that expects smooth per-token motion will look chunky.
The default reasoning setting is
low, as above. Three parameters to set explicitly, then a normal evaluation.The contract rules out the use cases in the launch post
Inception's Terms of Use went into effect on 1 September 2025 10. One clause in the basics section reads:
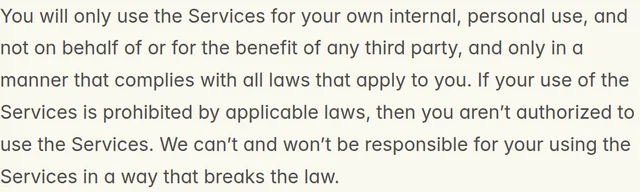
"Internal, personal use" is the phrase to hold onto, because the launch post is built on companies doing the opposite.
Lorikeet runs a concierge across voice, chat and email for its own business customers. General Learning gives students hints and marked answers. Octen puts the model behind smart glasses a customer wears. Every one of those partners serves third parties, which is the thing the clause excludes 1.
The same list bans content that "relates to high-stakes decision making involving individual rights" 10. Inception sells a model built for that kind of call: Mercury Decide makes structured choices with calibrated probabilities and escalates the unsure ones to a human 6.
The document allows Additional Terms to apply to particular services. Read as written, the click-through on the website describes a person trying a model in their own work. The launch post describes companies shipping one to their customers. Those are two different contracts, and only a sales conversation gets you from the first to the second.
Your prompts train the model unless you find a switch
The Terms grant Inception a perpetual licence over what you submit and say plainly what it covers: "we may use User Submissions to provide and maintain our Services, comply with applicable law, enforce our terms and policies, and train our models" 10.
The opt-out is a settings toggle called "Improve the model for everyone", which you turn off in the API platform.
The privacy policy, in force since 4 April 2025, lists "Personal Data contained in prompts, inputs and uploaded content processed by our models" among the categories it collects 11. It also names "training and refining our models" as a business purpose.
Retention runs "for as long as necessary", with no published number. The FAQ sends anyone who needs zero retention to the support queue, where such arrangements are "handled case by case" 8.
For a tutoring app handling children's homework, or a support agent reading account records, that is the first thing to settle. It settles in a contract rather than a checkbox.
The previous generation has 27 days
Mercury 2 and Mercury 2.5 are closed to new users. Customers who had usage before 19 October keep access until 15 November 6.
That is the migration window this company works to. A team building on Mercury 3 should read the note as a statement about the next twelve months rather than a footnote about the last one.
The rest of the portfolio shows the same split between what is announced and what is buyable. Mercury Voice, part of the post's "real-time product portfolio", has no self-serve path: the docs say to email sales to enable it for an organisation 5.
Mercury Decide is priced at $0.02 per million input tokens with output free. OpenRouter notes that it speaks the same
/v1/systemone schema as Jev, the model Inception's post says it beats 2.Verdict
Mercury 3 is a real model with a real result: a diffusion language model that answers tool calls, enforces a JSON schema and returns in a fraction of the time a frontier model takes on the same turn. That much survives every document in this piece.
The launch page sells a different object. It sells 1,068 tokens a second, and the marketplace serving those same servers counts 227. It sells a fraction of the cost, and its own table charges more than both rivals once the badge comes down. It sells partners serving customers, and its terms restrict the service to your own internal work.
So price the two planes separately. If your workload is a support agent on short turns, you can set
reasoning_effort to medium, you pin your budget to the undiscounted row, and you get a contract that permits your business, the speed is there and nothing else at this price is as quick.If the reason you wanted Mercury 3 was the 1M window, Inception's own table sends you to Claude Haiku 5.5: 78.40 on MRCR v2 against 75.50, and 51.62 on DeepSWE against 46.31.
The diffusion architecture earns the second look. The launch page does not.
References
- 1Diffusion at Scale: Introducing Mercury 3
inceptionlabs.ai
- 2Inception: Mercury 3 on OpenRouter
openrouter.ai
- 3
- 4Reasoning Efforts
docs.inceptionlabs.ai
- 5Models
docs.inceptionlabs.ai
- 6Our Models
inceptionlabs.ai
- 7Tool Use
docs.inceptionlabs.ai
- 8Frequently Asked Questions
docs.inceptionlabs.ai
- 9Streaming & Diffusion
docs.inceptionlabs.ai
- 10Terms of Use
inceptionlabs.ai
- 11Privacy Policy
inceptionlabs.ai
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.