The next AI-for-science bottleneck is dataset readiness
New U.S. programs are putting billions behind AI-for-science infrastructure and dataset engineering. The practical test is whether teams can prove that data is ready, reproducible, governed, and useful for a specific scientific task.

The funding is moving downstream
On July 22, the White House announced more than $5 billion in federal commitments for the Genesis Mission, a whole-of-government effort involving more than 15 agencies. Its proposed American Science and Security Platform is meant to connect researchers with data, compute, and AI tools across health, energy, infrastructure, manufacturing, and affordability projects. The announcement names assets ranging from longitudinal health cohorts and EPA monitoring data to DOE supercomputers and more than 150 petabytes of NASA data. 1
The important change is where the money is going. This is not only a bet on a better model. It is a bet on an integrated research system that can find data, prepare it, run computation, connect results to experiments, and coordinate people across institutions.
The same day's announcements show the stack taking shape. OpenAI says it will provide $4 million in Codex access for about 2,000 Genesis researchers, $3 million in API support for two large-scale scientific campaigns, and up to $10 million in API usage tied to $2.5 million in spending. The post describes high-temperature superconductivity and an atlas of the machine-accessible scientific frontier as planned campaigns, not completed discoveries. 2
Microsoft announced a separate $60 million commitment, split between $40 million in Azure compute and AI credits over three years and $20 million in engineering services. Its SPARK program is designed to manage intake, prioritization, checkpoints, security, compliance, and joint research. Microsoft also makes the less glamorous point that infrastructure by itself does not produce durable scientific results. People, domain expertise, delivery discipline, reproducibility, and governance still have to be supplied. 3
Those are commitments and operating plans. They show where institutions are investing, not that the resulting AI systems will discover reliable science.
The missing layer is data preparation
The National Science Foundation made that layer explicit in its July 22 announcement of the Unlocking Dataset Value for AI-Enabled Scientific Discovery program. NSF says the program will invest up to $100 million, with awards of $2 million to $5 million and planning grants of up to $200,000. It focuses mainly on existing scientific datasets that are valuable but not yet accessible, interoperable, or usable by automated systems. 4
The proposed work includes feature extraction, metadata generation, integration across datasets, and robust pipelines for automated analysis. The related funding opportunity also asks applicants to address data security and integrity, governance, and how a scientific community will contribute to and benefit from a dataset. 5
That is a data-science problem before it is a model problem. A dataset can be large, public, and technically accessible while still being a poor input to an AI workflow. Its units may be inconsistent. Its labels may encode several incompatible measurement practices. Its missingness may be related to the outcome. Its provenance may stop at the file level instead of recording how each training artifact was produced.
A model can hide these defects for a while. It can also turn them into confident, repeatable errors.
What AI-ready should mean
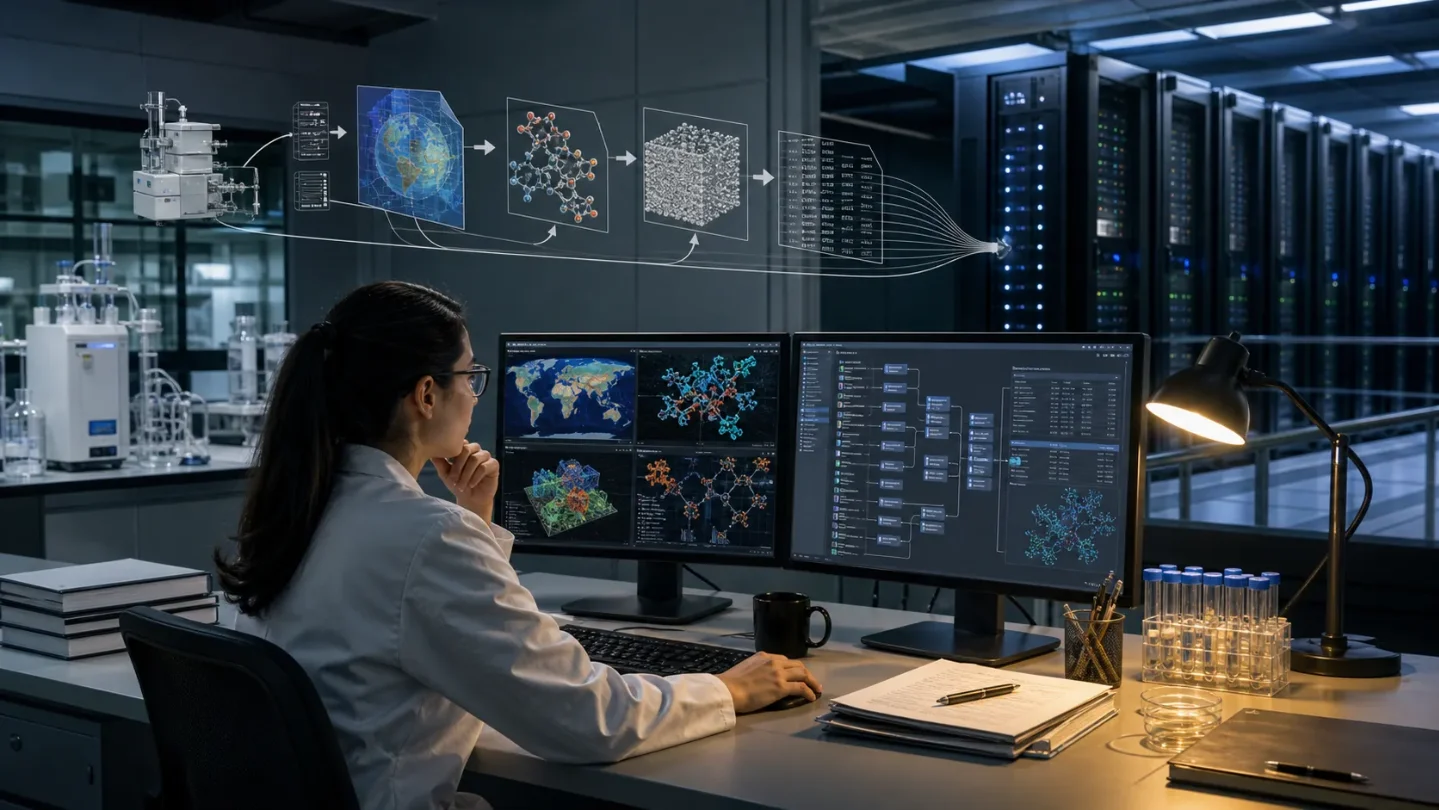
A July 2 preprint from researchers including Oak Ridge National Laboratory authors presents REDI, the Readiness Engine for Data Integration, as an attempt to make this preparation process explicit. REDI uses five stages: ingest, preprocess, transform, structure, and output. Its companion tool, SetGo, handles metadata readiness, FAIR checks, and catalog publication. The authors define AI-ready data as machine-readable data that has undergone domain-appropriate cleaning, validation, and feature engineering, with enough metadata to support reproducible model training and evaluation. 6
The paper evaluates the framework across climate, proteomics, materials science, and nuclear fusion workflows. It reports readiness-equivalent outputs across the cases and preliminary near-ideal parallel scaling to 100 nodes on the Frontier supercomputer for the climate example. It also reports that file I/O, rather than raw compute, was the dominant pipeline cost in its profiling, making storage format and file layout practical performance decisions. These are preprint results from the authors' evaluation, not an independent deployment audit. 6
For teams building or buying a scientific AI pipeline, the useful part is the separation of readiness dimensions:
| Dimension | Question to answer before training |
|---|---|
| Semantics | Do fields, units, coordinate systems, labels, and missing values mean the same thing across sources? |
| Transformation | Can another team rerun every cleaning, normalization, feature, and format-conversion step? |
| Provenance | Can each training artifact be traced back to raw inputs, code, parameters, versions, and approvals? |
| Validation | Were domain checks run on the transformed data, including leakage and split checks? |
| Task fit | Ready for which model, scientific question, decision, and error tolerance? |
The last row prevents a common category error. "AI-ready" is not a universal property of a file. A dataset may be ready for a climate surrogate model and unsuitable for a causal analysis, a materials simulator, or a clinical decision-support task.
FAIR is a foundation, not a verdict
FAIR data principles make data findable, accessible, interoperable, and reusable. REDI's paper argues that FAIR compliance is necessary but not sufficient for AI use. A FAIR dataset can still require normalization, feature engineering, or a domain-specific representation before it is suitable for training. NSF's funding opportunity makes a similar practical assumption by asking for pipelines, security, integrity, and governance rather than only a public repository link. 56
This distinction matters even more when coding agents are allowed to write preprocessing code. The REDI paper lists familiar failure modes: normalization calculated on the full dataset instead of the training split, inconsistent splits between runs, assumed format conventions, and missing provenance. An agent can complete a pipeline and still leave the scientific team unable to explain what changed or reproduce the result.
The engineering response is to make transformations framework-mediated and inspectable. A generated script may be useful, but it should not be the only record of the data state. Teams need versioned intermediate artifacts, machine-readable metadata, validation outputs, and a way to compare an agent-produced transformation with an independently implemented one.
Throughput is not scientific validity
The current Genesis announcements are strongest as evidence of institutional direction. The White House describes a shared platform and federal datasets. OpenAI and Microsoft describe access, compute, engineering support, and research campaigns. None of those announcements establishes that an AI agent can independently formulate a sound hypothesis, choose a valid experimental design, or distinguish a statistical artifact from a discovery.
A July 16 arXiv essay makes that boundary its subject. Emmanuel Jeannot describes AI-driven research as a shift from a craft model toward a supervised pipeline, and raises concerns about opaque machine-generated theories, a flood of output that could overwhelm peer evaluation, compounding errors in closed-loop workflows, and a thinner training path for human researchers. The essay is a conceptual argument rather than an empirical evaluation, so it should not be read as a measured forecast. Its value is as a checklist of failure modes that an infrastructure program needs to test. 7
The distinction can be stated simply:
- Infrastructure evidence shows that an organization can connect data, compute, tools, and people.
- Pipeline evidence shows that data can be transformed, validated, and reproduced under defined conditions.
- Scientific evidence shows that the resulting system improves a scientific decision or discovery task on held-out or independently checked cases.
The first can exist without the second. The second can exist without the third. A fast, reproducible pipeline is a prerequisite for trustworthy AI-for-science work, not proof that the work is correct.
A practical adoption test for data teams
Teams evaluating a scientific AI platform should require evidence at the level where the decision will be made.
- Define the endpoint first. Specify the scientific question, the prediction or experimental decision, the acceptable error, and the holdout data before choosing a model or transformation pipeline.
- Version the whole data lifecycle. Keep raw, intermediate, and final artifacts linked to code, parameters, schema changes, validation results, and approvals. A final training file without its transformation history is not an auditable asset.
- Test domain invariants. Check units, ranges, conservation rules, label meaning, coordinate systems, missingness, and leakage. Generic schema validation cannot replace scientific checks.
- Measure the end-to-end outcome. Track scientific accuracy, calibration, failed experiments, time to a verified result, and reviewer effort. Preprocessing speed and model benchmark scores are supporting measurements.
- Reproduce outside the agent's path. Use an independent pipeline, a held-out dataset, or a fresh research team to test whether the result survives a change in code, prompt, model, or infrastructure.
- Set access and rollback boundaries. Sensitive data, production instruments, external APIs, and automated experiments need least-privilege credentials, audit logs, sandboxing, human approval, and a tested rollback path. Microsoft's emphasis on security, compliance, reproducibility, and governance is a useful baseline for these controls. 3
The most honest success metric is not "how many hypotheses did the agent generate?" It is how many independently verified scientific results the full system produces per unit of compute, data-engineering effort, and expert review.
The bottom line
The July 2026 Genesis and NSF announcements move AI-for-science toward the layer that determines whether models can be used at all: curated data, interoperable formats, provenance, shared compute, governance, and domain review. That is a healthier basis for progress than treating each new model as a self-contained research engine.
The near-term opportunity is substantial. Existing datasets may support questions they were never originally collected to answer, and automated preparation can reduce repeated engineering work across scientific communities. The near-term risk is equally concrete: organizations may count accessible data, model calls, or generated hypotheses while skipping the checks that connect those inputs to valid knowledge.
For data science teams, the next procurement question should be precise: can this system show what it changed, why the change was appropriate for the scientific task, and whether an independent team can reproduce the result?
Primary sources
- Trump Administration Announces More Than $5 Billion for the Genesis Mission
- Advancing the next era of national science
- Powering America's Genesis Mission: Microsoft's commitment to scientific discovery
- New NSF initiative aims to unlock dataset value for AI-enabled scientific discovery
- Unlocking Dataset Value for AI-Enabled Scientific Discovery
- Automated Data Readiness for Scientific AI
- The Industrialization of Research: On AI-Driven Science and Its Consequences
Follow the author
References
- 1
- 2
- 3
- 4
- 5
- 6
- 7
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.