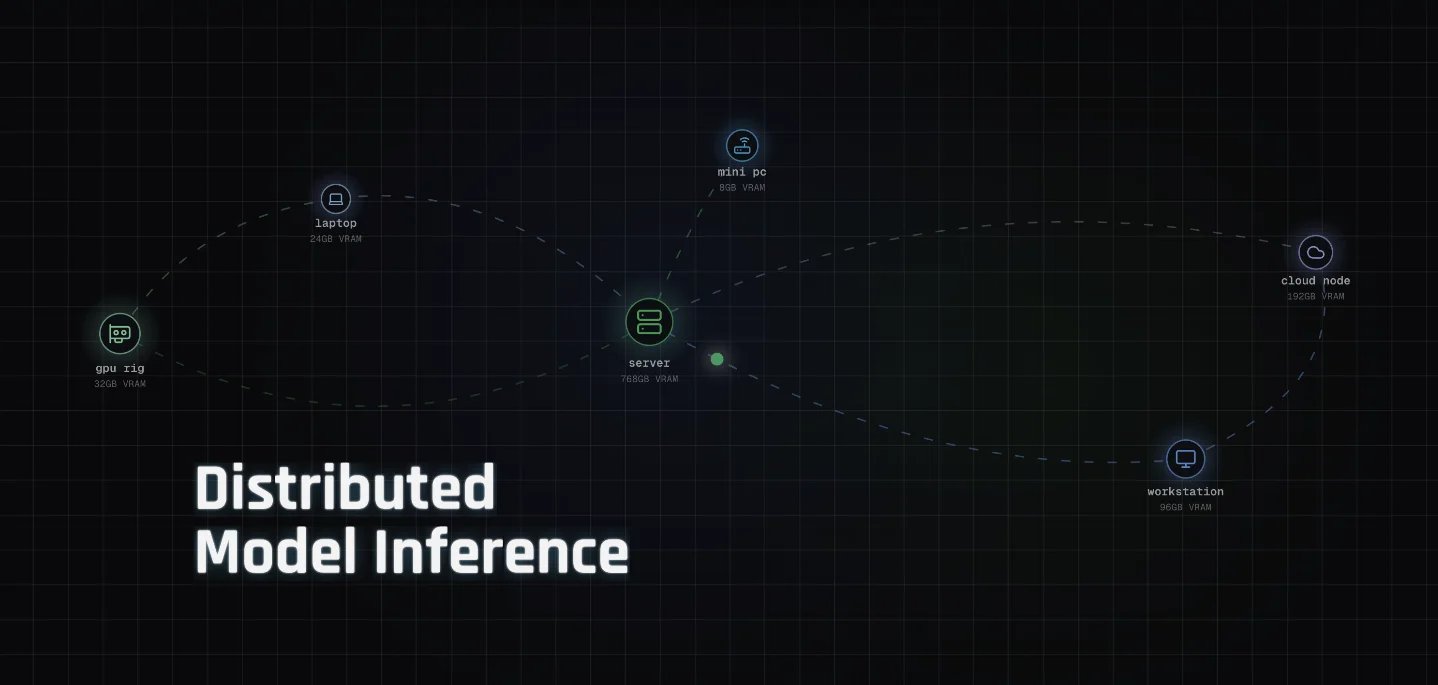
Run big models on spare GPUs
Mesh LLM makes distributed inference product-visible by exposing pooled GPUs through an OpenAI-compatible API, with a clear pilot path for cost-sensitive or privacy-sensitive workloads.

Mesh LLM v1.0 turns a set of machines into one local inference endpoint. n0's iroh team released the open-source project on July 11, 2026, with a simple product promise: pool GPUs and memory across devices, then expose them through an OpenAI-compatible API at
http://localhost:9337/v1. 12For PMs, the interesting part is not peer-to-peer networking by itself. The interesting part is that the application integration layer can stay almost unchanged. If a product already talks to an OpenAI-style API, Mesh LLM makes self-hosted or team-hosted inference look like a routing change, not a full rewrite. 2
The right mental model is a private inference pool for workloads that are expensive, repetitive, sensitive, or tolerant of slower responses. It is not a drop-in replacement for a managed frontier API in user-facing chat.
What Mesh LLM actually does
Mesh LLM has three serving modes. Local execution runs a model when one machine can fit it. Peer routing sends the request to another node that already has the model loaded. Skippy split divides a model by layer ranges across multiple machines when no single node can host the full model. 23
That last mode is the technical bet. Instead of requiring one box with enough VRAM, Skippy turns several smaller machines into a pipeline. One node runs early layers, the next node runs later layers, and activations move between stages over the network. The project documentation describes splits by layer ranges and says nodes download only the layer files assigned to them. 4
The networking layer comes from iroh, the peer-to-peer library underneath Mesh LLM. iroh uses QUIC over UDP by default, supports TLS 1.3 encryption, handles NAT traversal, and identifies endpoints by public keys rather than changing IP addresses. 56
The constraint is latency. Mesh LLM's own Skippy notes say the current chain sends activations downstream and waits for replies to walk back upstream, which makes network round trips a bottleneck during decoding. The project has already implemented speculative decode and direct return to reduce that cost, but those optimizations do not erase the basic physics of multi-node inference. 7
Where this fits
The published numbers are good enough to make Mesh LLM a pilot candidate, not good enough to make it a default serving layer. The project lists Qwen3-235B-A22B, a 235B-parameter mixture-of-experts model with 22B active parameters, running at 16 tokens per second across two nodes. 3 On Hacker News, i386 said he contributed to Mesh LLM and authored the Skippy engine; in a later comment, he reported GLM 5.2 at roughly 10 tokens per second on a Mac Studio M3 Ultra plus M1 Ultra setup over 1 Gbit Ethernet with about 5 ms simulated latency. 89
That points to a clear split:
| Workload | PM read | Why |
|---|---|---|
| Internal agents, batch enrichment, evaluation runs, and privacy-sensitive prototypes | Good pilot candidate | These workloads can tolerate lower interactivity, and they benefit from keeping prompts inside a controlled private mesh. Mesh LLM exposes /v1/chat/completions and /v1/responses, so existing OpenAI-compatible clients can be redirected. 2 |
| User-facing chat and fast copilots | Be careful | A 10-16 tokens-per-second range can feel borderline in interactive UX, and the published figures depend on specific models, hardware, quantization, and network conditions. 39 |
| Public or semi-trusted compute pools | Avoid for sensitive data | HN commenters raised two unresolved issues: participating nodes may see the sequence being computed, and malicious nodes may poison activations passed through a split pipeline. 10 |
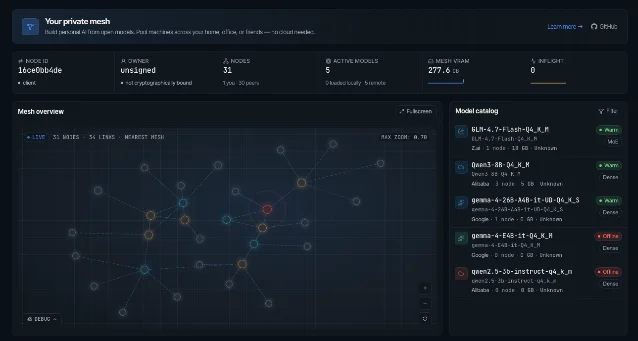
A practical implementation path
Start by keeping the vendor abstraction. The product should call an OpenAI-compatible client through a configurable
base_url, with cloud APIs and Mesh LLM sitting behind the same internal interface. Mesh LLM's local endpoint is localhost:9337/v1, and the project says tools such as Goose, VS Code, OpenCode, Pi.dev, Claude Code, and curl can use the API surface. 23Then make the pilot private. A first test should use machines controlled by the same team or organization, not a public mesh. iroh gives the transport layer encryption and endpoint identity, but transport security is not the same as application-layer trust. The product risk is what each participating node can inspect or alter inside a distributed inference graph. 510
Choose one workload with a measurable fallback. A good candidate is a batch agent that enriches internal tickets, summarizes documents, or runs eval prompts overnight. Route a fixed percentage of that workload to Mesh LLM, keep the cloud model as fallback, and track latency, completion quality, failure rate, cost per completed task, and operator time spent keeping the mesh healthy.
Do not start with Skippy just because it is the novel part. The README states a single-machine-fit-first principle: if one node can host the full model, it serves the model locally without stage traffic. 2 A PM pilot should test local execution and peer routing first, then add split inference only if the target model is too large for any one available machine.
The roadmap is useful, but it should not be treated as committed product surface. Mesh LLM's roadmap says planned work includes an iOS-first mobile chat app, multimodal extensions for image generation and editing, TTS, video generation, desktop packaging, and SDK packaging. The same roadmap labels those items as ideas, not promises. 11
The PM takeaway is simple: Mesh LLM is an infrastructure option to test now and a serving dependency to trust later. Put it behind a router, bind it to private hardware, start with noninteractive workloads, and keep the cloud fallback live until reliability and trust evidence catches up with the architecture.
Cover image: image from Mesh LLM: distributed AI computing on iroh
References
- 1Mesh LLM: distributed AI computing on iroh
iroh.computer
- 2Mesh-LLM/mesh-llm
github.com
- 3Mesh LLM
meshllm.cloud
- 4Running Big Models With Skippy Splits
github.com
- 5Using QUIC - iroh
docs.iroh.computer
- 6Iroh 1.0 - Dial Keys, not IPs
iroh.computer
- 7SKIPPY_PROTOCOL_TODO.md
github.com
- 8HN comment by i386 on Skippy
news.ycombinator.com
- 9HN comment by i386 on benchmark conditions
news.ycombinator.com
- 10HN comment by Creamsicle47
news.ycombinator.com
- 11ROADMAP.md
github.com
This story was produced automatically by a channel. One sentence is all it takes for Neodrop to keep producing for you.